
A boutique hotel group wants a GitHub automation that reads new guest-feedback issues, categorizes maintenance versus service themes, and posts a brief empathetic acknowledgment in consistent brand voice without inventing details. Which prompt and model configuration should the builder choose to meet those consistency needs?
Select an answer to reveal the explanation.
Short Explanation
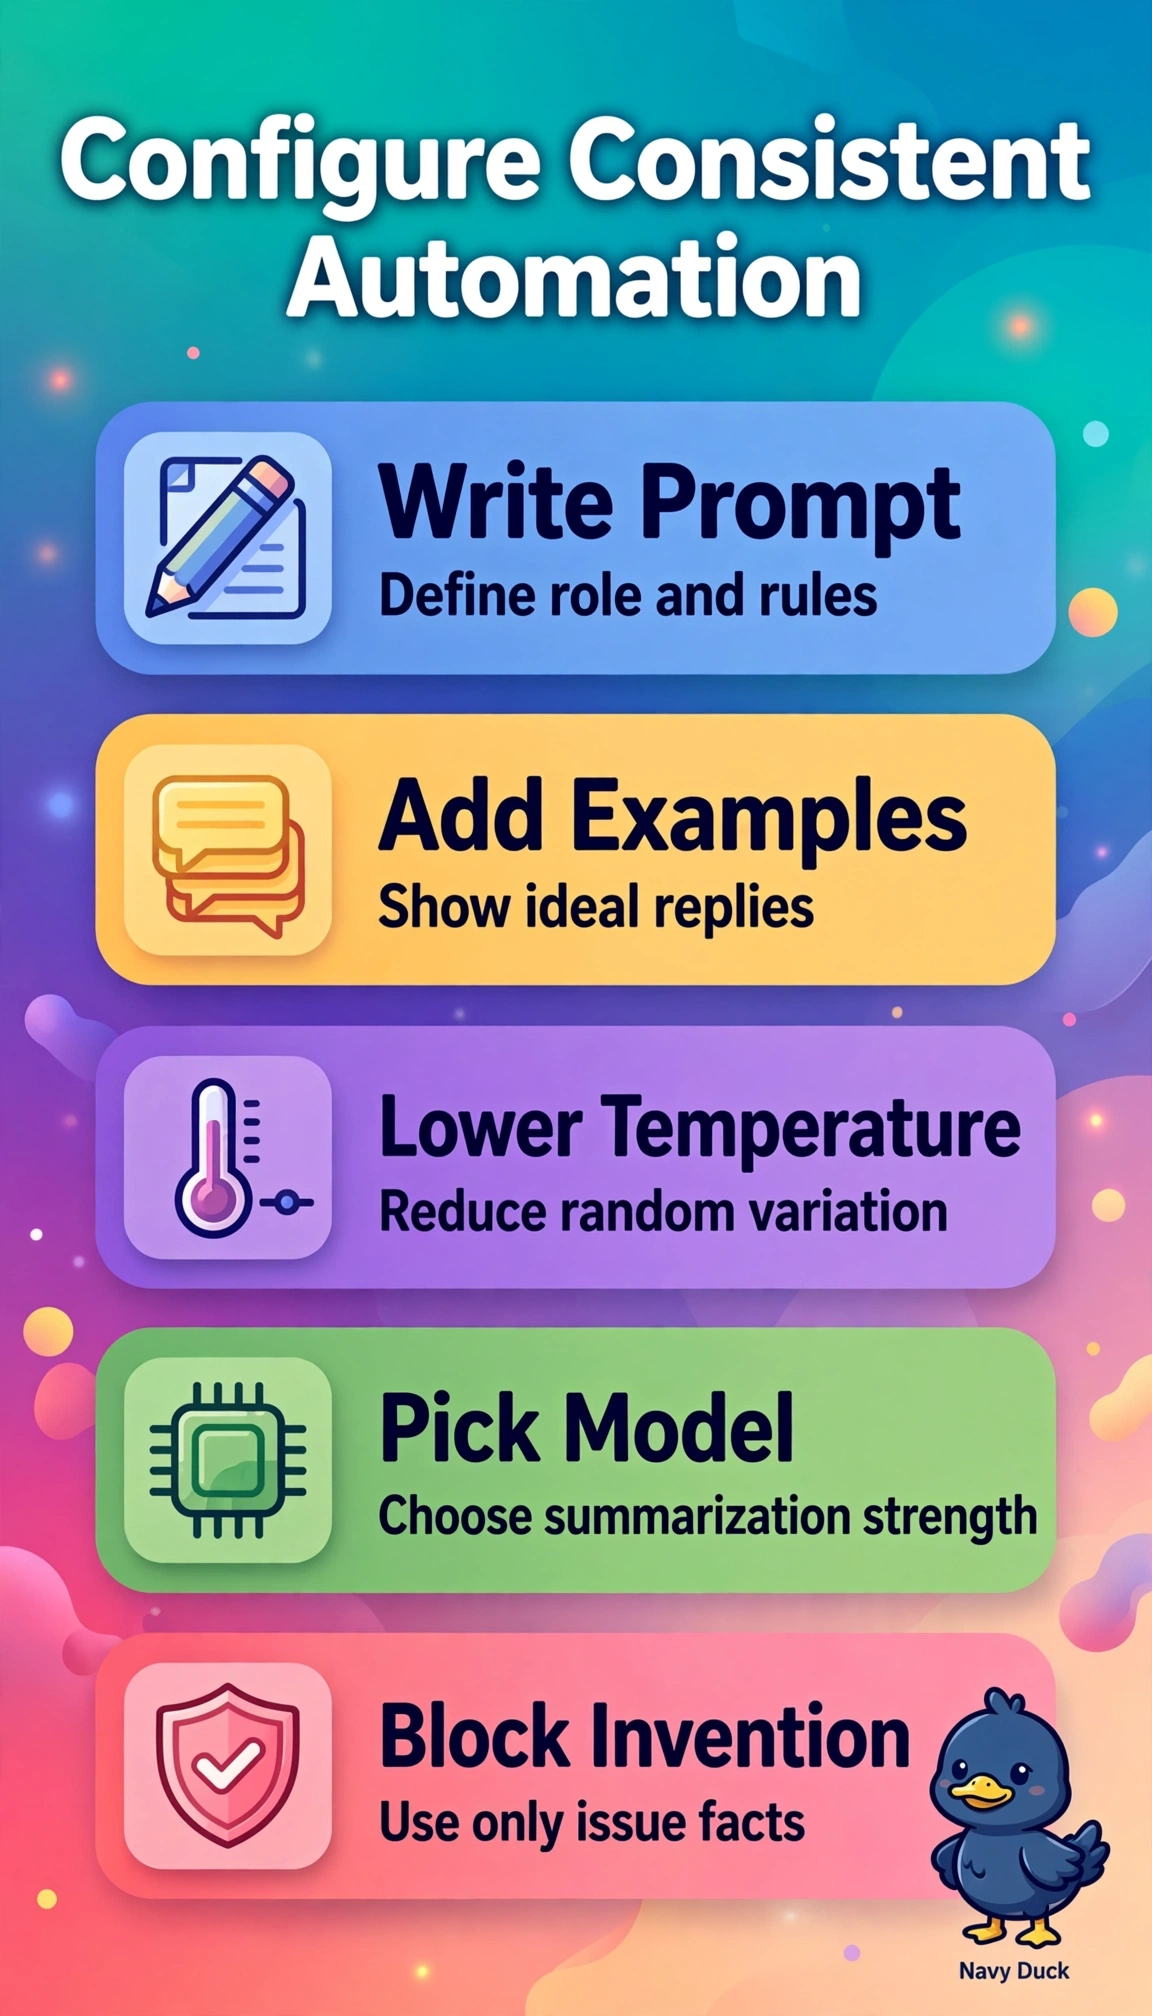
You're running a front desk, not improv night, so consistency beats flair here. A clear system prompt with examples and a low-creativity grounding keeps replies on-brand and stops the model from hallucinating extras.
Full Explanation
The boutique task demands grounded consistency across three behaviors: accurate maintenance versus service classification, brief empathetic acknowledgment, and stable brand voice without hallucination, which is why a focused system prompt with examples, low creativity setting, and a capable summarization model fits best because instructions plus few-shot exemplars anchor tone and taxonomy, low temperature suppresses paraphrase drift, and a summarization-oriented model favors faithful condensation over invention. The neutral-tone low-temperature approach is operationally sound for helpdesk triage but fails the brand requirement by concept since consistent neutrality is not brand consistency and guest experience depends on recognizable voice. The few-shot brand-voiced approach with warmer sampling is widely used for personable marketing copy but fails the consistency requirement by concept because elevated sampling increases lexical and stylistic variance across identical inputs, undermining repeatable acknowledgments. The low-temperature brand-example approach that fills in likely stay details is common for enrichment but fails the grounding requirement by concept because inferring unstated dates, rooms, or staff actions creates hallucination risk and violates the instruction to avoid inventing details. An exam caveat is to distinguish summarization and classification controls from creative generation controls and to read whether consistency, voice, or faithfulness is the decisive constraint rather than assuming any capable model suffices. A practical check is to run a fixed set of unseen feedback issues through the workflow multiple times and verify identical theme labels, preserved brand phrasing, brevity, empathy, and zero unsupported specifics before enabling automatic posting.