
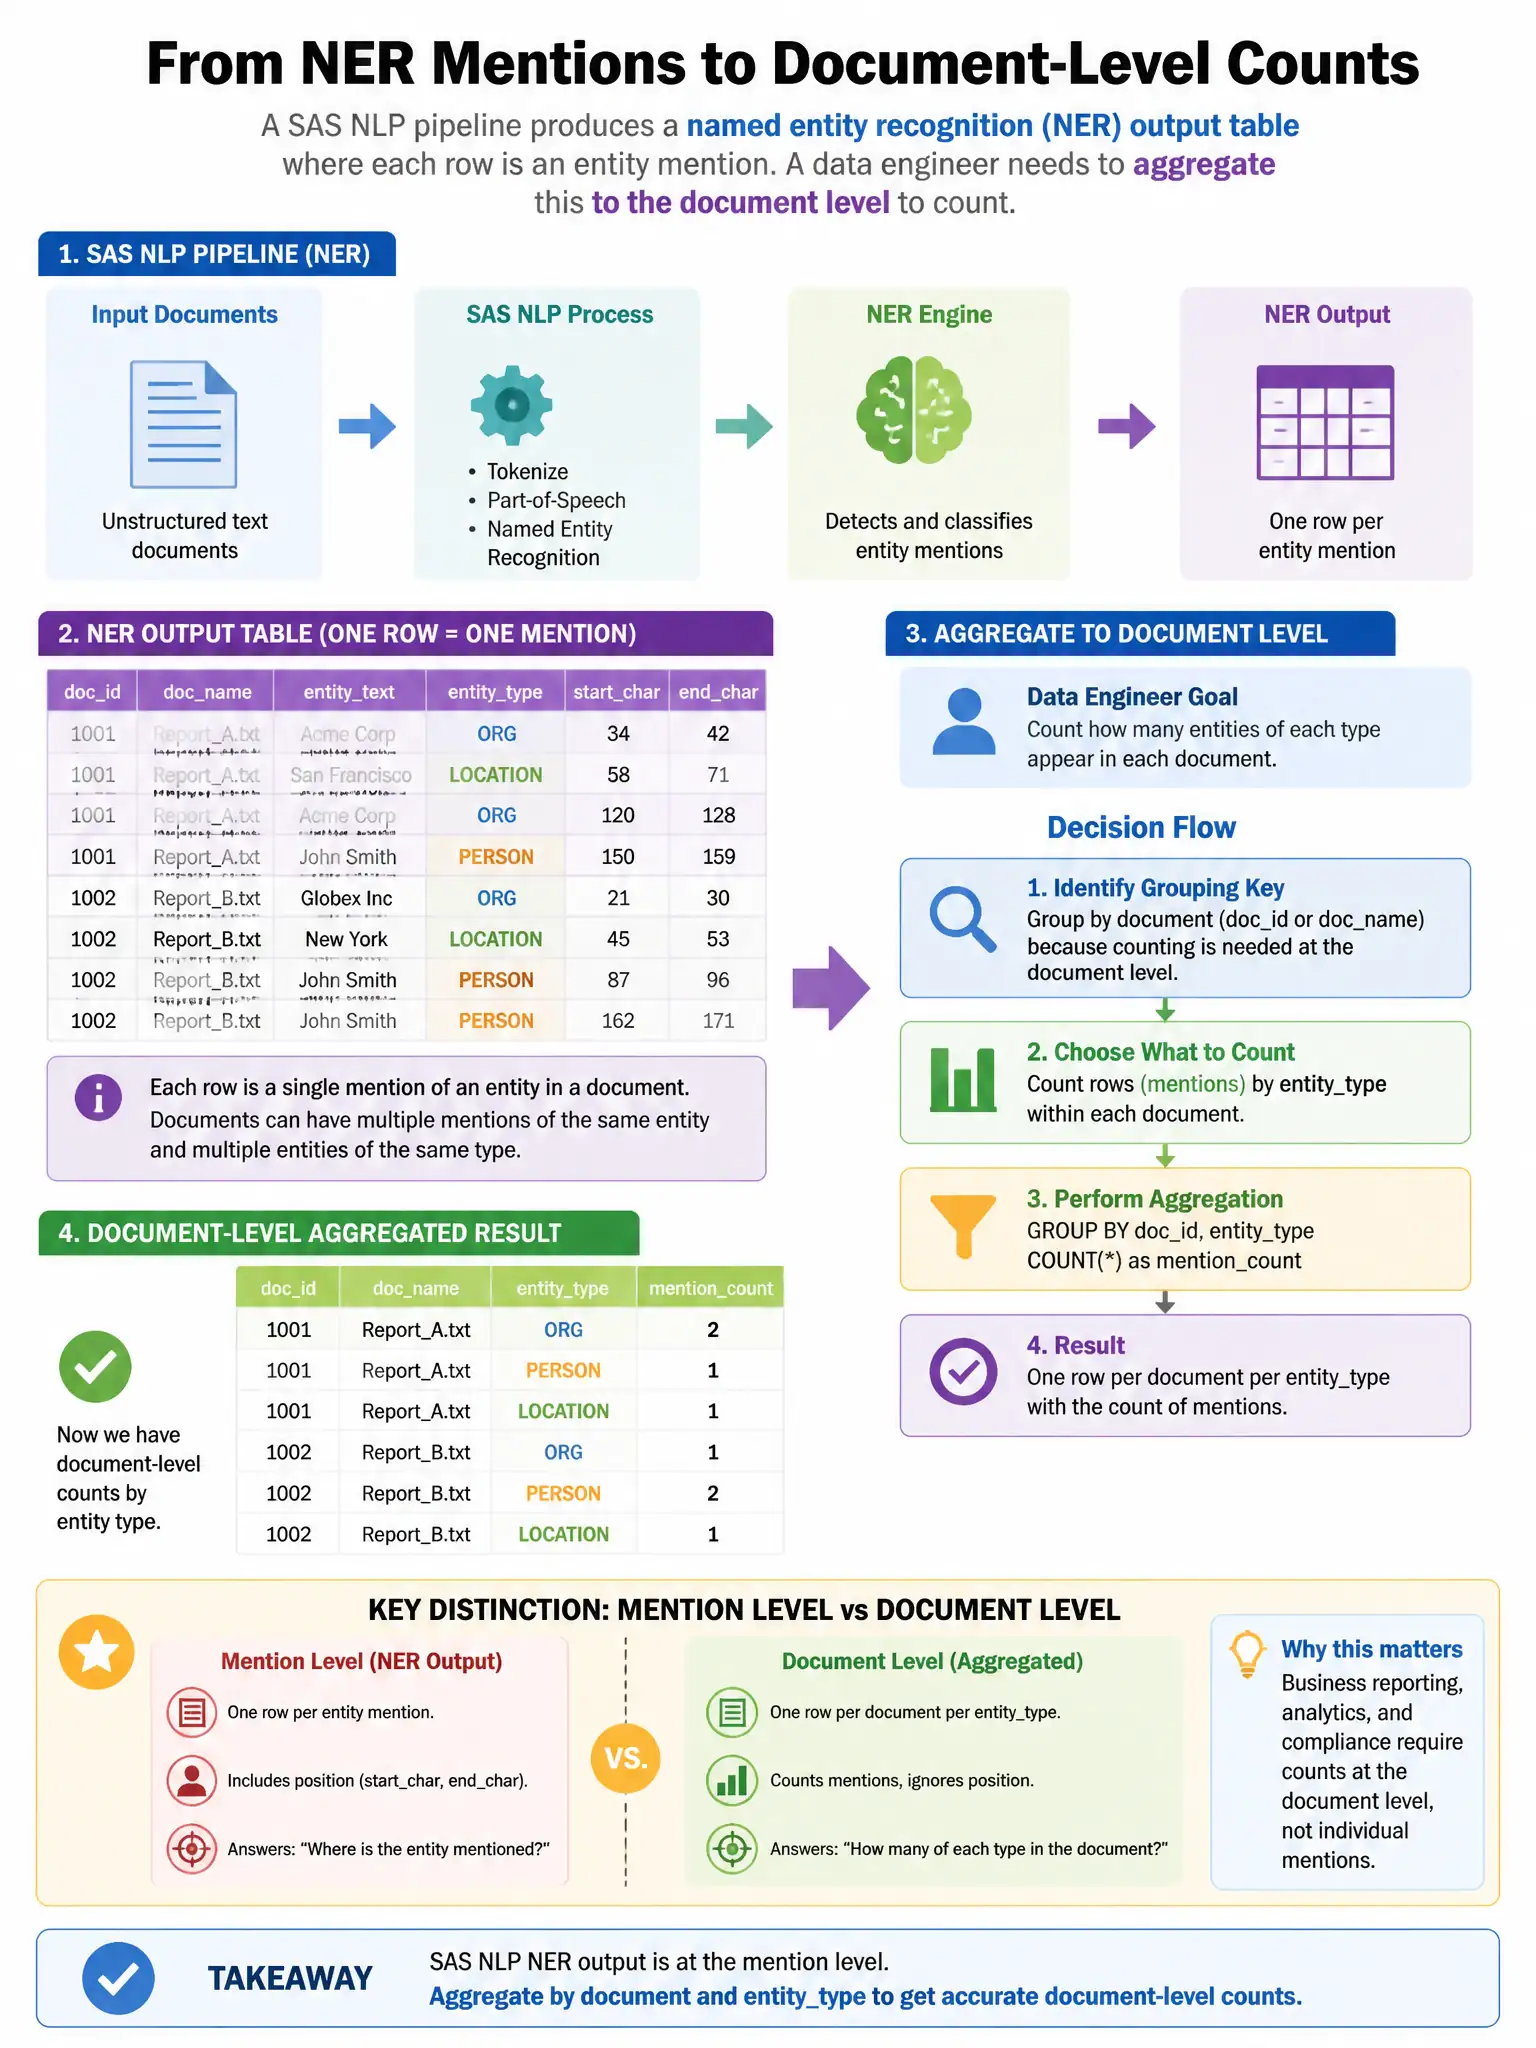
A SAS NLP pipeline produces a named entity recognition (NER) output table where each row is an entity mention. A data engineer needs to aggregate this to the document level to count how many PERSON entities appear per document. Which SAS step accomplishes this most directly?
Select an answer to reveal the explanation.
Short Explanation
Here's the deal — you want the PROC SQL step that filters to PERSON, groups by doc_id, and counts rows, because that gives you a clean document-level count directly. The cross-tab, transpose, and means approaches either change the shape or can't count a character entity type the way you need.
Full Explanation
The PROC SQL step is correct because it uses WHERE entity_type='PERSON', GROUP BY doc_id, and COUNT() to directly produce a document-level count of PERSON entity mentions. The PROC FREQ option with a TABLE entity_typedoc_id statement would produce a cross-tabulation but not a clean per-document count filtered to one entity type. The PROC TRANSPOSE option pivoting the entity type column into separate columns per document would pivot entity types across columns, which is a different output structure. The PROC MEANS option with CLASS=doc_id and VAR=entity_type to count occurrences is wrong; PROC MEANS computes numeric statistics, entity_type is character, and COUNT in this context requires PROC FREQ or PROC SQL.