
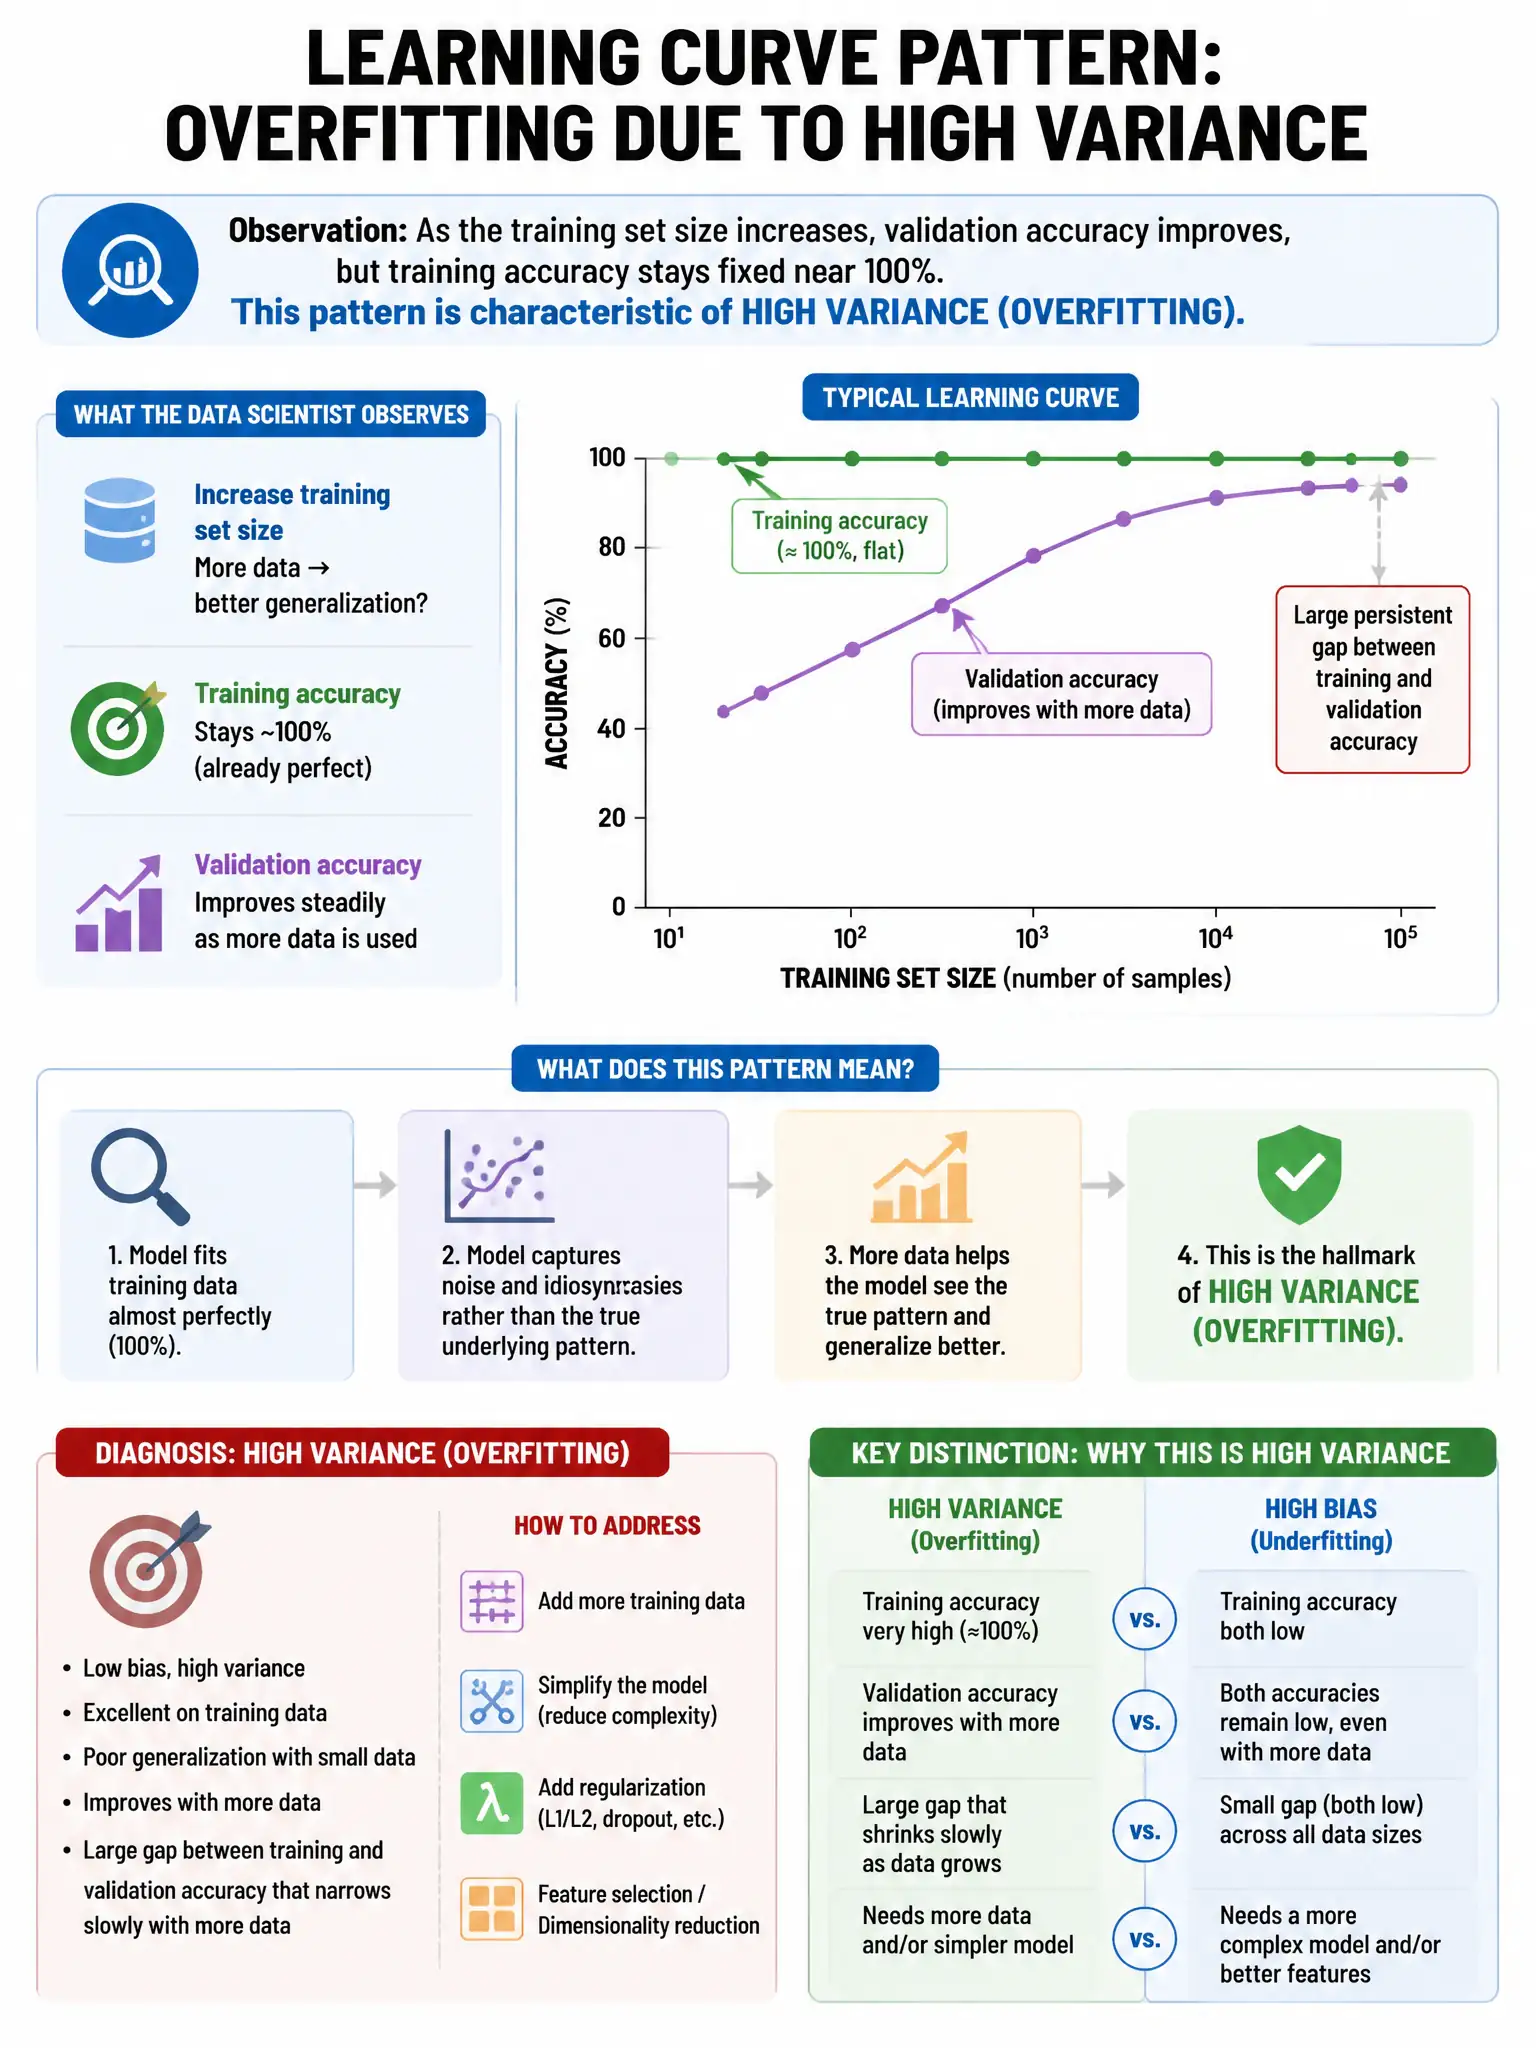
A data scientist observes that increasing training set size improves validation accuracy but training accuracy stays fixed near 100%. This learning curve pattern is characteristic of which condition?
Select an answer to reveal the explanation.
Short Explanation
Here's the deal — you're seeing high variance (overfitting) because training accuracy stays pinned at 100% while validation accuracy keeps improving as you add data. The model is memorizing the training set, and more data helps validation catch up.
Full Explanation
The high variance (overfitting) condition is correct because training accuracy fixed at 100% while validation accuracy improves with more data is the signature of high variance. The model is memorizing training data; more data helps validation catch up. The high bias (underfitting) condition would show both training and validation error plateauing at a high value. The optimal fit condition would show both curves converging at a low value. The label noise condition would cause training accuracy to degrade, not stay at 100%.