
In SAS Viya's gradient boosting implementation, a data scientist wants to prevent individual trees from memorizing specific training observations. Which combination of parameters directly implements this goal?
Select an answer to reveal the explanation.
Short Explanation
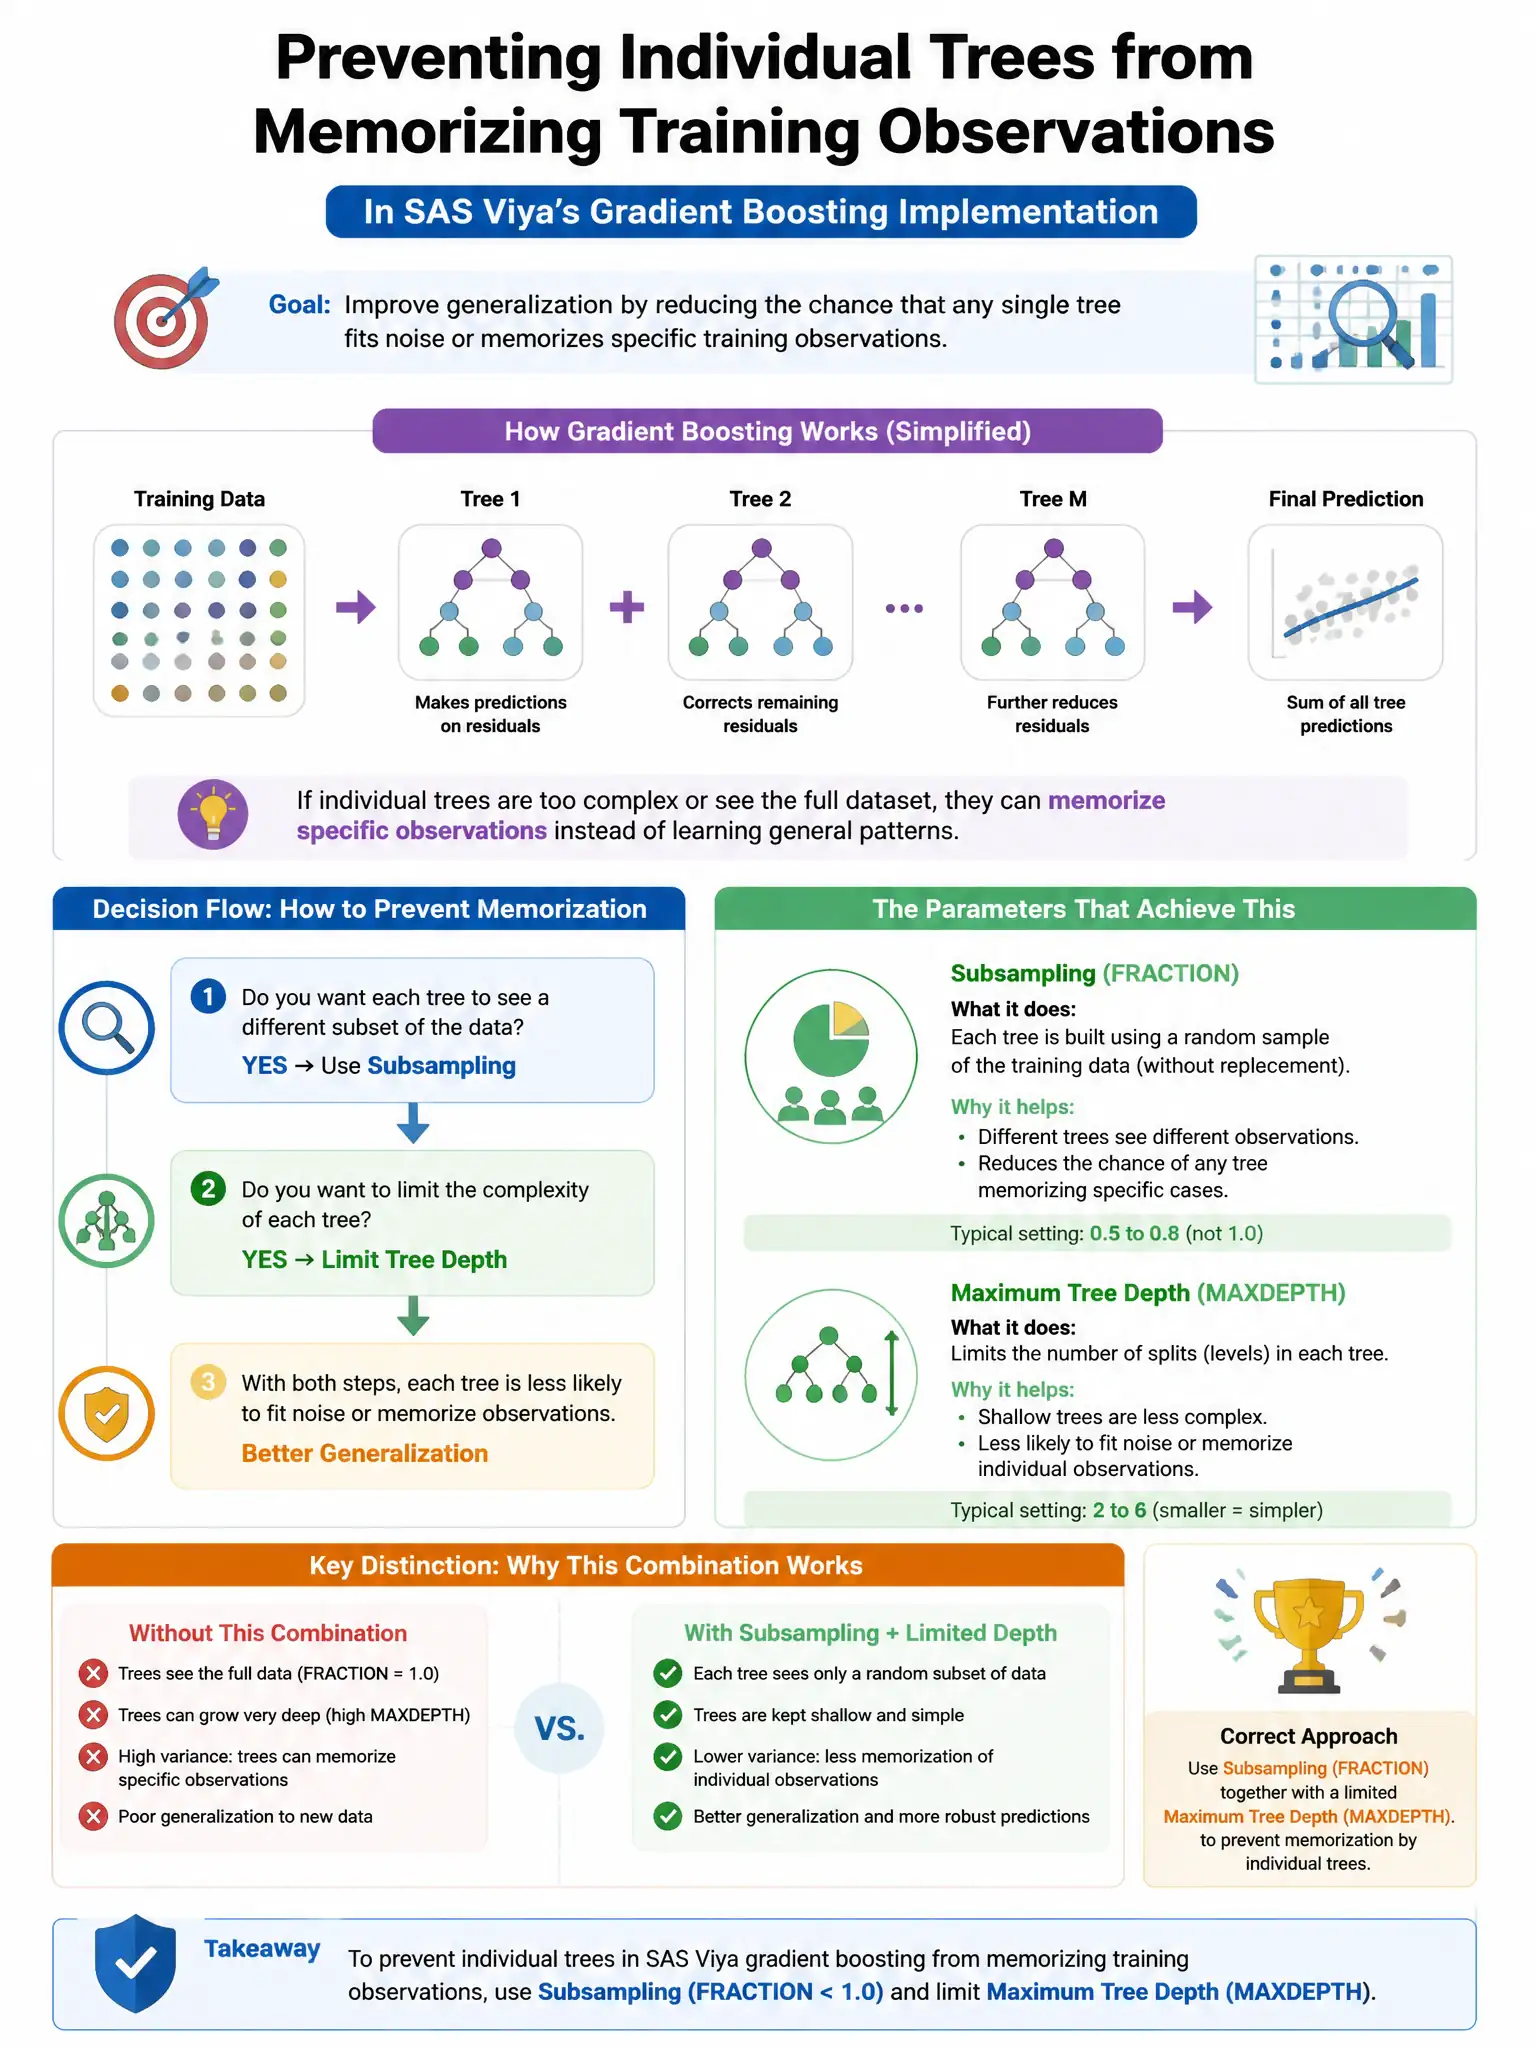
You want stochastic gradient boosting. Setting row and column subsampling below 1.0 makes each tree see only a random slice of observations and variables, so it can't memorize every training row. That randomness also keeps the ensemble diverse.
Full Explanation
The correct approach is to set SUBSAMPLERATE < 1.0 for row subsampling and COLSAMPLEBYTREE < 1.0 for column subsampling. This implements stochastic gradient boosting: each individual tree is trained on a random subset of observations and variables. That randomness prevents any single tree from seeing all training observations and memorizing their noise, while also increasing diversity across trees in the ensemble. Increasing NTREES= while decreasing LEARNINGRATE= slows overall convergence, but it does not add tree-level stochasticity or stop an individual tree from fitting specific observations. Increasing MAXDEPTH= allows trees to learn more complex patterns per observation, which increases the chance of memorizing observations. Setting LEARNINGRATE=1.0 removes shrinkage, so each tree fully corrects previous residuals and leads to aggressive overfitting.