
A data scientist uses SAS PROC TEXTMINE to analyze customer support tickets and identify common themes. Which output from PROC TEXTMINE best represents the dominant themes across documents?
Select an answer to reveal the explanation.
Short Explanation
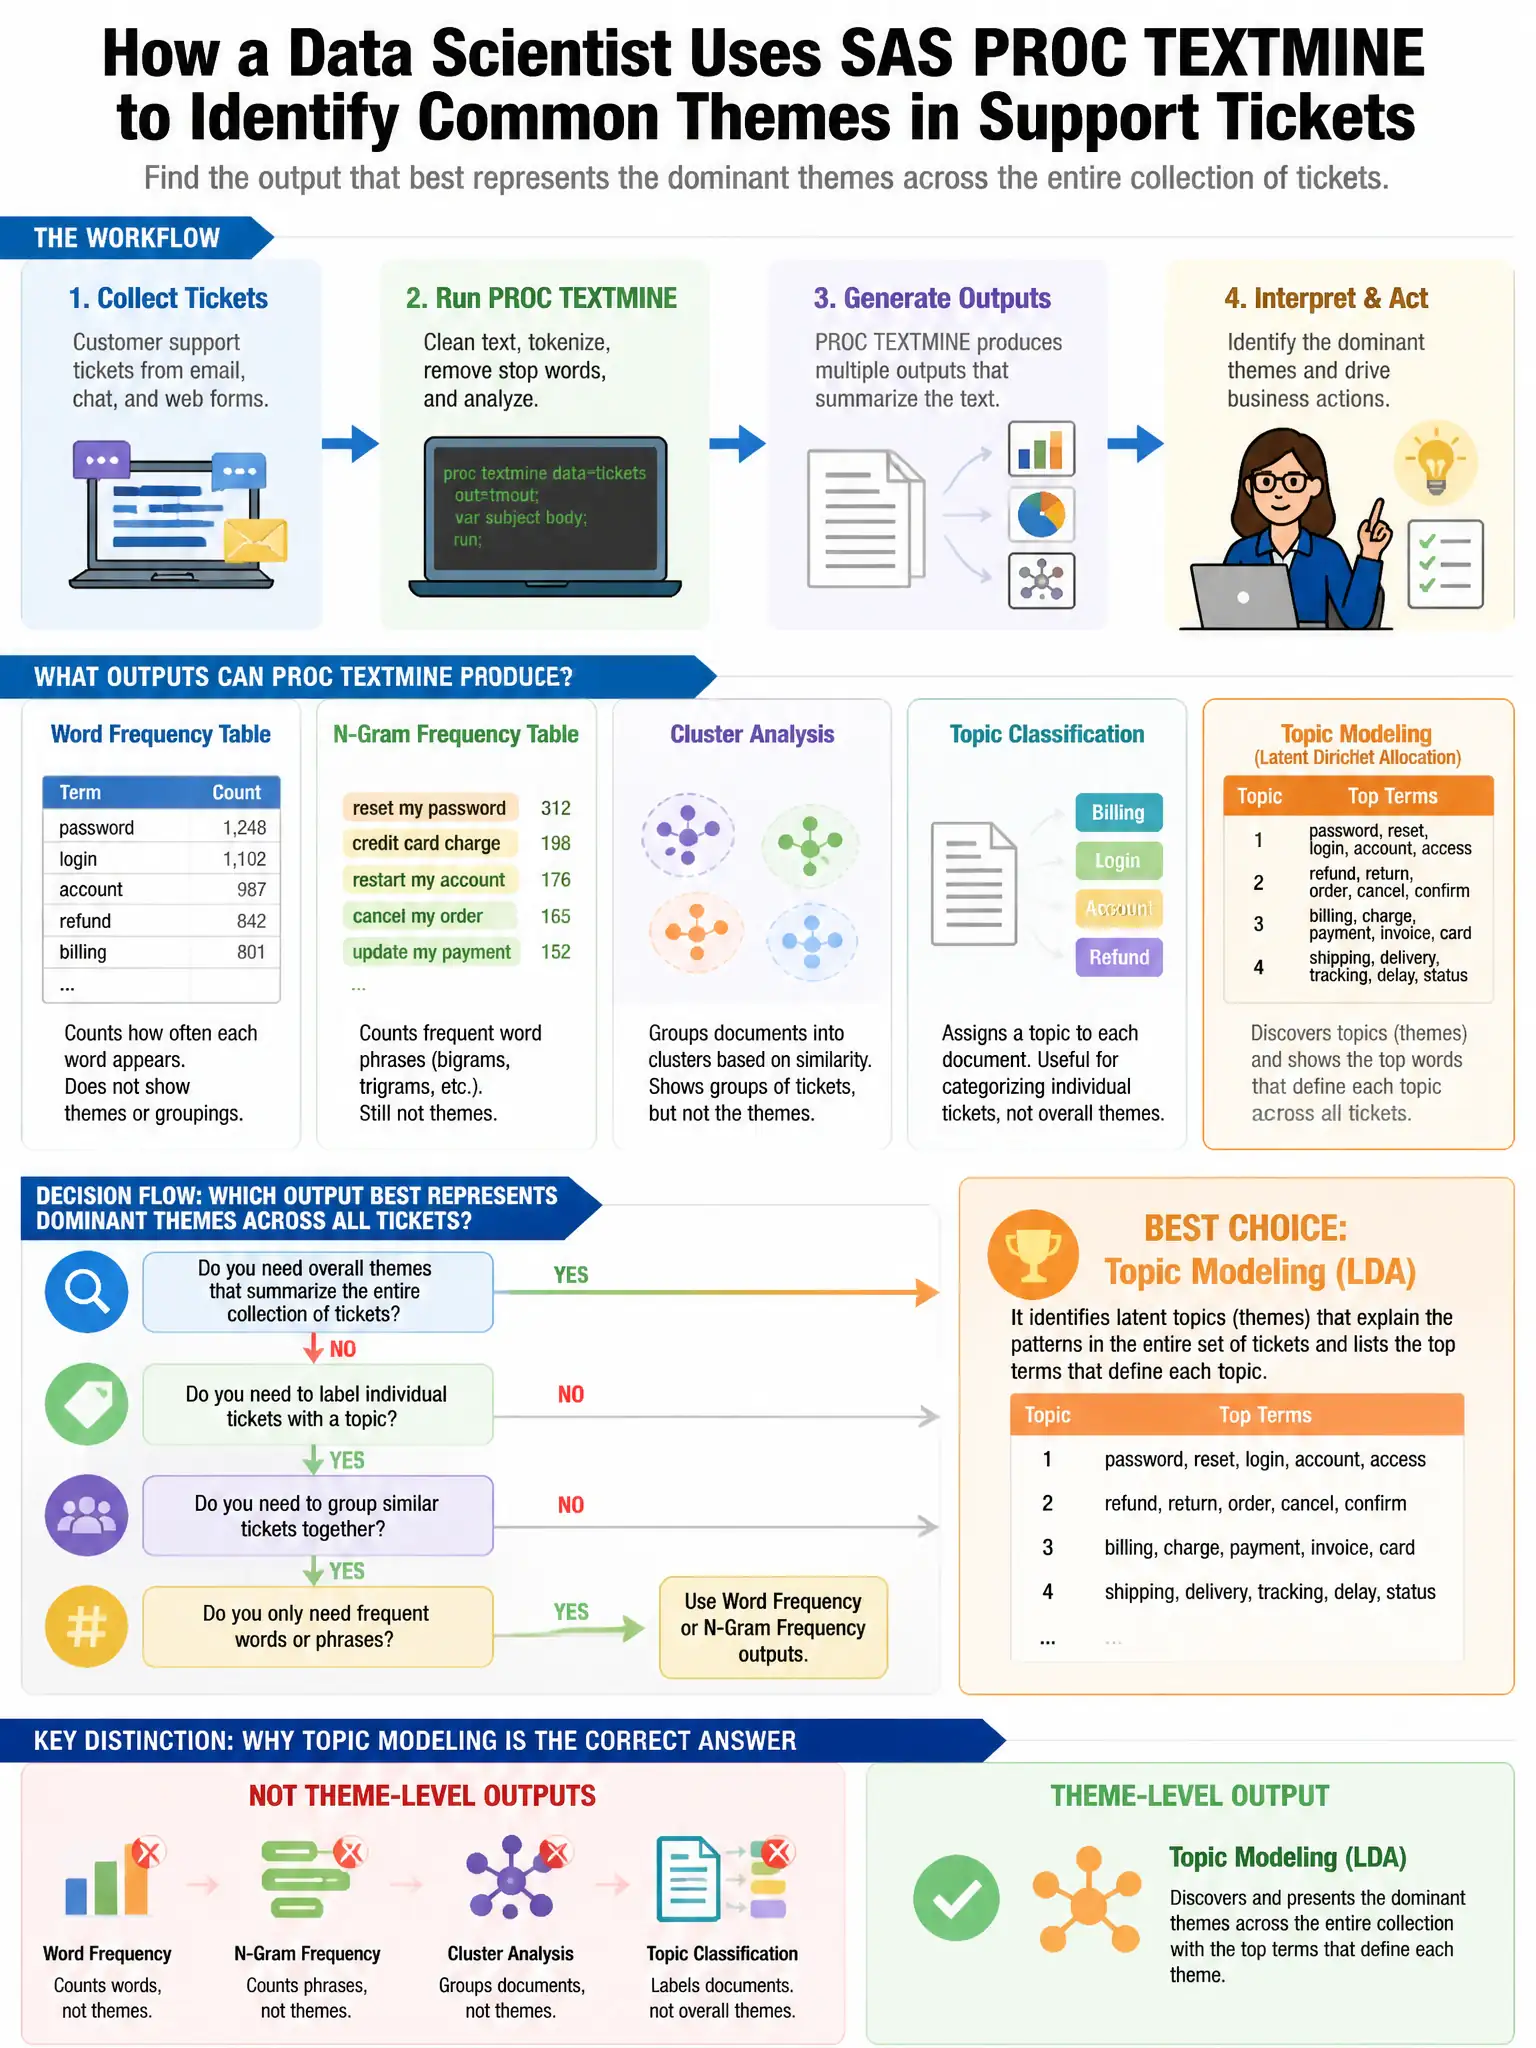
Here's the deal — you want the LDA topic-document probability matrix from the LDA statement's OUTTOPICS= dataset because it gives you the probabilities that tie topics to documents, directly showing the dominant themes across the support tickets. The other outputs just give you terms, stems, or coordinates, not the themes themselves.
Full Explanation
The LDA topic-document probability matrix from the LDA statement's OUTTOPICS= dataset is correct because the LDA statement in PROC TEXTMINE produces topic-term and topic-document probability distributions. The OUTTOPICS= dataset contains the dominant terms for each topic and their probabilities, directly representing the discovered themes across the document corpus. The OUTTERMS= dataset showing individual term frequencies across all documents is wrong because it shows raw term frequencies, not themes. The OUTPARSE= dataset showing the stemmed vocabulary is wrong because it shows the stemmed vocabulary list, not themes. The OUTSVD= dataset showing document coordinates in SVD space is wrong because it shows document coordinates in latent semantic space, which requires interpretation, unlike the direct LDA topic outputs.