
A SAS NLP pipeline applies PROC TEXTMINE to e-commerce product reviews to predict star ratings (1-5). After text parsing and SVD, the data scientist wants to train a gradient boosting classifier on the SVD features. What is the correct workflow?
Select an answer to reveal the explanation.
Short Explanation
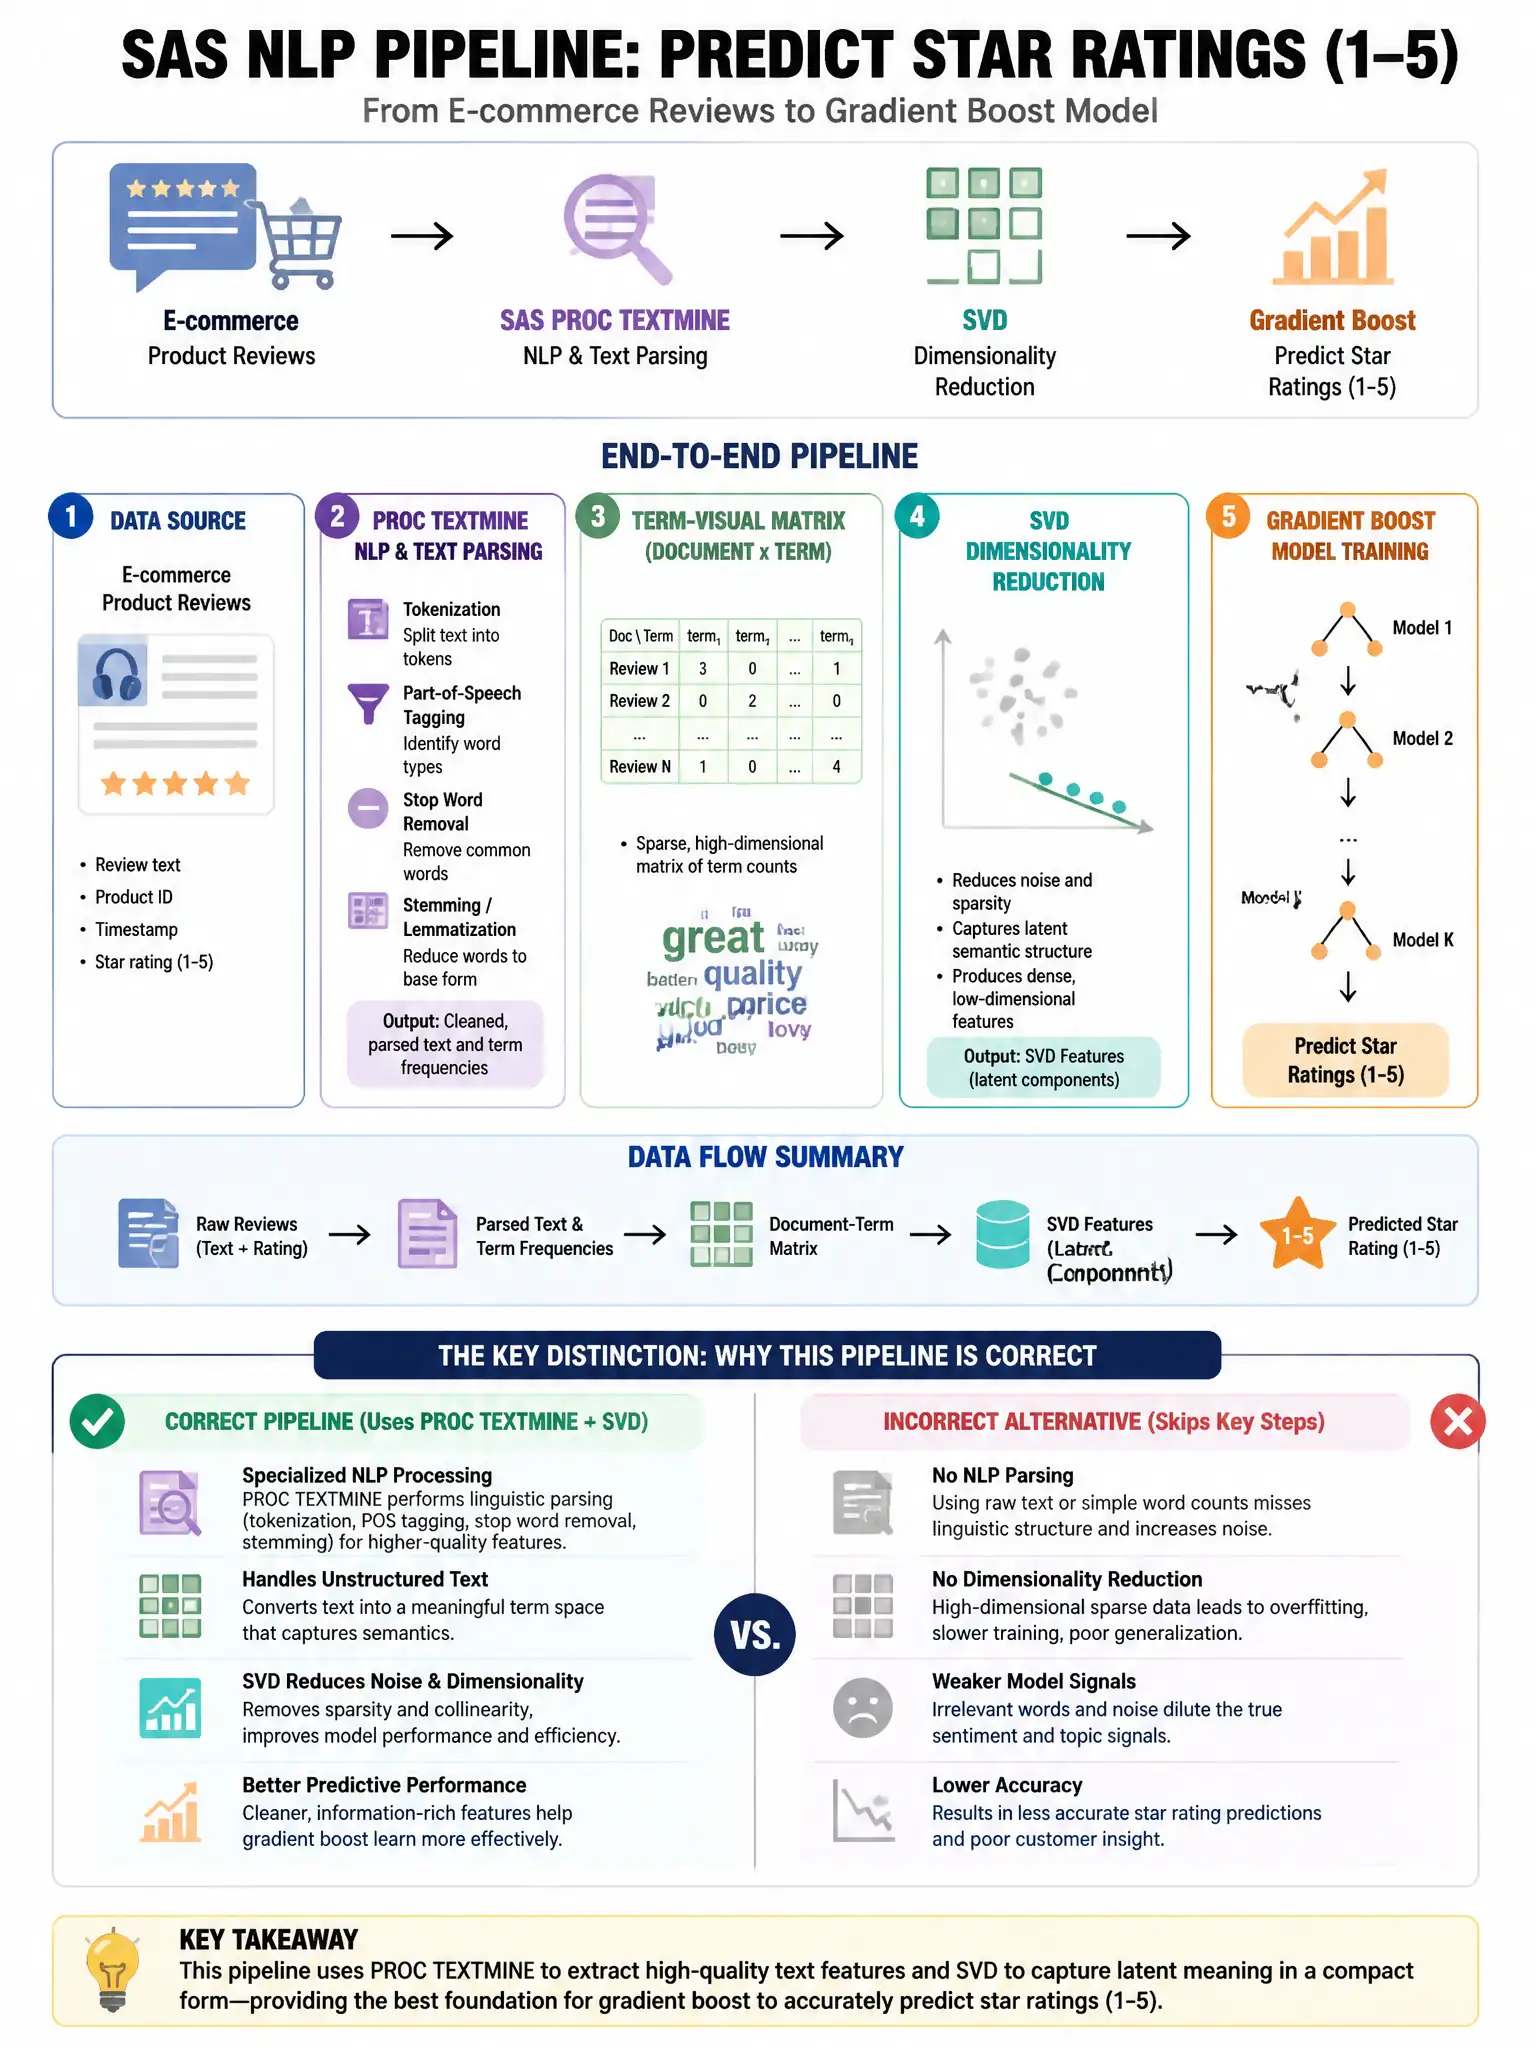
Here's the deal — you join the SVD scores to the star ratings, then train a gradient boosting or forest model on those numeric features. That's the standard SAS NLP-to-ML flow.
Full Explanation
The correct workflow is to join the SVD output dataset, containing document-level SVD scores, with the ratings table, then train PROC HPFOREST, the gbtreetrain CAS action, or PROC HPLOGISTIC on the numeric SVD features. PROC TEXTMINE turns text into numeric SVD dimensions, and the downstream classifier consumes those numbers. Passing raw text to PROC HPFOREST with a TEXT= option is wrong because that option does not exist. Using PROC HPNEURAL with a raw text input layer is wrong because it lacks such a layer. Exporting to Python and scikit-learn is not the SAS-native workflow described.