
In PROC TEXTMINE, after SVD is applied using SVDINIT, what are the resulting SVD dimensions used for in subsequent analysis steps?
Select an answer to reveal the explanation.
Short Explanation
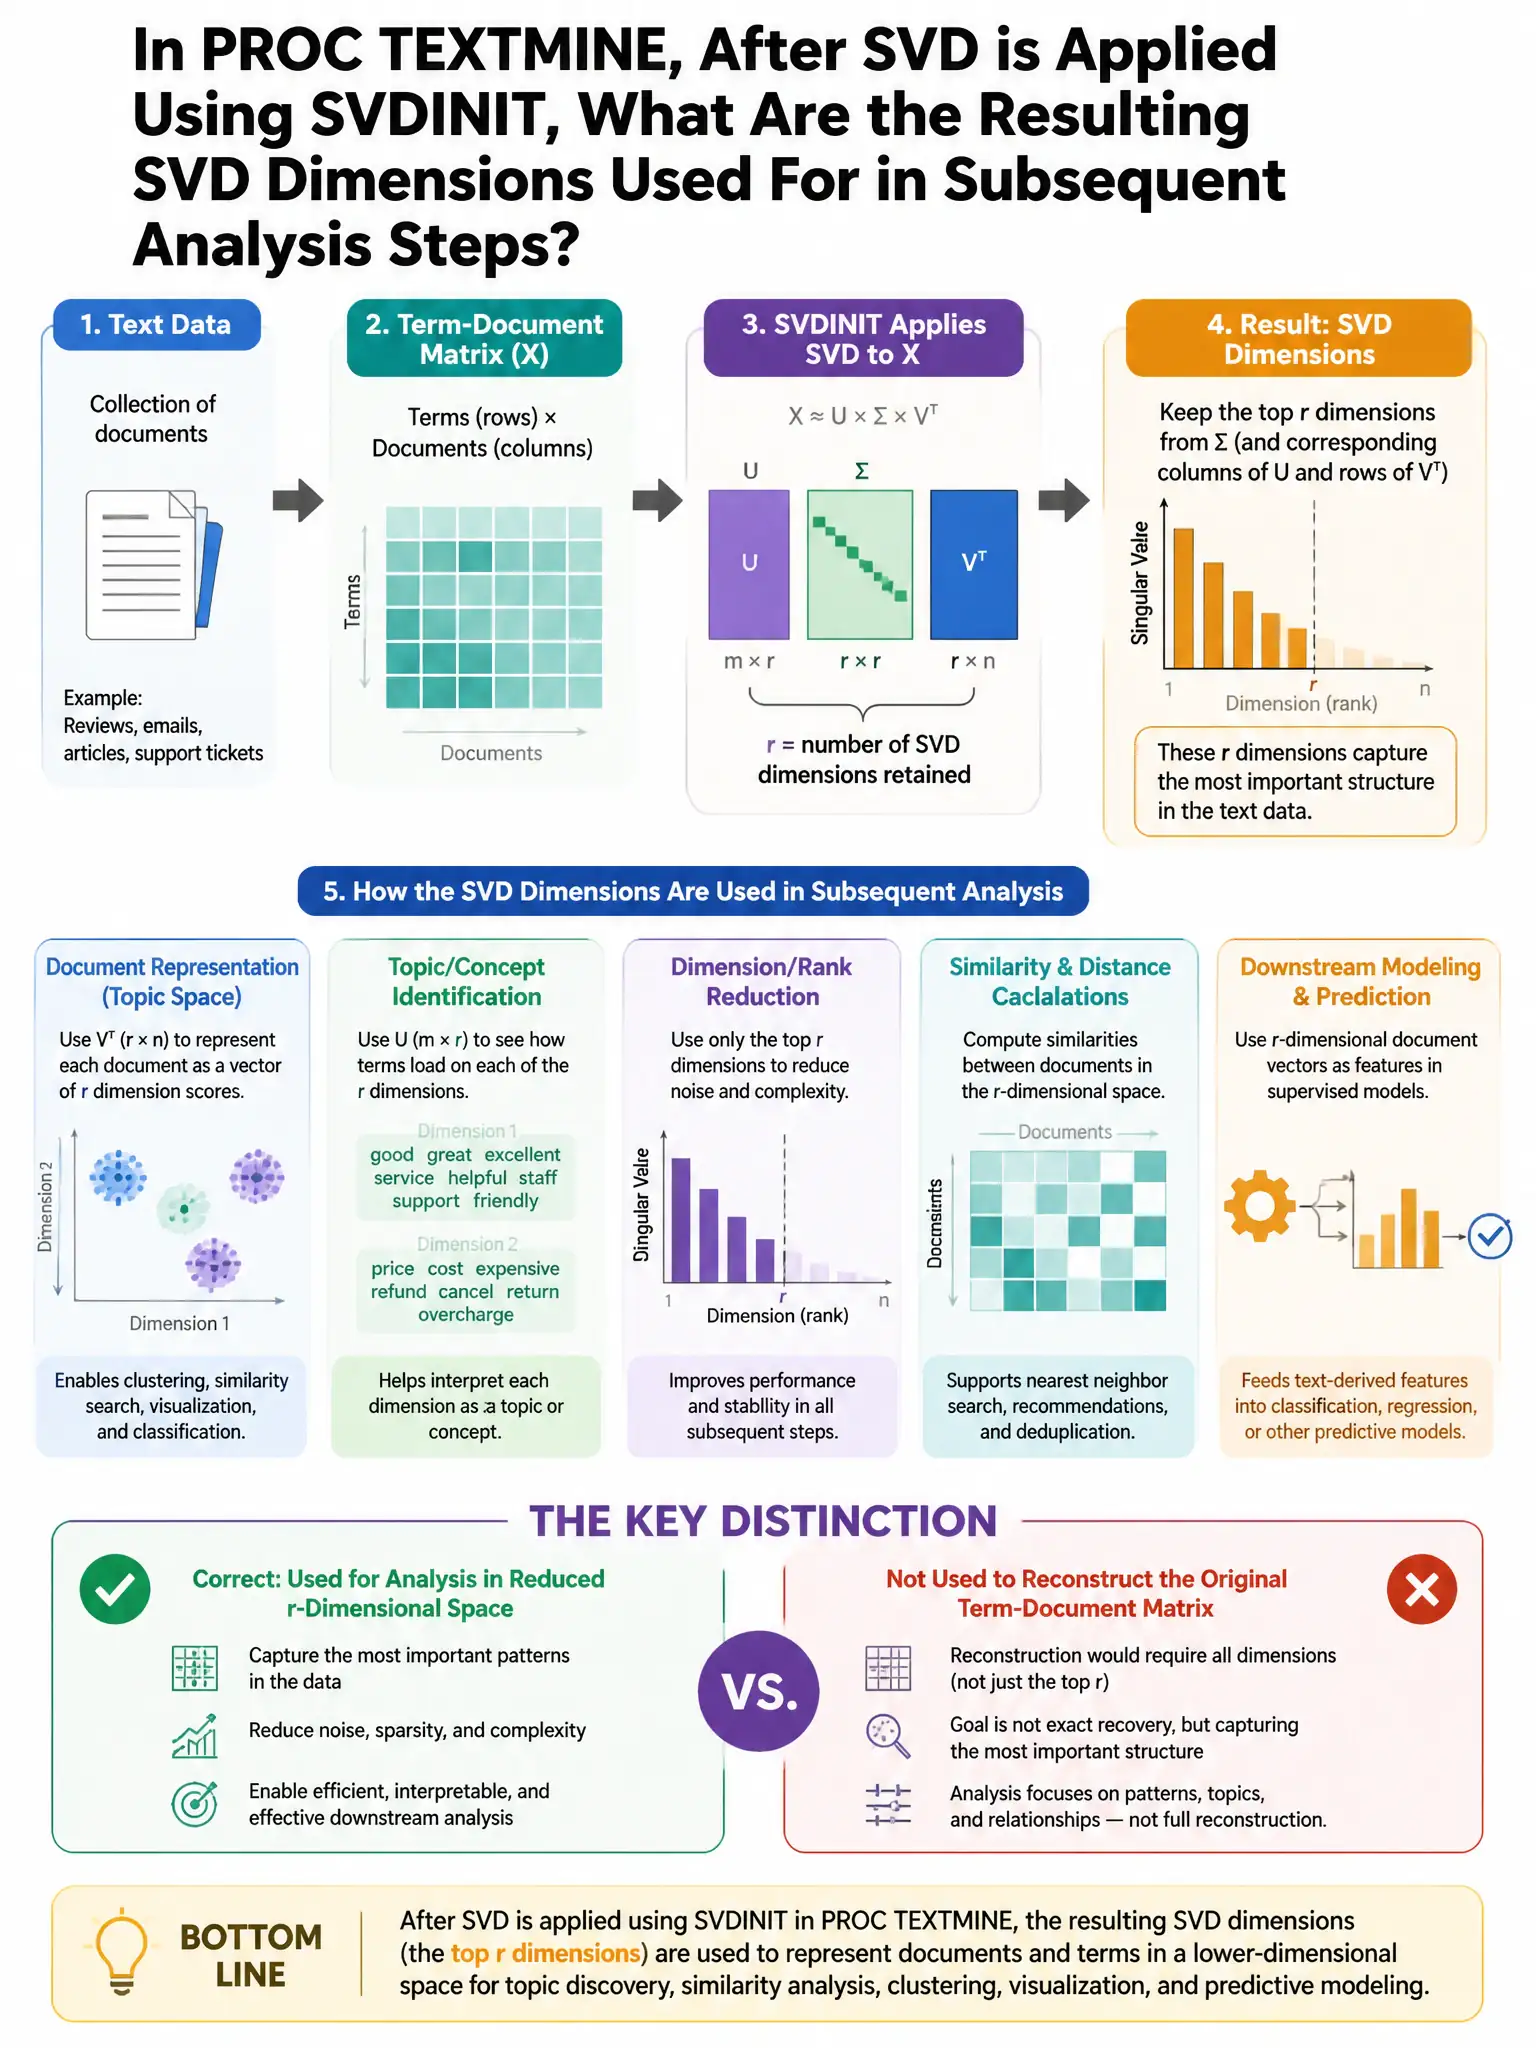
Here's the deal — you use the SVD dimensions as compact input features for clustering, classification, or topic modeling, replacing the huge sparse term-document matrix. They capture latent semantic patterns so downstream analysis works with dense low-dimensional data instead of raw text counts.
Full Explanation
The correct approach is to use the SVD dimensions as input features for clustering, classification, or topic modeling, replacing the high-dimensional term-document matrix. Singular Value Decomposition in PROC TEXTMINE reduces the high-dimensional sparse term-document matrix to a dense low-dimensional latent semantic space. These compact SVD dimensions capture underlying semantic patterns and are used as features for downstream tasks including clustering (e.g., PROC HPCLUS), classification, or as initialization for LDA topic modeling. The option about filtering out low-frequency terms is wrong because term filtering happens in the PARSE step, not from SVD dimensions. The option about computing the Flesch-Kincaid readability score for each document is unrelated to SVD dimensions. The option about using the SVD dimensions as random seeds for subsequent LDA topic initialization is wrong because SVD dimensions are semantic features, not random seeds.