
Tax FAQ validation perplexity drops sharply while BLEU on letter drafts barely moves. How should analysts read that?
Select an answer to reveal the explanation.
Short Explanation
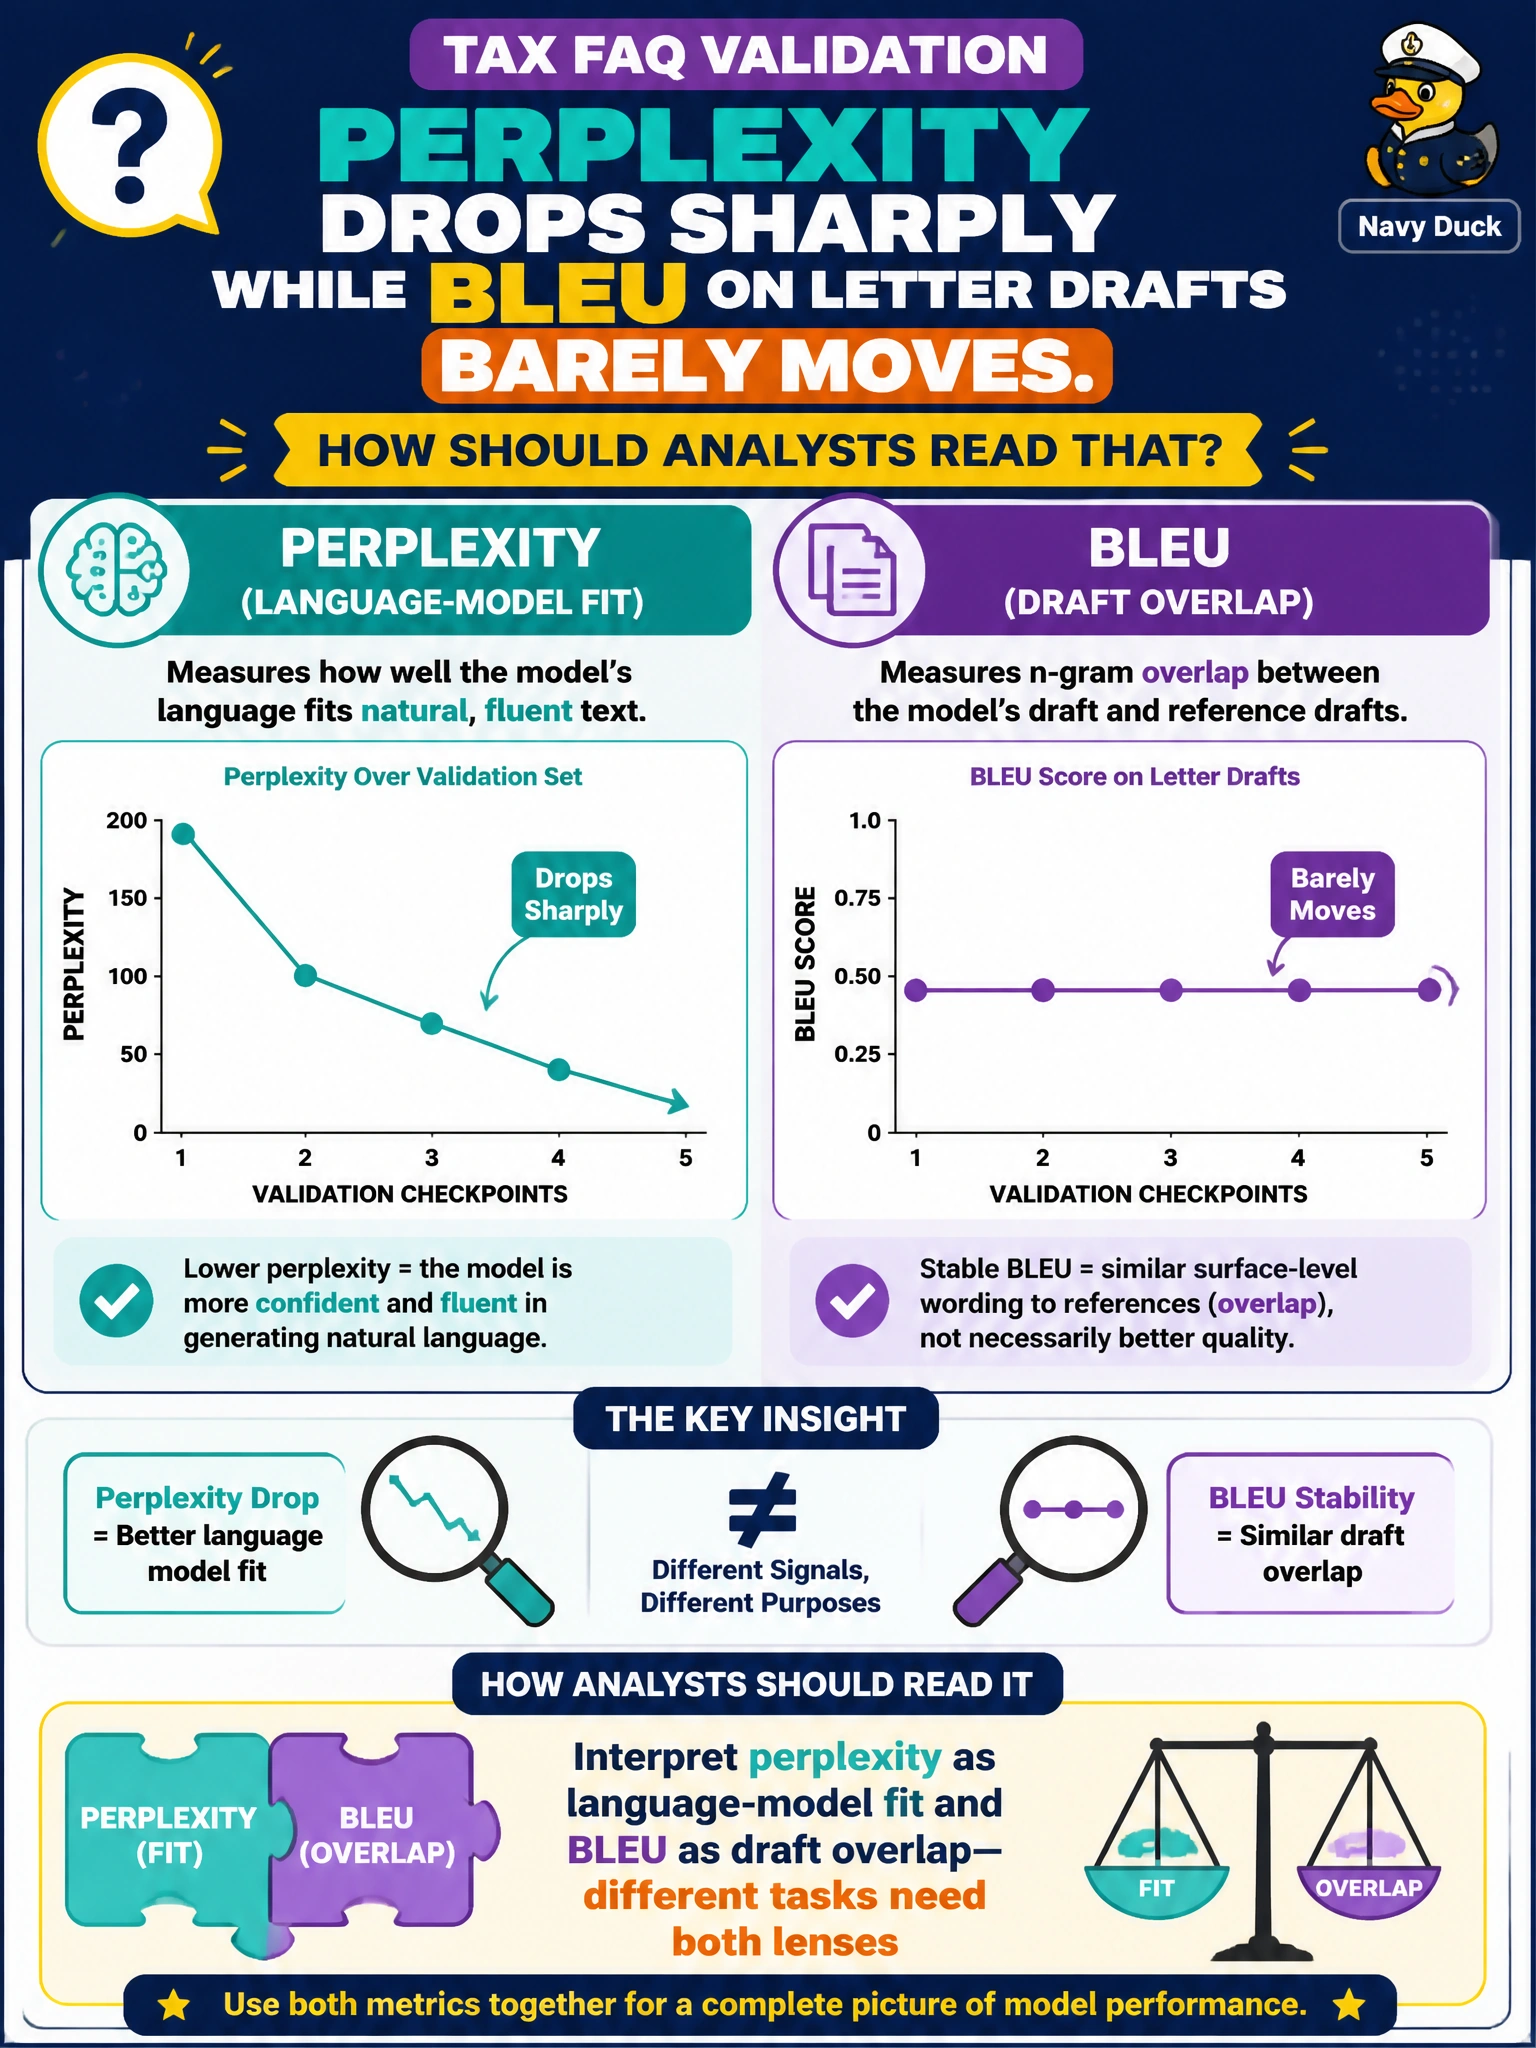
Perplexity is ‘how unsurprised is the model by the FAQ,’ BLEU is ‘how much does the letter overlap the gold draft.’ Different yardsticks—don’t pretend one number fixed both jobs.
Full Explanation
When tax FAQ validation perplexity drops sharply while BLEU on letter drafts barely moves, analysts should interpret the metrics as different lenses on different jobs: perplexity reflects language-model fit on FAQ text, while BLEU reflects n-gram overlap on letter drafts. A better LM fit on FAQs does not mean letter drafting is solved; civic evaluation must read each metric against its task rather than declaring global victory from one curve.
Concluding the letter draft model is fully solved because perplexity fell fails by concept: FAQ perplexity is not a letter-overlap certificate. Treating perplexity and BLEU as interchangeable for every civic task fails because they measure different quantities and suit different outputs. Ignoring both metrics and shipping the higher-temperature checkpoint fails as process: hotter decoding is not an evaluation reading and often hurts draft fidelity.
Exam caveat: if FAQ and letter drafting share one fine-tune, report both metrics every run so regressions on either task cannot hide behind a single flattering number. Operational check: dashboard FAQ perplexity and letter-draft BLEU (plus a human letter rubric sample) side by side; promote only when the task you intend to ship actually improved on its own metric.