
City multi-GPU training stalls on IO. Magnum IO GPUDirect Storage to the parallel filesystem is misconfigured. What should ops fix?
Select an answer to reveal the explanation.
Short Explanation
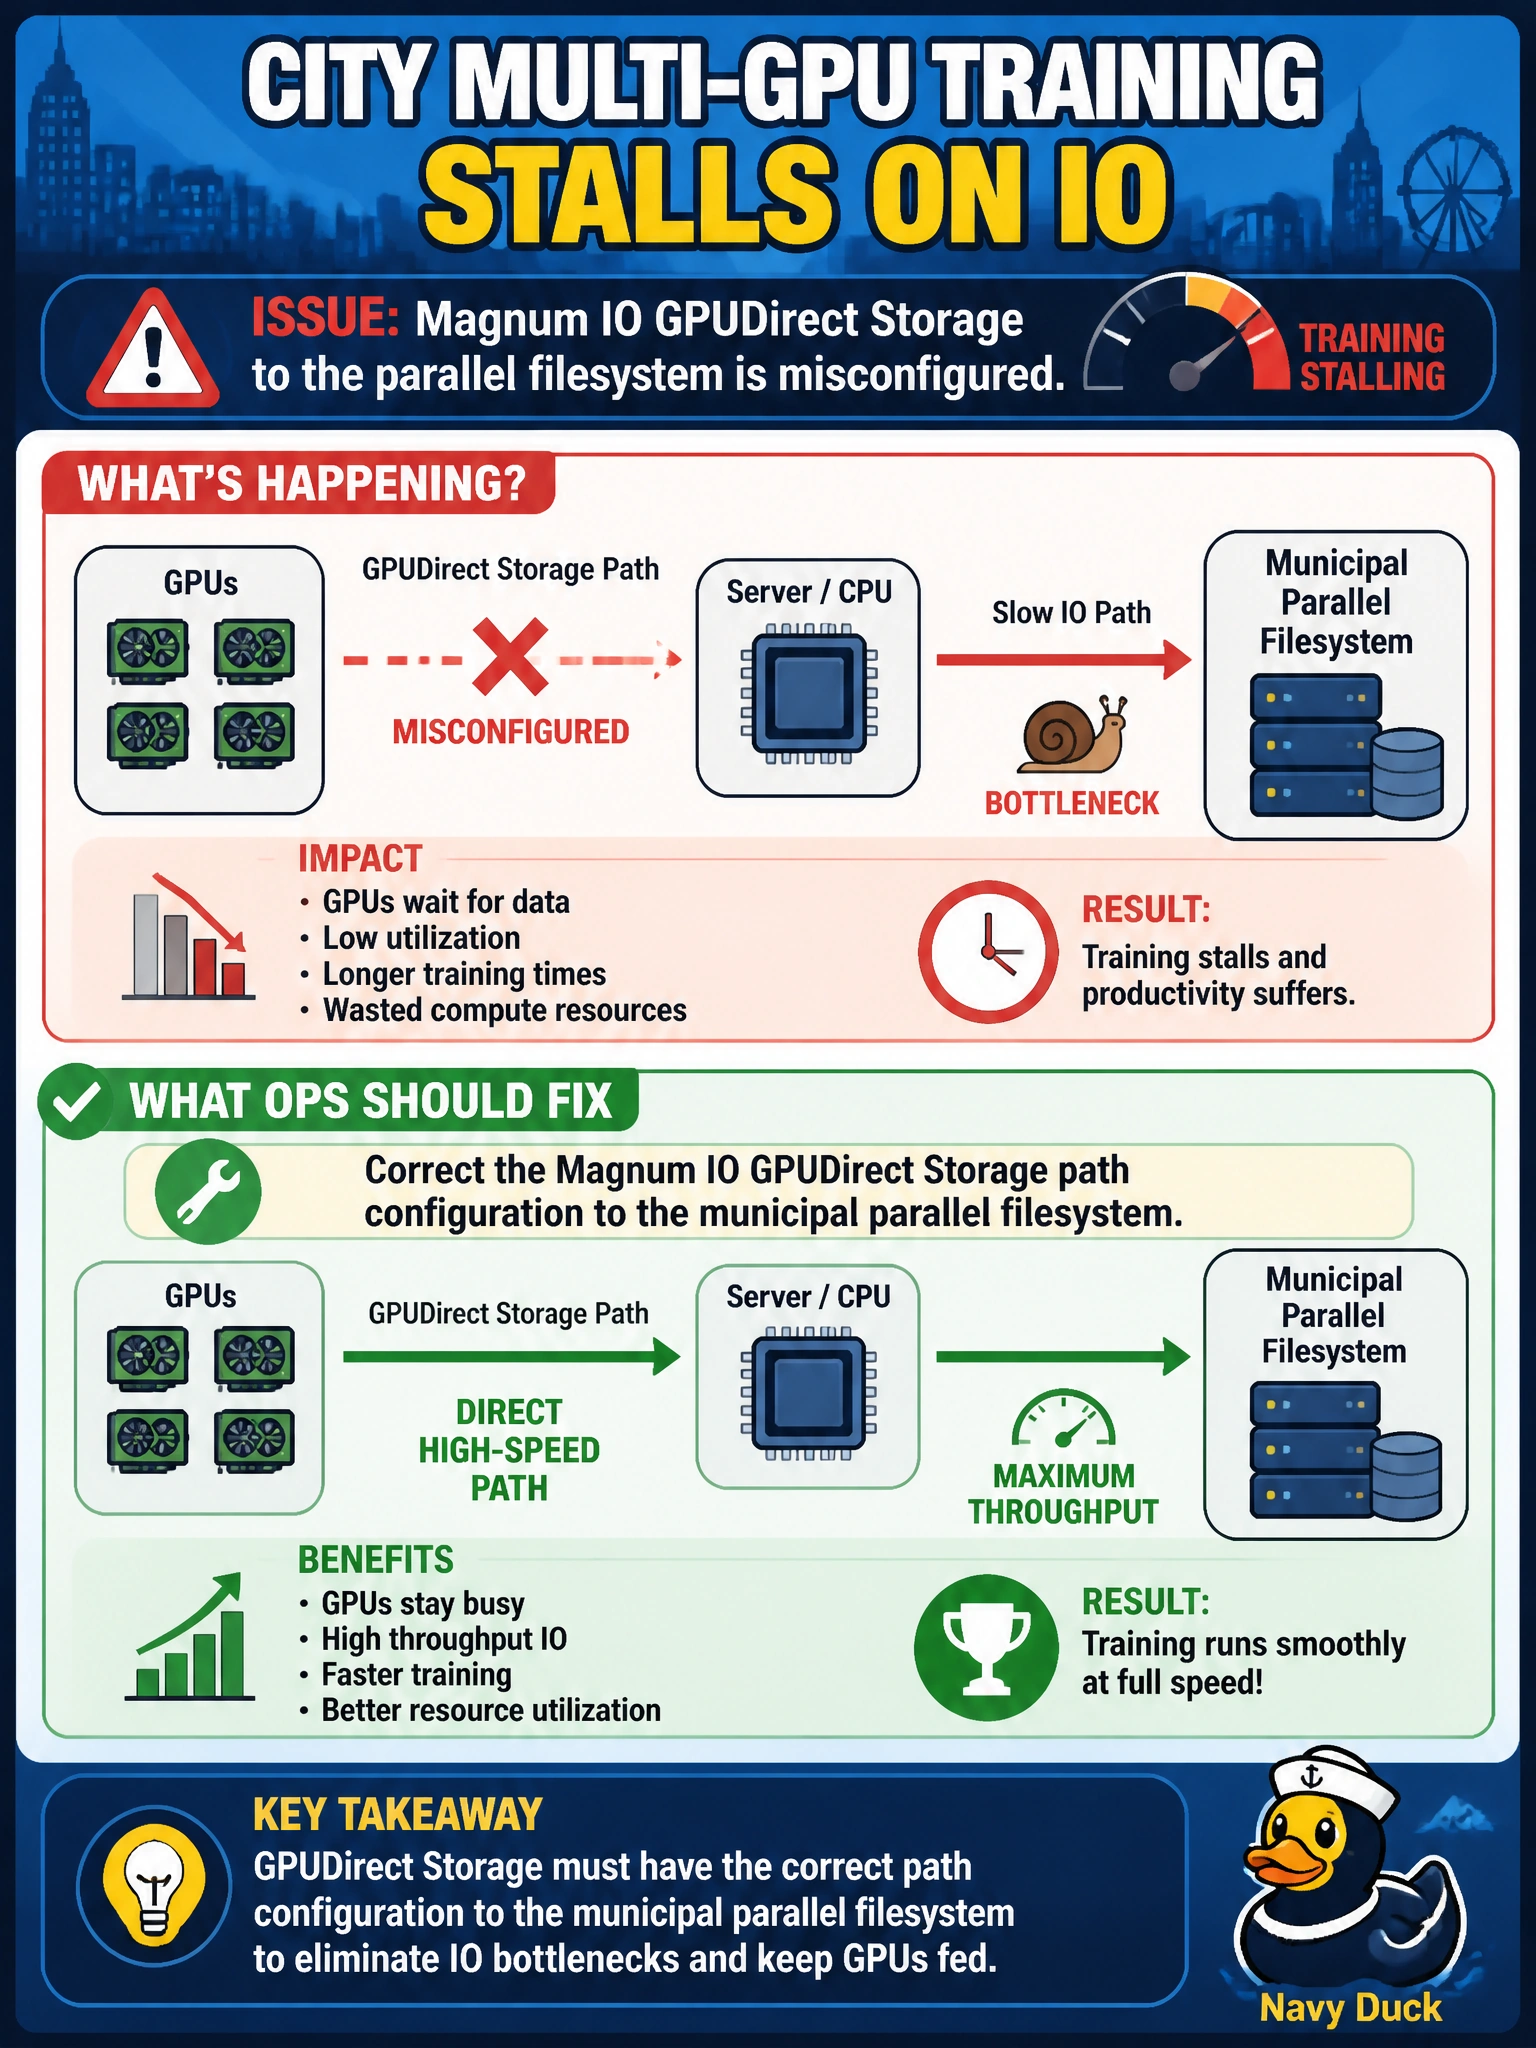
You can get training moving again by fixing the Magnum IO GPUDirect Storage path to the municipal parallel filesystem. Switching to CPU-only nodes, keeping checkpoints only in /tmp, or removing Magnum IO would avoid the fix rather than clear the IO stall.
Full Explanation
Magnum IO GPUDirect Storage (GDS) accelerates training IO by enabling a direct path between GPUs and the parallel filesystem. When city multi-GPU training stalls on IO because GDS is misconfigured, correcting its path to the municipal parallel filesystem restores the intended accelerated route for checkpoint writes and dataset reads. Path, mount, or enablement mistakes can force slower CPU-mediated copies, making training appear inexplicably stalled. Forcing all training onto CPU-only nodes abandons GPU acceleration instead of fixing the GDS configuration that should feed those GPUs. Disabling the parallel filesystem and keeping checkpoints only in node-local /tmp loses shared, durable municipal storage and does not scale to multi-node training. Removing Magnum IO packages eliminates the stack intended to solve this class of IO stall. Exam caveat: Magnum IO GDS problems present as IO-bound training, not NCCL topology bugs, so verify the GDS path and enablement before rewriting model code; also confirm the filesystem client and GPUDirect prerequisites match the civic Magnum IO guide. Practical check: validate the GDS configuration against the municipal filesystem mount, run a controlled GPUDirect Storage read/write test from a training node, compare throughput with the CPU-copy baseline, then restart the stalled multi-GPU job and confirm IO wait drops.