
City IT builds a gold set of 200 labeled 311 dialogues to score the agent weekly. What evaluation practice does this implement?
Select an answer to reveal the explanation.
Short Explanation
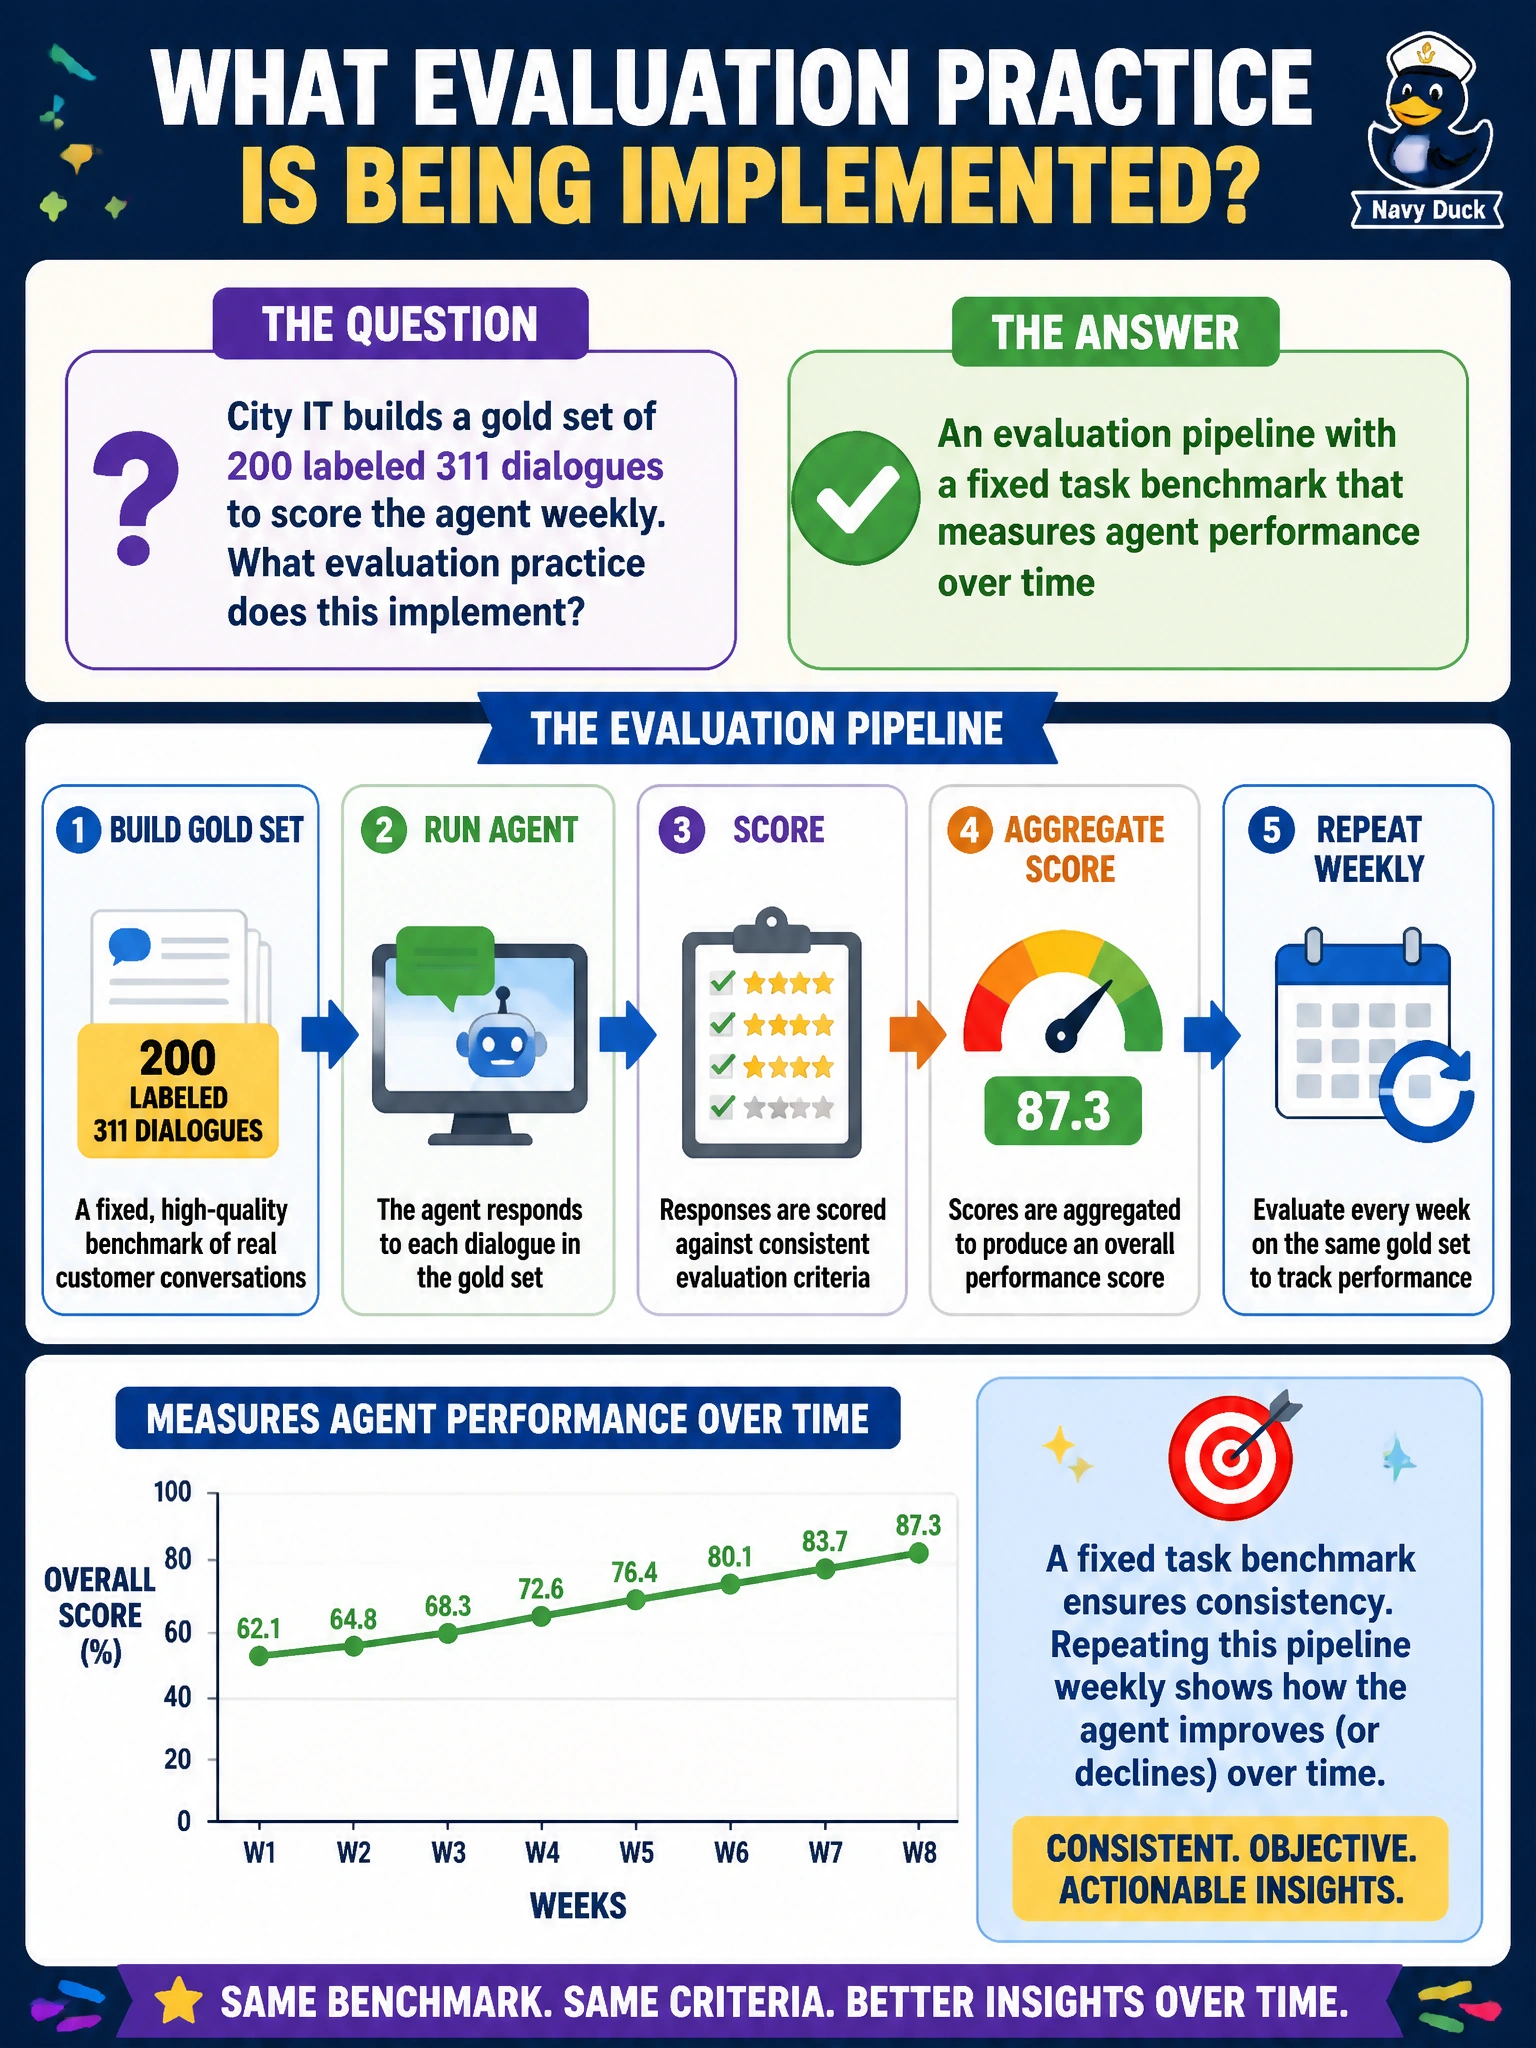
A labeled gold set is the city’s weekly report card for the 311 agent—same test, scored on purpose. That’s an evaluation pipeline with a real benchmark, not vibes from a council demo. Anecdotes alone won’t catch regressions.
Full Explanation
Building a gold set of 200 labeled 311 dialogues scored weekly implements an evaluation pipeline with a fixed task benchmark that measures agent performance over time. Curated labeled tasks create a repeatable civic scorecard: the same dialogues, consistent rubrics, and scheduled scoring reveal regressions after prompt or tool changes. That practice is how municipal teams move from anecdote to trendable quality for 311 agents.
Replacing all production monitoring with a single anecdotal staff opinion discards systematic measurement and cannot show week-over-week change. Publishing unlabeled chats publicly as the only success metric confuses transparency theater with scored evaluation and lacks ground-truth labels. Tuning production solely by which demo impressed council members optimizes for spectacle rather than labeled task performance.
Exam caveat: a gold-set benchmark complements—not fully replaces—online monitoring; both offline scheduled scoring and production signals matter. Operational check: freeze the 200-dialogue gold set and scoring rubric, run weekly scoring in the evaluation pipeline, alert on regressions versus prior weeks, and require investigation before promoting agent changes that drop gold-set metrics.