
Permit-answer accuracy must be measured against ordinance excerpts. Why is that benchmark choice better than generic chatbot leaderboards?
Select an answer to reveal the explanation.
Short Explanation
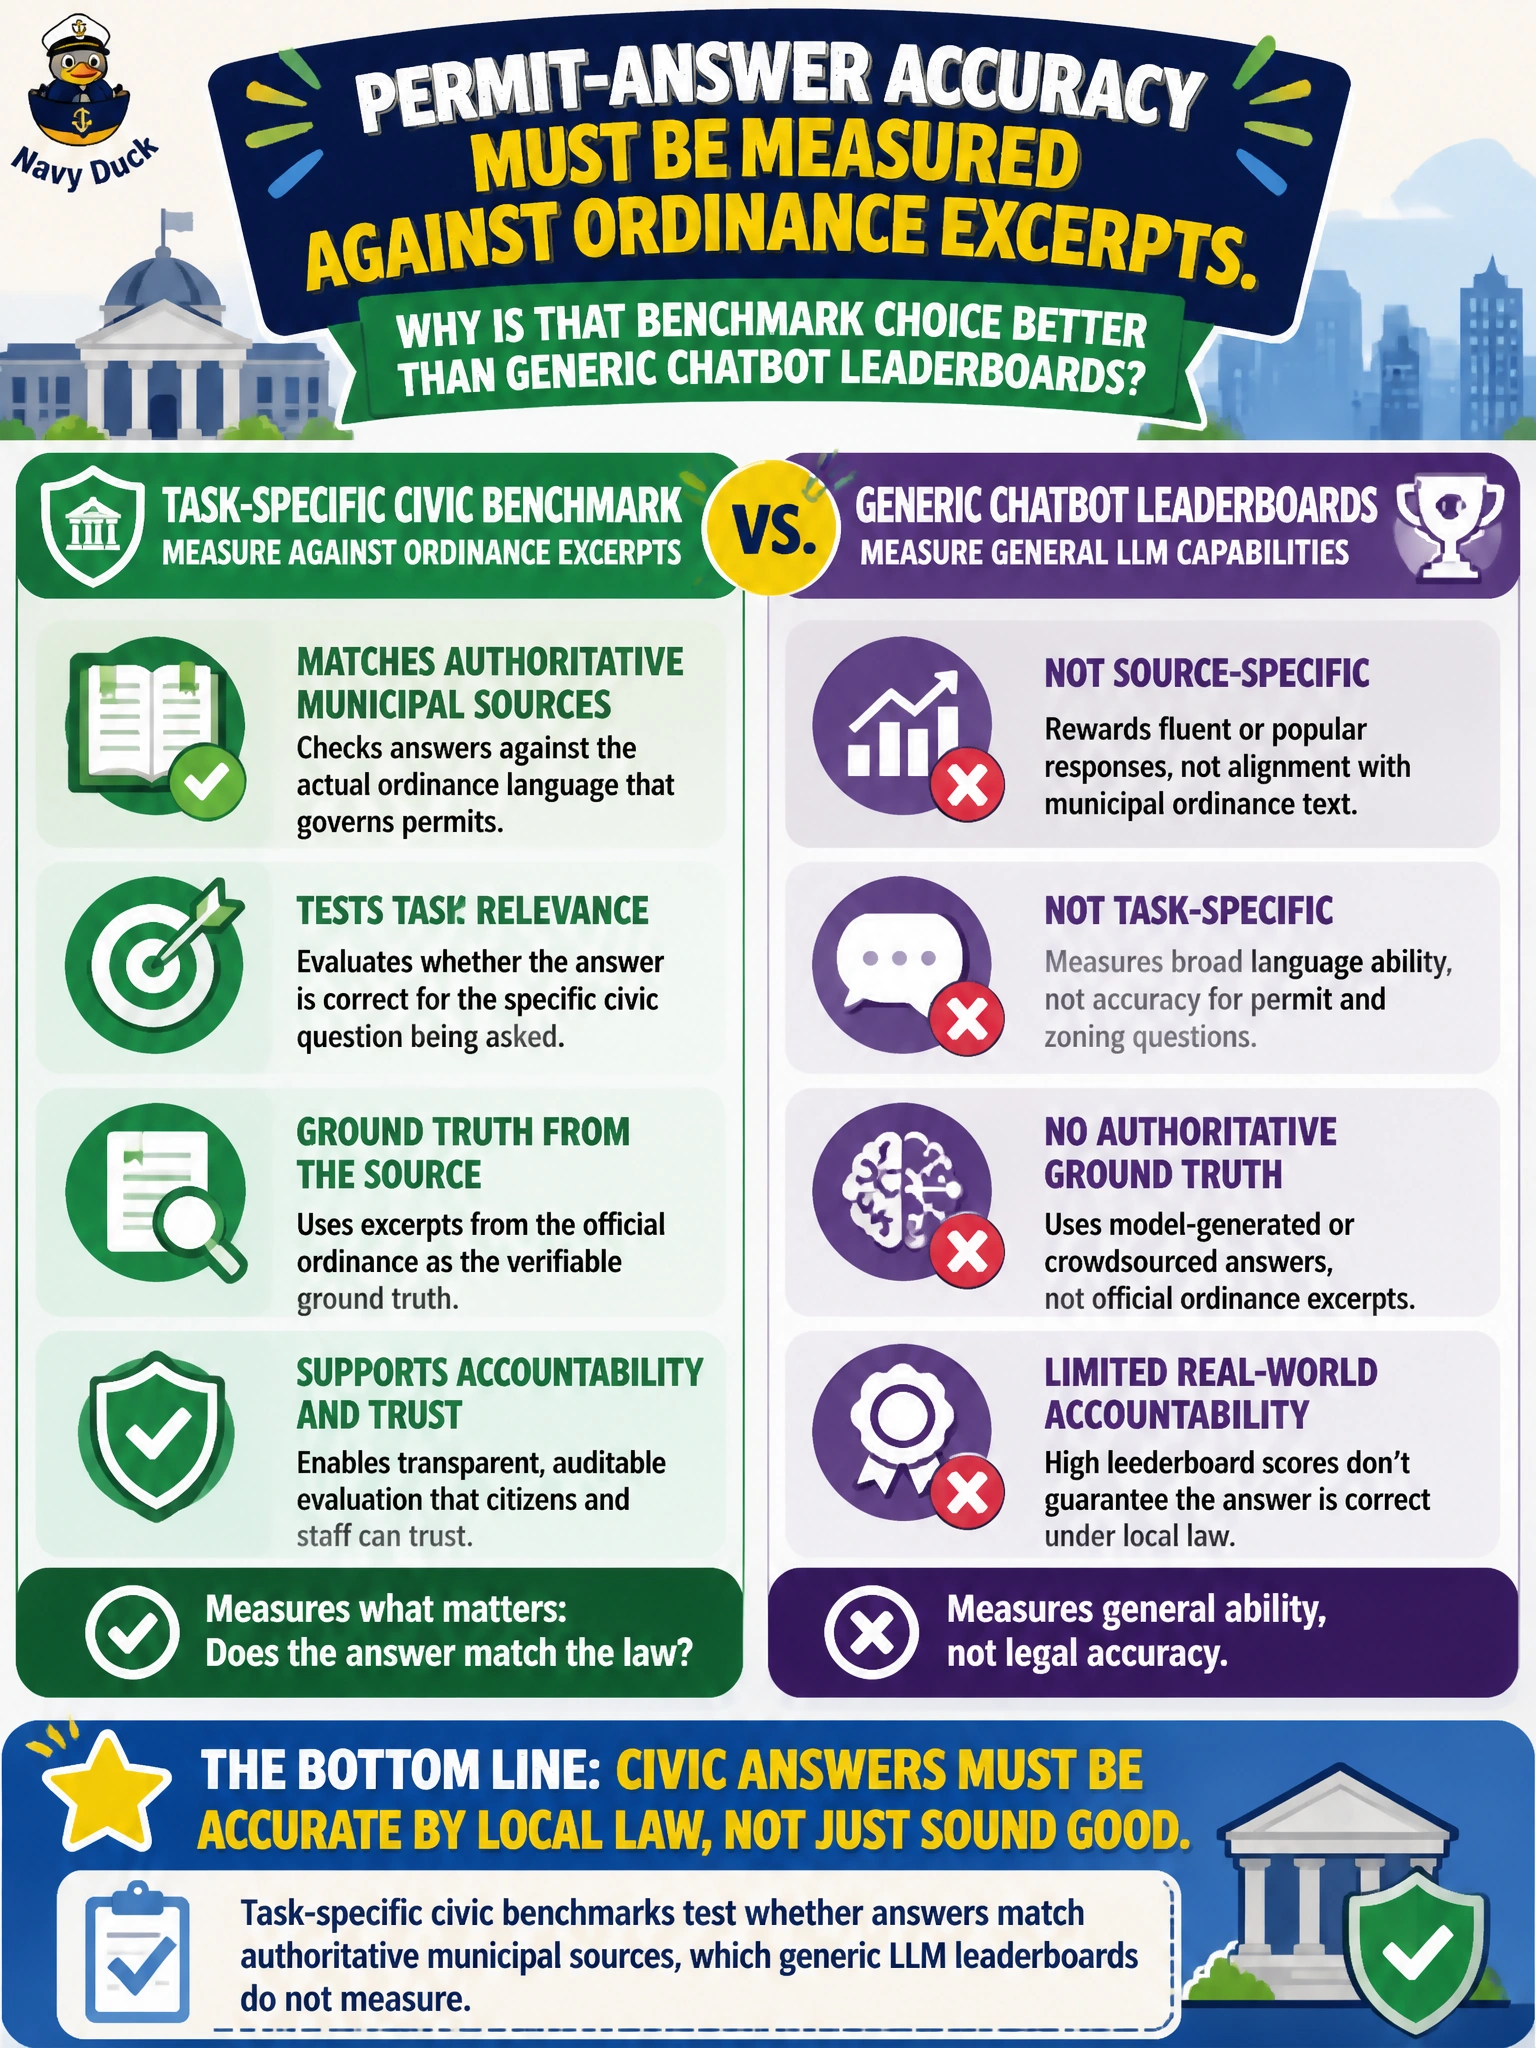
A global chatbot trophy doesn’t prove the bot quoted your ordinance right. Score permit answers against the actual code excerpts. Fluency isn’t the same thing as getting the fee and section correct.
Full Explanation
Permit-answer accuracy measured against ordinance excerpts is a task-specific civic benchmark: it tests whether answers match authoritative municipal sources. Generic chatbot leaderboards measure broad model skills on public datasets that do not embed a city’s zoning code, fee schedules, or local ordinance text. For permitting agents, grounded agreement with the authority of record is the evaluation target that matches operational risk—wrong fees and wrong sections harm residents and staff.
Generic leaderboards do not automatically include every city’s zoning code; they are not municipal legal corpora. Treating ordinance-grounded eval as unnecessary because fluency equals legal correctness confuses fluent prose with correct citations and amounts. Leaderboard rank alone cannot prove the agent cites the correct local fee schedule.
Exam caveat: task-specific civic benchmarks should use current ordinance excerpts and versioned fee schedules so evaluation does not reward outdated law. Operational check: build a permit-question set with gold ordinance spans and fees, score agent answers for grounded agreement, compare against any generic leaderboard vanity metric, and gate releases on civic benchmark performance rather than leaderboard rank.