
A library program attendance analytics team finds one GPU host cannot hold countywide fact tables. What complementary approach should they consider?
Select an answer to reveal the explanation.
Short Explanation
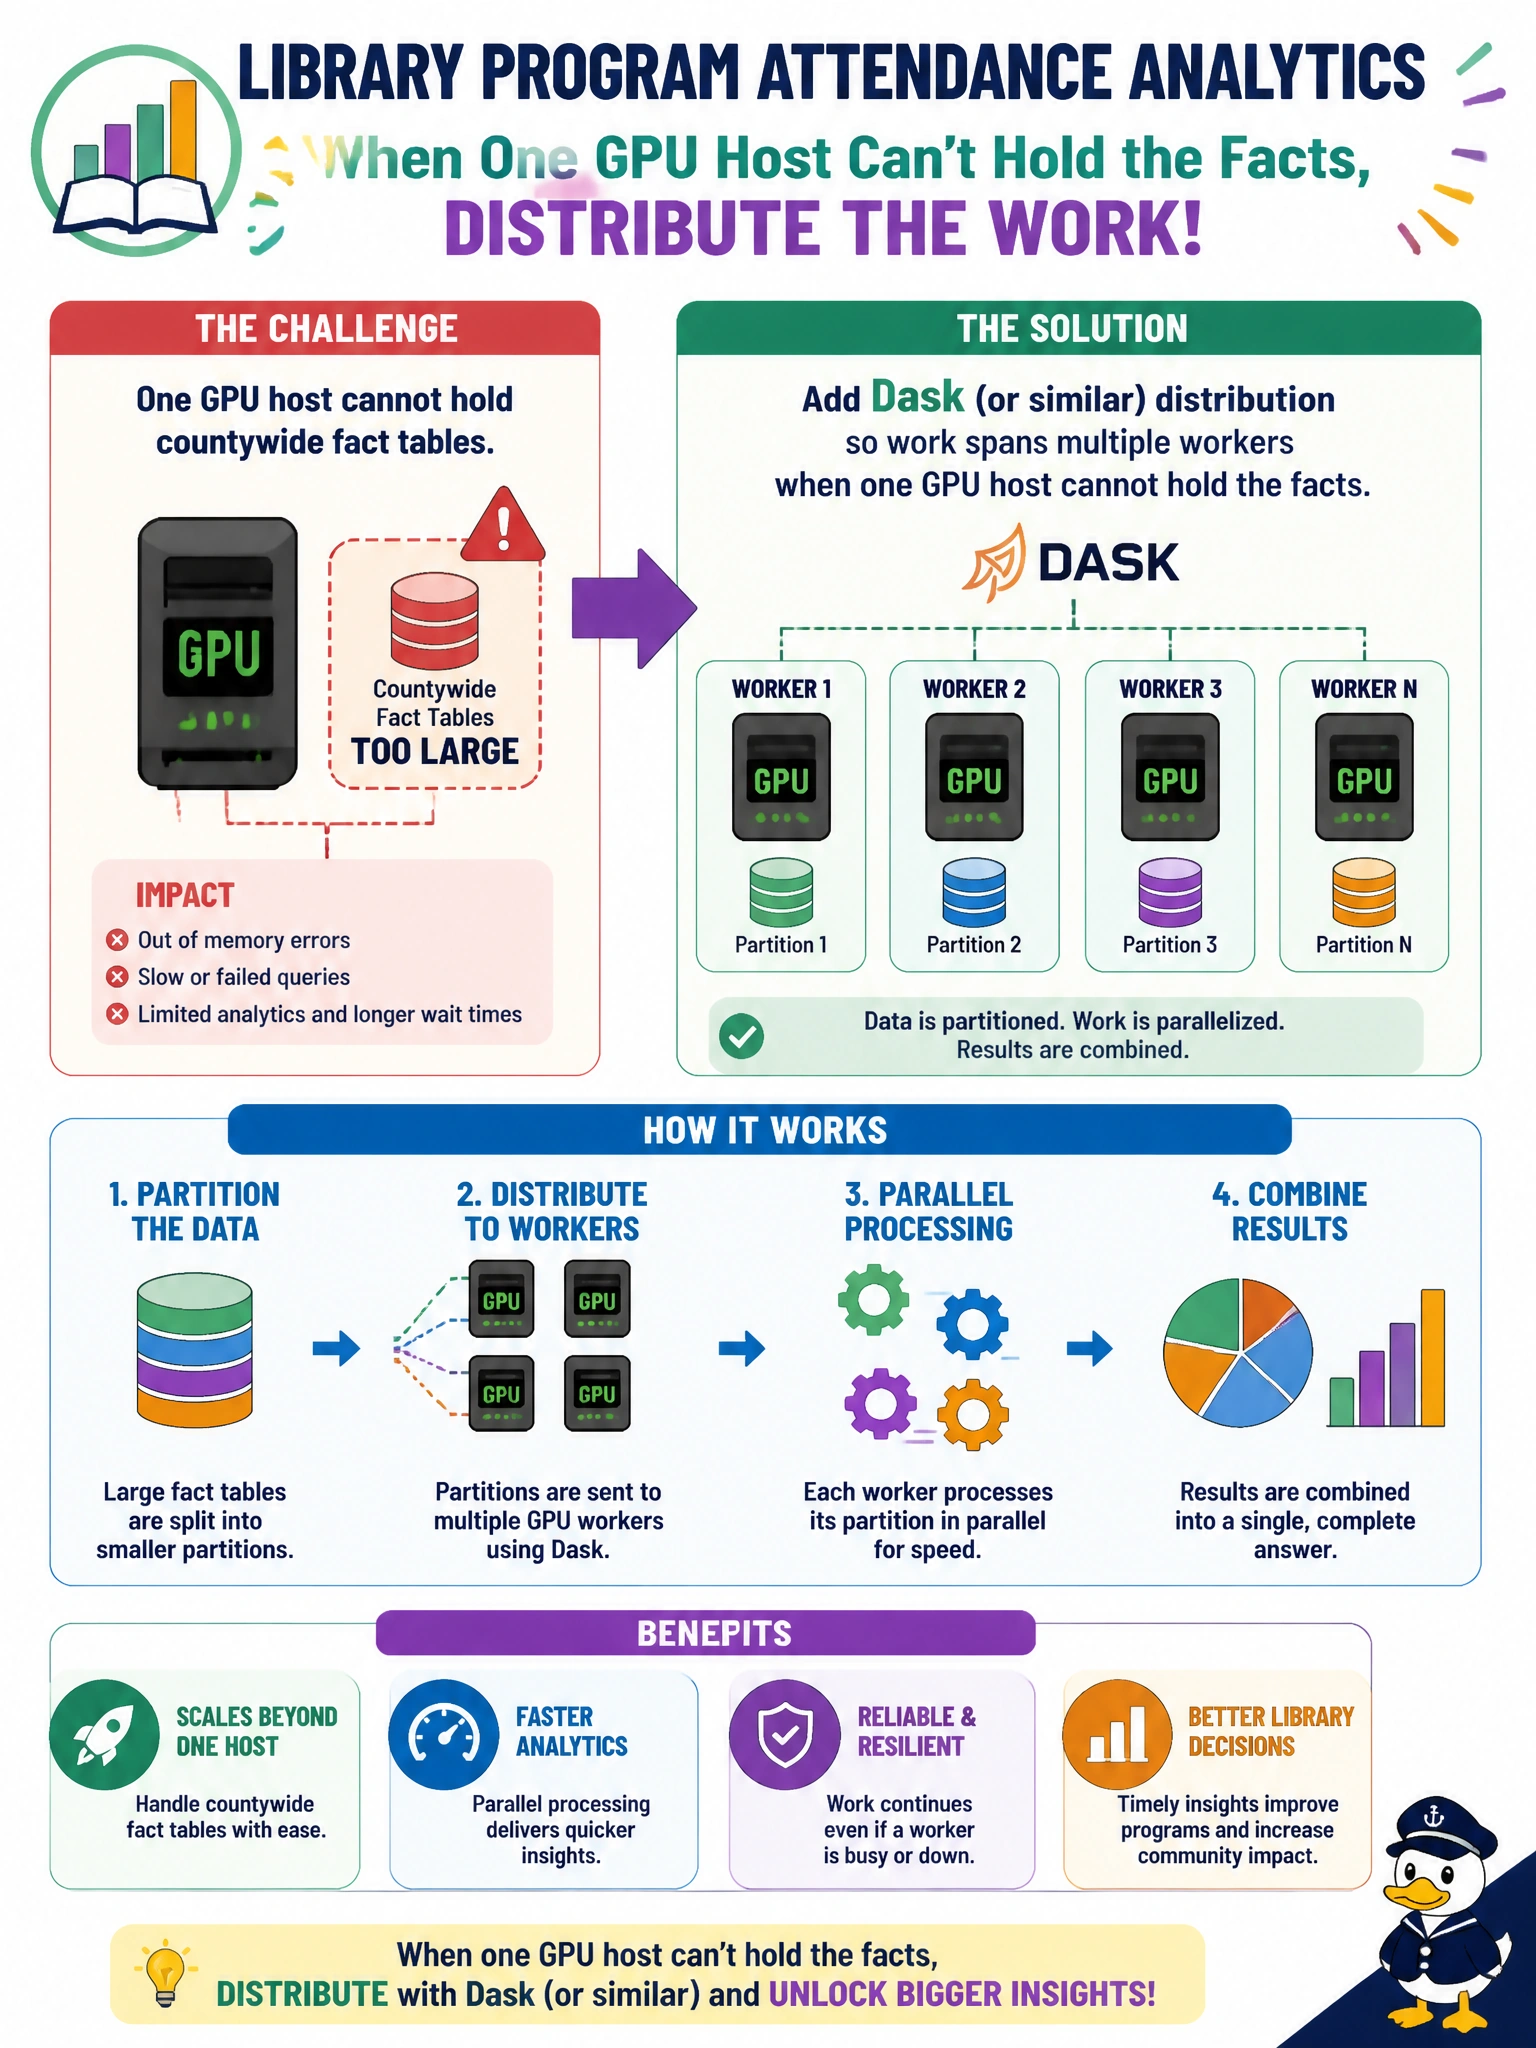
When one GPU host runs out of room for countywide facts, you can bring in Dask-style distribution to spread the work across workers. A fabricated summary row or email attachments won’t solve the scale problem, and distribution can complement GPU acceleration when memory runs out.
Full Explanation
When one GPU host cannot hold countywide library attendance fact tables, add Dask (or similar) distribution so work spans multiple workers. Distribution complements GPU acceleration: scale-out addresses memory and partition limits that a single device cannot. For civic datasets that outgrow one host, this lets you keep GPU benefits while spanning workers instead of pretending the county fits in one card. Replacing the countywide facts with one fabricated summary row falsifies the analytic population and produces meaningless attendance KPIs. Disabling GPUs entirely and never revisiting scale-out options abandons acceleration and ignores the remedy for memory pressure. Storing all facts only as uncompressed email attachments is not a scale-out architecture and undermines governance. Exam caveat: when single-host GPU memory is exceeded, distribute the work with Dask or a similar approach; fabricating a tiny dataset or emailing the facts is not a solution. Practical check: partition the countywide facts across a Dask cluster, validate row counts against the full extract, and retire one-row “fits” or email-based storage ideas.