
A financial technology company runs a real-time risk assessment model that spans both an on-premises private cloud and a public cloud environment. High data transfer times between the on-premises database and the cloud-based GPU inference cluster are causing the system to miss real-time transaction deadlines. Which network modification will best resolve the latency bottleneck while preserving the existing hybrid deployment architecture?
Select an answer to reveal the explanation.
Short Explanation
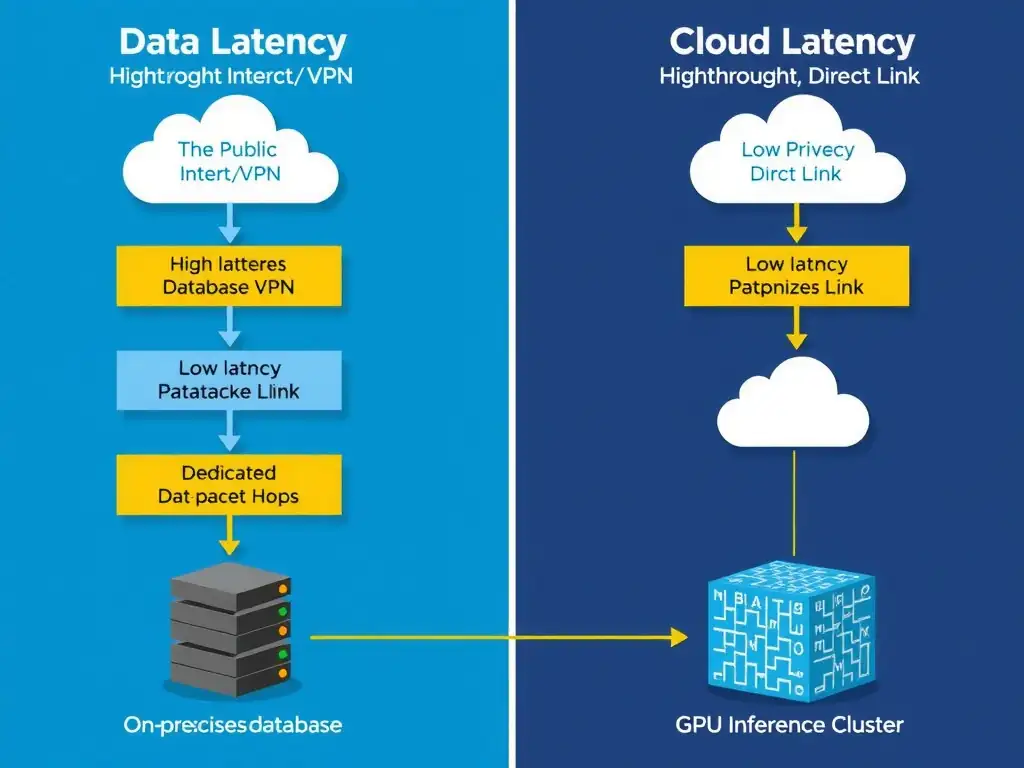
Check this out: if your hybrid risk model is timing out, the problem is the pipe, not the GPUs. Put in a dedicated, high-throughput private link between your data center and the cloud, and you'll slash latency without ripping out the architecture.
Full Explanation
In hybrid cloud architectures supporting real-time AI applications, data transit latency between the on-premises environment and the public cloud is a common operational bottleneck. Real-time inference pipelines, such as those used for fraud detection or risk assessment, operate under strict SLA constraints, often sub-100 milliseconds. If data must traverse standard internet connections or basic VPN tunnels, packet delivery times become unpredictable because of routing hops, jitter, and network congestion. Establishing a dedicated, low-latency, high-throughput direct connection, such as AWS Direct Connect, Azure ExpressRoute, or Google Cloud Dedicated Interconnect, bypasses the public internet entirely. It establishes a physical, private telecommunications circuit between the enterprise data center and the cloud provider's edge location. This guarantees consistent bandwidth, dramatically reduces round-trip times, and provides a highly secure channel for sensitive transaction data. This solution directly addresses the latency issue while allowing the organization to maintain its hybrid architecture, which may be required for compliance, data sovereignty, or cost management reasons. Rehosting the entire database and model execution pipeline exclusively on local on-premises hardware, or otherwise moving the workload entirely to a single cloud provider, ignores the organizational requirements that drove the hybrid model choice in the first place, such as security policies, capital expenditure utilization, or regulatory constraints, and it also abandons the existing hybrid deployment architecture. Deploying additional GPU nodes on-premises to completely replicate the cloud infrastructure's throughput locally does not solve the data transfer latency issue if the application still depends on real-time data syncs or model updates between the local site and the cloud. Routing all data traffic over standard public internet VPN tunnels actually increases packet overhead and latency because of encryption processing and the unpredictable nature of public internet routing.