
An international bank is architecting a real-time, global credit card fraud detection pipeline. The pipeline must ingest billions of transaction records, execute deep learning-based tabular models with sub-millisecond response times, and scale dynamically without service interruption. Which combination of NVIDIA infrastructure and software frameworks is optimized to meet these high-throughput requirements?
Select an answer to reveal the explanation.
Short Explanation
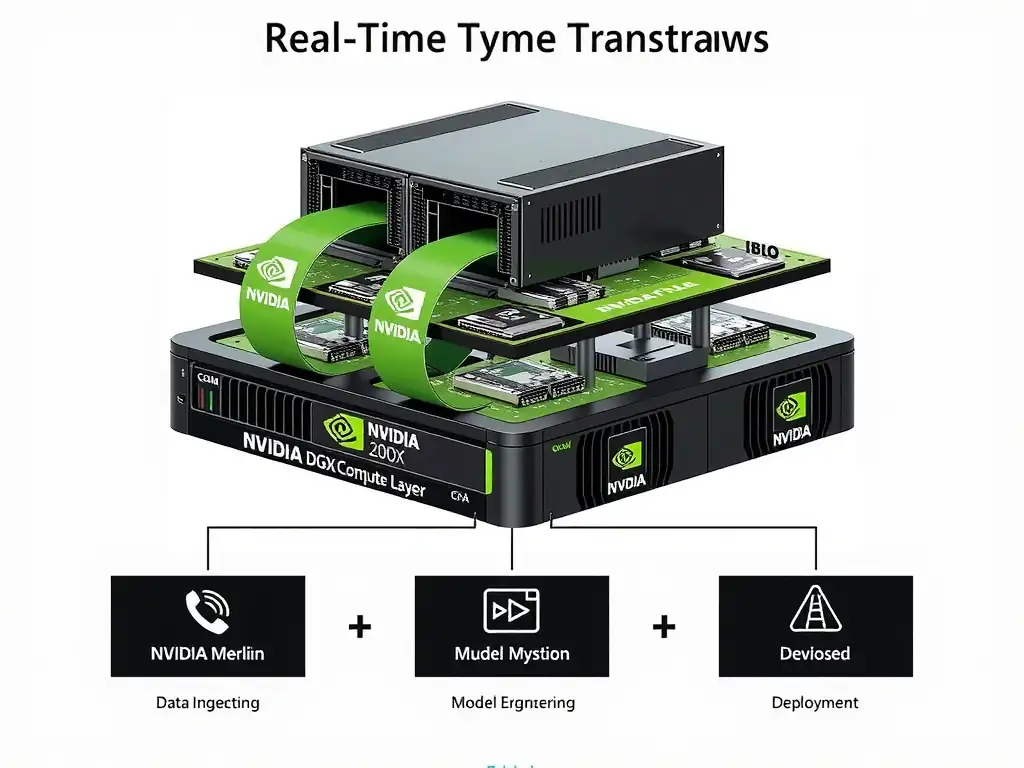
You're chasing fraud in real time, so you need DGX systems and NVIDIA Merlin. DGX gives you the GPU muscle, and Merlin speeds up tabular transaction pipelines so decisions come back in milliseconds. CPU servers, workstation cards, and edge modules won't cut it.
Full Explanation
Enterprise-grade, real-time fraud detection systems require high-performance computing platforms capable of scaling to handle massive volumes of transaction data with minimal latency. The database operations and deep learning models associated with fraud detection are typically based on tabular data and sequential patterns, similar to large-scale recommender systems. Deploying these workloads on NVIDIA DGX platforms provides the necessary hardware foundation. DGX systems integrate multiple high-performance enterprise GPUs, such as the A100 or H100, with high-bandwidth interconnects, such as NVLink and NVSwitch, and high-speed networking, such as InfiniBand or Ethernet. This architecture minimizes communication latency between GPUs, allowing for efficient distributed training and inference. On the software side, NVIDIA Merlin is an application framework optimized for deep learning recommender systems and large-scale tabular dataset processing. Merlin accelerates the entire pipeline, from data preprocessing and feature engineering via NVTabular to model training and deployment. This tight integration of hardware, DGX, and software, Merlin, enables the sub-millisecond response times required to assess fraud risk before transactions are approved. Reviewing the incorrect approaches: the standard CPU-based server approach running CUDA-accelerated libraries for localized processing lacks the massive parallel processing capabilities of GPUs, and CUDA cannot run directly on CPU hardware without GPU acceleration. The NVIDIA Quadro workstation card approach running standard TensorFlow containers for model training and local inference uses workstation-class GPUs designed primarily for professional visualization, computer-aided design, and rendering, rather than the high-density, multi-GPU scale required for global transaction processing. The NVIDIA Jetson edge accelerator approach deployed in local branches for decentralized database query processing uses low-power system-on-module edge accelerators designed for embedded systems, robotics, and edge AI, not for central data center core pipelines processing global banking transactions.