
A data scientist is building a fraud detection model using a transaction dataset containing ten million records. However, only 0.05% of the transactions are flagged as fraudulent. If the model is trained on this data as-is, it will likely achieve high accuracy simply by classifying every transaction as legitimate. Which preprocessing strategy should the scientist apply to prevent this bias and ensure the model accurately learns the characteristics of fraudulent transactions?
Select an answer to reveal the explanation.
Short Explanation
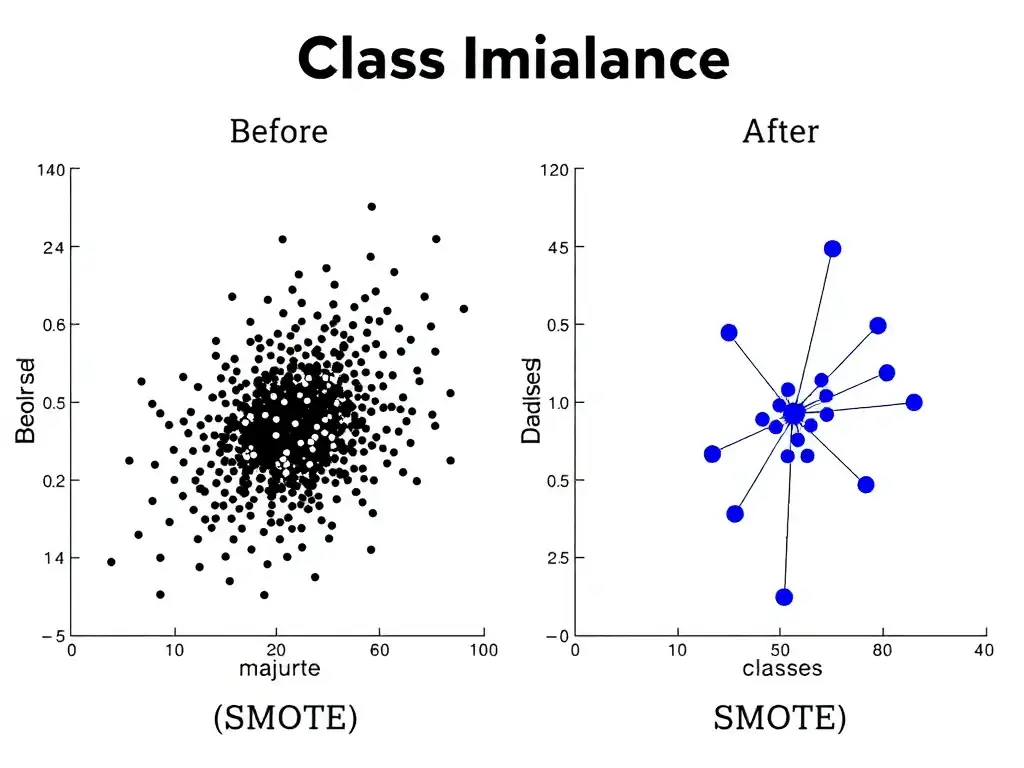
Here's the deal: when 99.95% of transactions are legitimate and only 0.05% are fraud, your model gets lazy. It'll guess legitimate every time, hit high accuracy, and miss fraud. You need to balance the scales by oversampling the minority class with synthetic fraud examples, such as the synthetic minority over-sampling technique, so the model learns both classes.
Full Explanation
Class imbalance is a pervasive challenge in classification tasks such as fraud detection, medical diagnosis, and cybersecurity. When one class vastly outnumbers the other, such as 99.95% legitimate transactions versus 0.05% fraudulent transactions, a standard machine learning algorithm will optimize for the majority class because that minimizes the loss function most easily. Consequently, the model exhibits strong bias and fails to recognize rare minority events. The correct preprocessing strategy is to balance the dataset by oversampling the minority class, specifically using the synthetic minority over-sampling technique. That technique creates synthetic examples of the minority class by interpolating between existing minority samples, giving the model sufficient representation of the rare class and enabling it to learn the distinguishing boundaries between classes. Discarding the minority class data and focusing the model entirely on predicting normal transaction patterns is wrong because it makes it impossible to build a fraud classifier; the model will never see examples of fraud. Training the model using the raw dataset but evaluating its performance using only overall classification accuracy is wrong because it does not solve the underlying bias and uses a highly misleading metric. In highly imbalanced datasets, metrics such as precision, recall, F1 score, and area under the precision-recall curve must be used. Applying principal component analysis to reduce dataset features while excluding the minority class records from the projection is wrong because it is counterproductive. Principal component analysis reduces dimensionality but does not address class imbalance, and excluding the minority class from feature reduction ensures that the model loses the features critical for distinguishing fraudulent transactions.