
You are designing an end-to-end pipeline for a large language model that processes terabytes of raw text data and trains across a cluster of NVIDIA DGX systems. To maximize training speed, you must eliminate the CPU bottleneck during data preparation (tokenization and loading) and optimize collective communication during distributed weight synchronization. Which combination of NVIDIA software libraries is designed specifically to address these two areas?
Select an answer to reveal the explanation.
Short Explanation
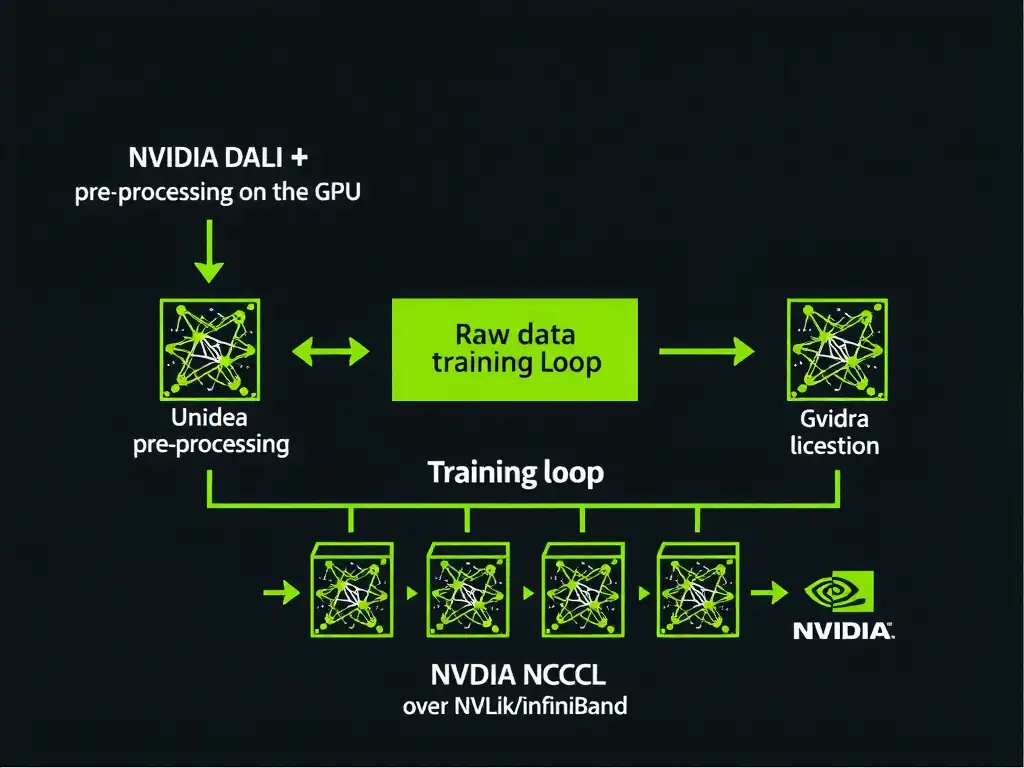
You need DALI to keep the GPUs fed by offloading data loading and preprocessing, and NCCL to make multi-GPU and multi-node communication fast during distributed training. Together, they remove the CPU data bottleneck and speed up collective operations like AllReduce.
Full Explanation
To achieve maximum training efficiency on multi-GPU systems, developers must solve two major performance bottlenecks: data loading/preprocessing and inter-GPU communication. NVIDIA DALI (Data Loading Library) is a collection of highly optimized building blocks designed to accelerate data pipelines for deep learning. Typically, data preprocessing such as decoding, resizing, and tokenization is handled by the CPU, which can become a bottleneck and leave the GPU underutilized. DALI offloads these operations to the GPU or optimizes them on the CPU, ensuring a continuous, fast stream of training data. NVIDIA NCCL (NVIDIA Collective Communications Library) provides multi-GPU and multi-node collective communication primitives such as AllReduce, AllGather, Reduce, Broadcast, and ReduceScatter that are highly optimized for NVIDIA GPUs. NCCL automatically detects the underlying topology, such as NVLink, PCIe, or InfiniBand, and uses the fastest path to synchronize weights and gradients across devices, ensuring efficient distributed training. The pairing of NVIDIA TensorRT and NVIDIA DGX OS is incorrect because TensorRT is an inference optimizer, not a training data pipeline or communication library, and DGX OS is an operating system, not a software library for data loading or collective communication. The pairing of NVIDIA cuDNN and NVIDIA NGC Catalog is incorrect because cuDNN is a GPU-accelerated library for deep neural network primitives such as convolutions and pooling, while the NGC Catalog is a repository of pre-trained models and containers; neither directly solves data loading bottlenecks or multi-GPU collective communication. The pairing of NVIDIA DeepStream SDK and NVIDIA CUDA Toolkit is incorrect because DeepStream SDK is designed for multi-sensor processing and video/audio analytics inference pipelines, while the CUDA Toolkit is the general development environment rather than the specific libraries needed for data loading acceleration and collective communication optimization.