
A networking engineer is optimizing a multi-node GPU cluster for a massive deep learning training job. They observe that the traditional network stack is introducing significant CPU overhead and high latency when transferring tensor gradients between GPU memories on different physical servers. Which technology should they implement to enable direct node-to-node memory transfers that bypass the OS kernel and host CPU?
Select an answer to reveal the explanation.
Short Explanation
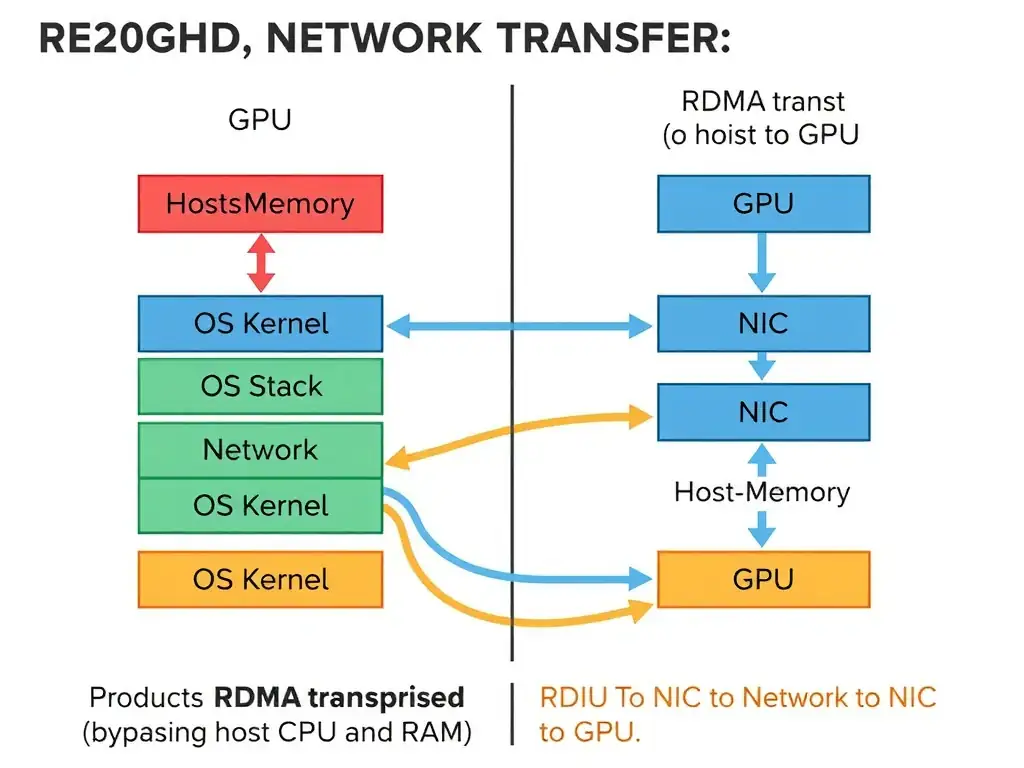
Here's the deal: when your GPUs are sharing gradients across servers, you don't want the host CPU and operating system kernel stuck in the middle. InfiniBand with remote direct memory access lets one GPU write directly into another node's GPU memory, bypassing the kernel and CPU. For a high-performance cluster, that's the move.
Full Explanation
In distributed deep learning, models are split across multiple GPUs and nodes. During the backward pass, GPUs must synchronize gradients, typically using an AllReduce operation. If this communication relies on standard TCP/IP over Ethernet, the data must travel through multiple layers of the operating system kernel and TCP stack, requiring CPU interrupts and memory copying. This creates a severe latency and throughput bottleneck. InfiniBand with Remote Direct Memory Access addresses this issue by allowing one computer to access the memory of another computer without involving either one's operating system or CPU. GPUDirect RDMA takes this a step further by allowing direct memory access between GPUs on different nodes across the network fabric. This bypasses the host CPU and system memory entirely, drastically reducing latency and maximizing throughput. The standard TCP/IP over 100 Gigabit Ethernet approach introduces high latency and CPU overhead due to packet encapsulation, buffer copying, and kernel interrupts, even at high speeds like 100 Gbps. Virtual Local Area Network segmentation is used to isolate broadcast domains and secure traffic on a network. It does not bypass the CPU stack or accelerate memory transfers. Network Address Translation loopback routing is a method for routing traffic from a private network back to itself through an external IP address. It adds routing overhead and has no acceleration benefits for node-to-node GPU communication.