
When building or running deep learning models on NVIDIA GPUs, frameworks like PyTorch and TensorFlow do not write low-level GPU acceleration code for standard mathematical operations from scratch. Instead, they rely on a specific NVIDIA library that provides highly optimized, hardware-tuned implementations of routines like convolutions, pooling, activation functions, and forward/backward passes. What is the name of this library?
Select an answer to reveal the explanation.
Short Explanation
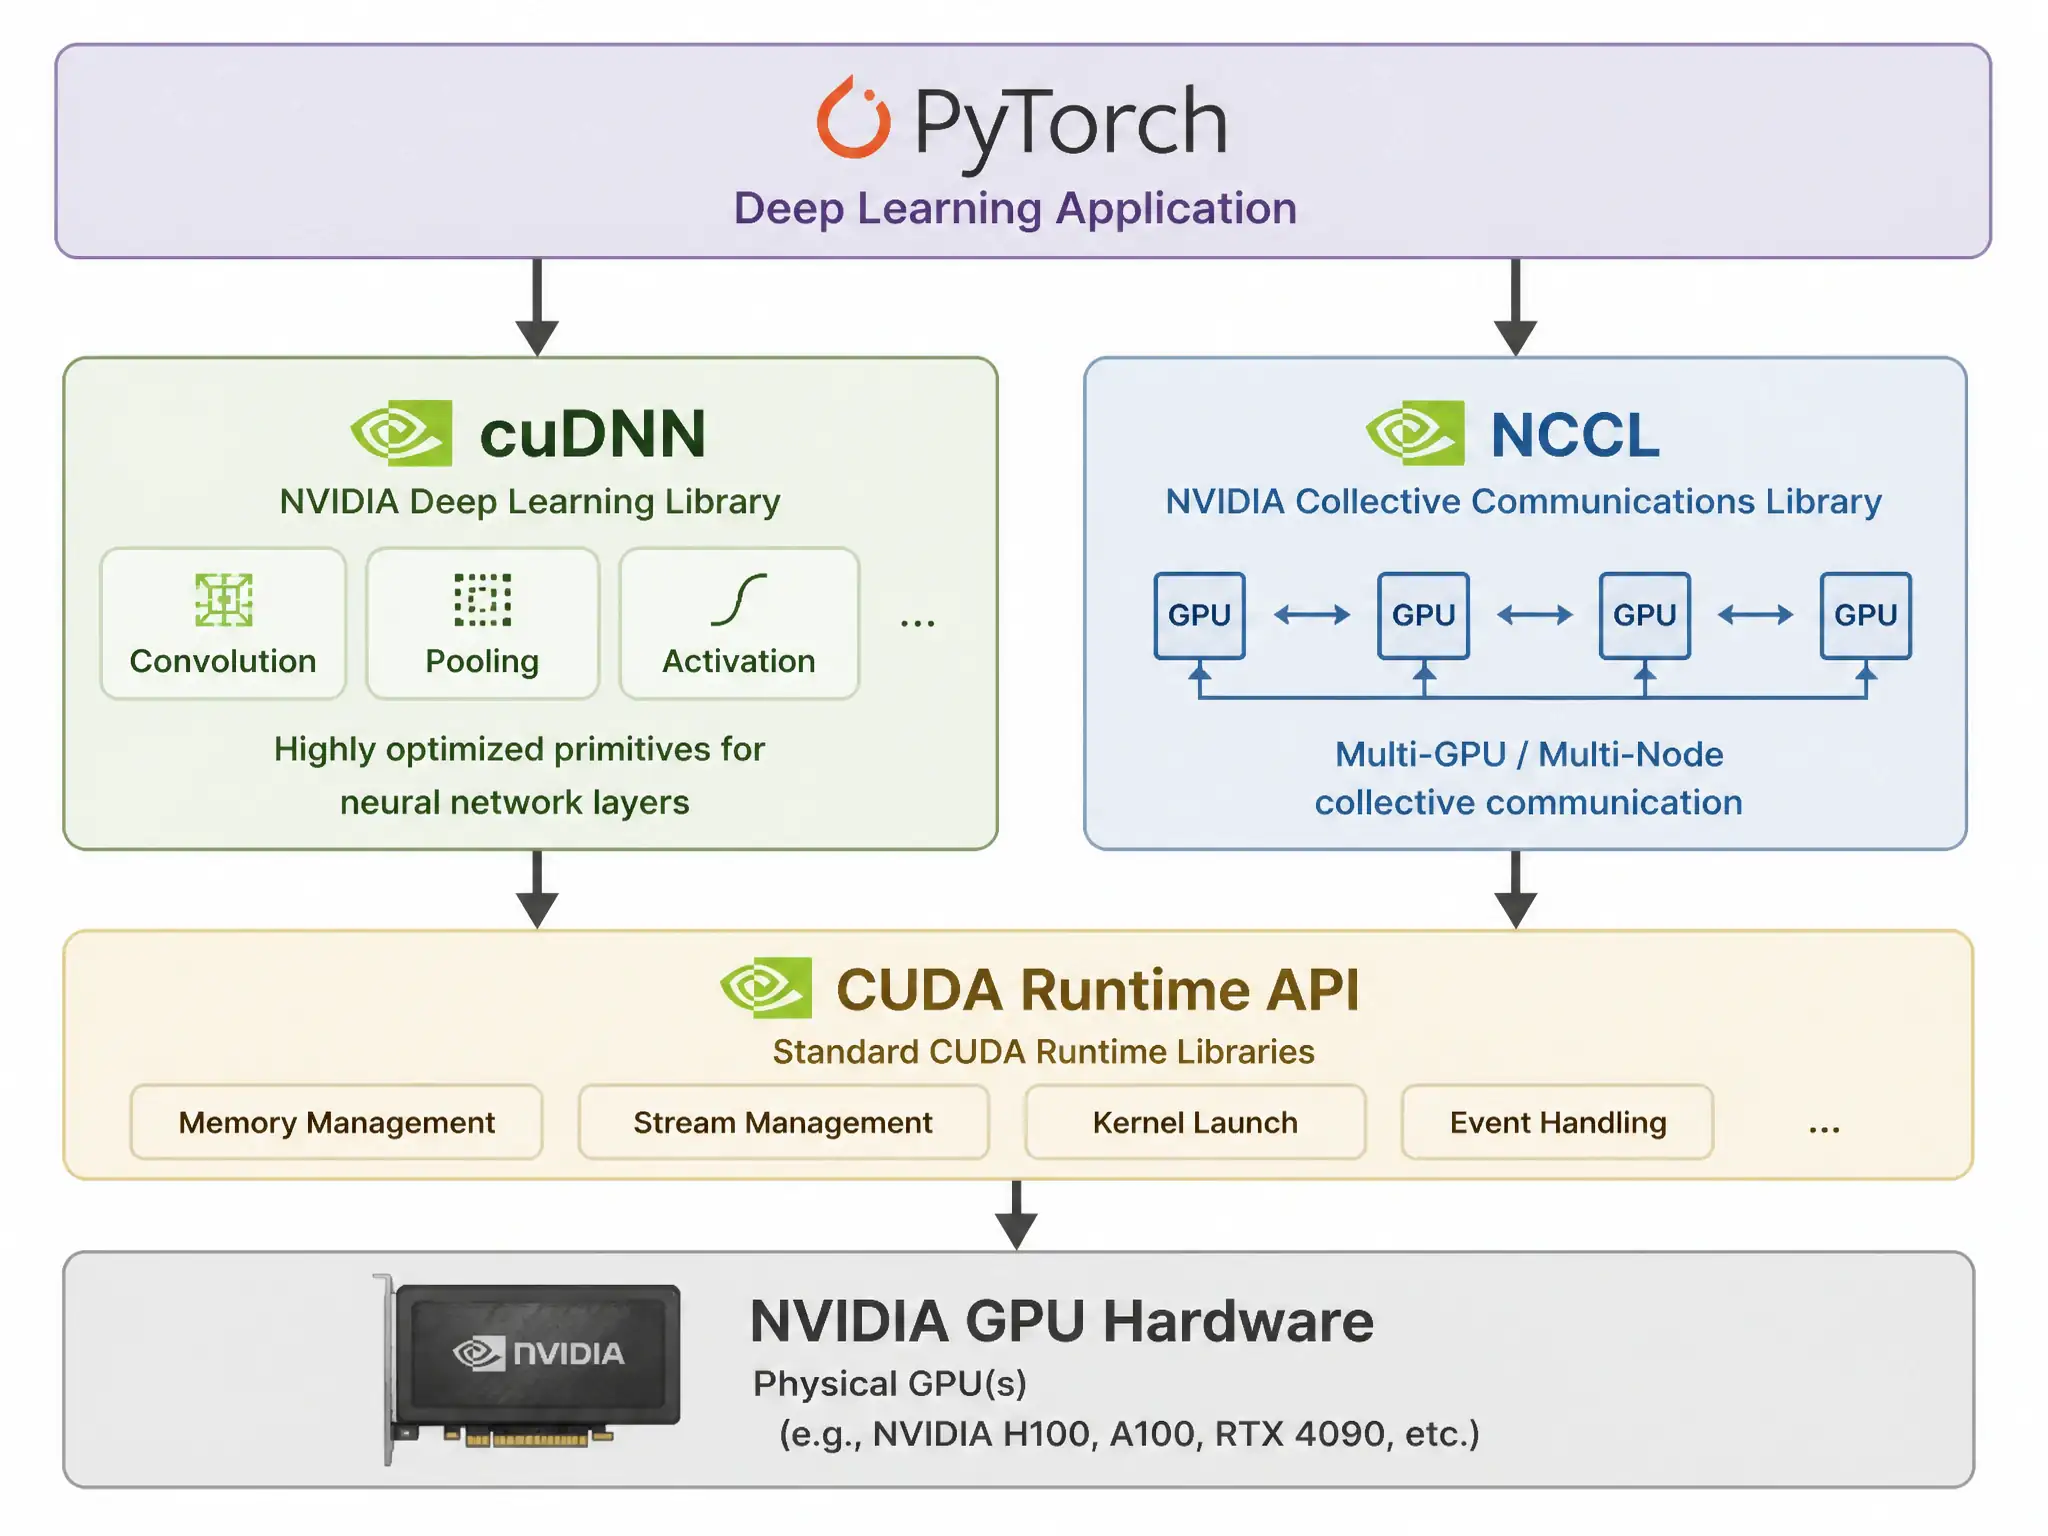
Here's the deal: you don't want to reinvent the wheel, especially when NVIDIA has already built a rocket-powered one for you. When you write deep learning code in PyTorch or TensorFlow, routines like convolutions, pooling, and activation functions call cuDNN—the CUDA Deep Neural Network library. NVIDIA's engineers have spent years tuning cuDNN to squeeze performance out of GPU architectures, so your code runs fast without low-level GPU math code.
Full Explanation
Modern deep learning architectures depend heavily on a few core mathematical primitives, such as multi-dimensional convolutions, pooling, activation functions such as ReLU and Sigmoid, and normalization layers. Writing custom CUDA kernels for these operations that are optimized for every generation of GPU architecture, such as Ampere, Ada Lovelace, or Hopper, is an immense development challenge. To address this, NVIDIA provides cuDNN, the CUDA Deep Neural Network library, which is a GPU-accelerated library of primitives for deep neural networks. Frameworks like PyTorch, TensorFlow, and JAX interface directly with cuDNN to execute these operations. cuDNN automatically selects the most efficient algorithms at runtime, taking advantage of hardware features like Tensor Cores, to maximize computational throughput.
The other options represent different parts of the NVIDIA software stack. The NVIDIA Collective Communications Library, or NCCL, handles multi-GPU and multi-node collective communication primitives, such as all-reduce and broadcast, not mathematical layers within a single model. The CUDA Toolkit Compiler, nvcc, is the compiler driver used to compile CUDA C/C++ source code into executable device binaries; it is not a library of deep learning routines. TensorRT is a high-level SDK used to optimize completed models specifically for production deployment, performing layer fusion, precision calibration, and serialization, rather than the low-level mathematical primitive library utilized by general training frameworks.