
Your team has successfully trained a deep learning model for real-time translation on a distributed cluster using massive datasets. Now, the project is moving into the production deployment phase, where the model will serve live API requests from millions of mobile users. Which of the following architectural requirements becomes the primary focus when designing this inference environment compared to the original training setup?
Select an answer to reveal the explanation.
Short Explanation
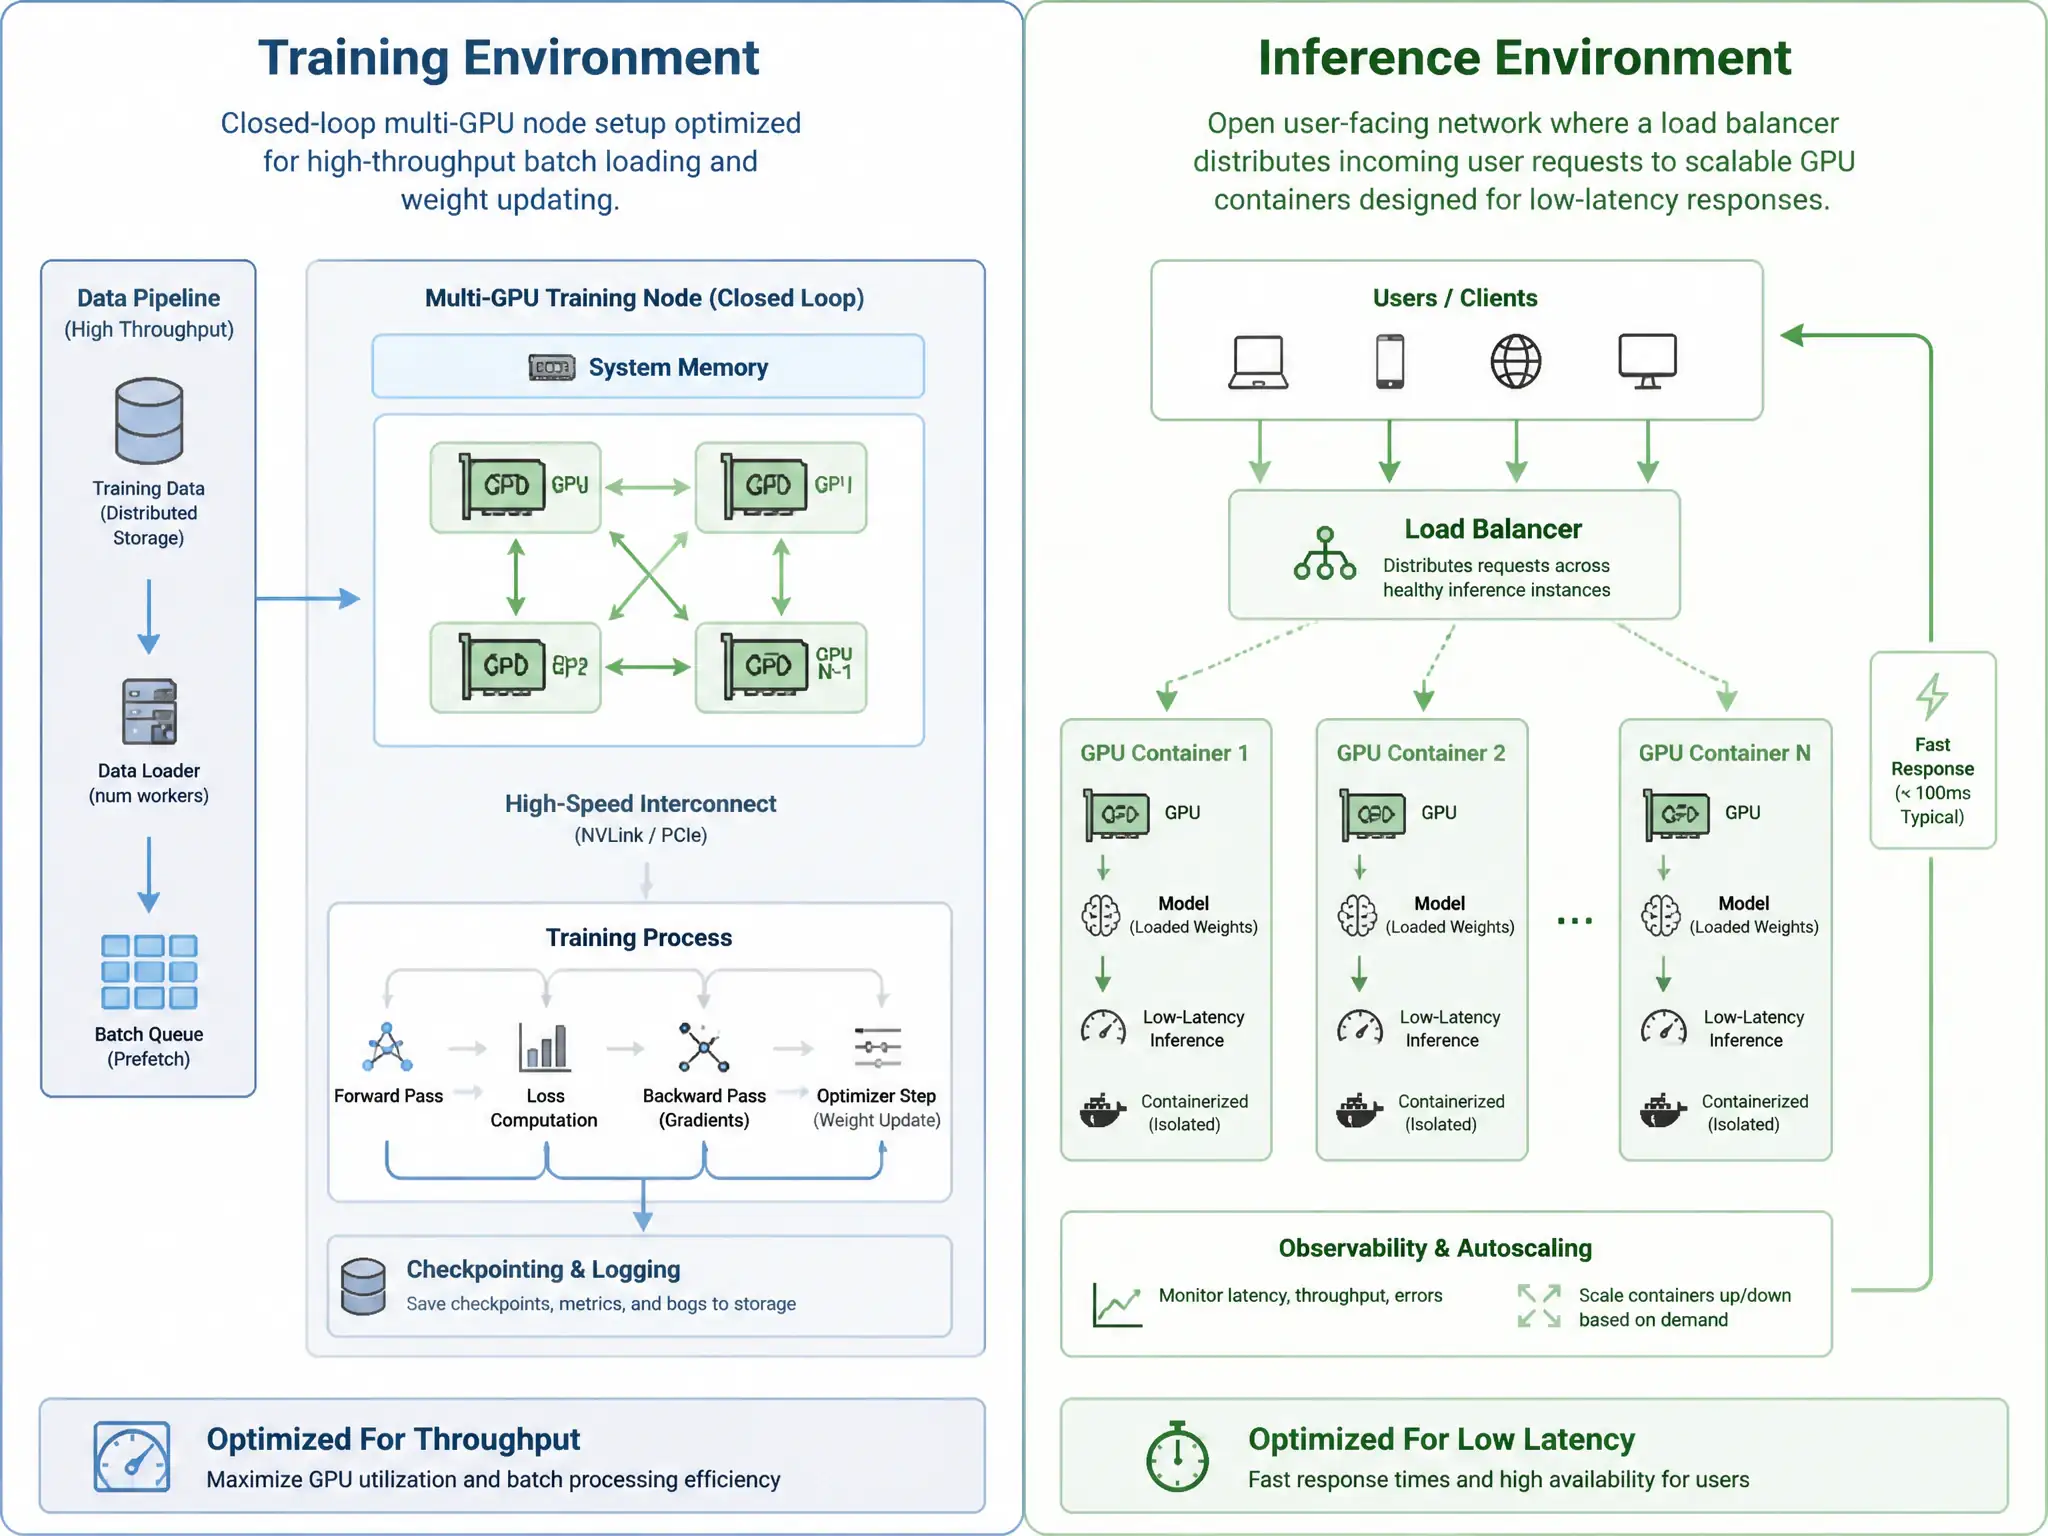
Once your model goes live, you're chasing milliseconds, not training throughput. You need low-latency inference and autoscaling to handle traffic spikes without wasting money.
Full Explanation
The transition from deep learning model training to production inference represents a fundamental shift in systems engineering priorities. During training, the primary metric is aggregate throughput: processing massive batches of training samples to update model weights as quickly as possible, and it's acceptable for the process to take hours or days. Systems are optimized for high memory bandwidth and efficient distributed communication, such as using NCCL over InfiniBand. In contrast, the inference phase focuses on serving real-time predictions to end-user requests, where a user isn't going to wait ten seconds for a response. The primary architectural goals here are minimizing latency, reducing the time elapsed between an incoming request and the outgoing prediction, and supporting horizontal autoscaling. The infrastructure must dynamically spin up or tear down model serving containers in response to real-time API demand variations, such as ten users at 3 AM and ten thousand users at 3 PM, to maintain latency SLAs while optimizing operational costs. The other requirements focus on training-phase activities. Maximizing distributed training bandwidth and inter-GPU communication throughput is essential for synchronizing gradients across multi-GPU setups during backward passes, which is not required when running forward-pass inference. Enabling periodic model checkpointing and weight optimization saving rates is a recovery mechanism for long training runs to save weights, whereas inference servers run with static, frozen weights. Implementing heavy data augmentation pipelines and hyperparameter searches are pre-training techniques used to improve generalization and tune architecture parameters, having no role in the active inference path.