
A system administrator scales an image classification model training job from two GPUs to eight GPUs. However, the total training time remains nearly identical, and monitoring logs reveal that while the CPU cores are pinned near 100% utilization, the GPU utilization has dropped significantly. What is the most likely root cause of this scaling failure?
Select an answer to reveal the explanation.
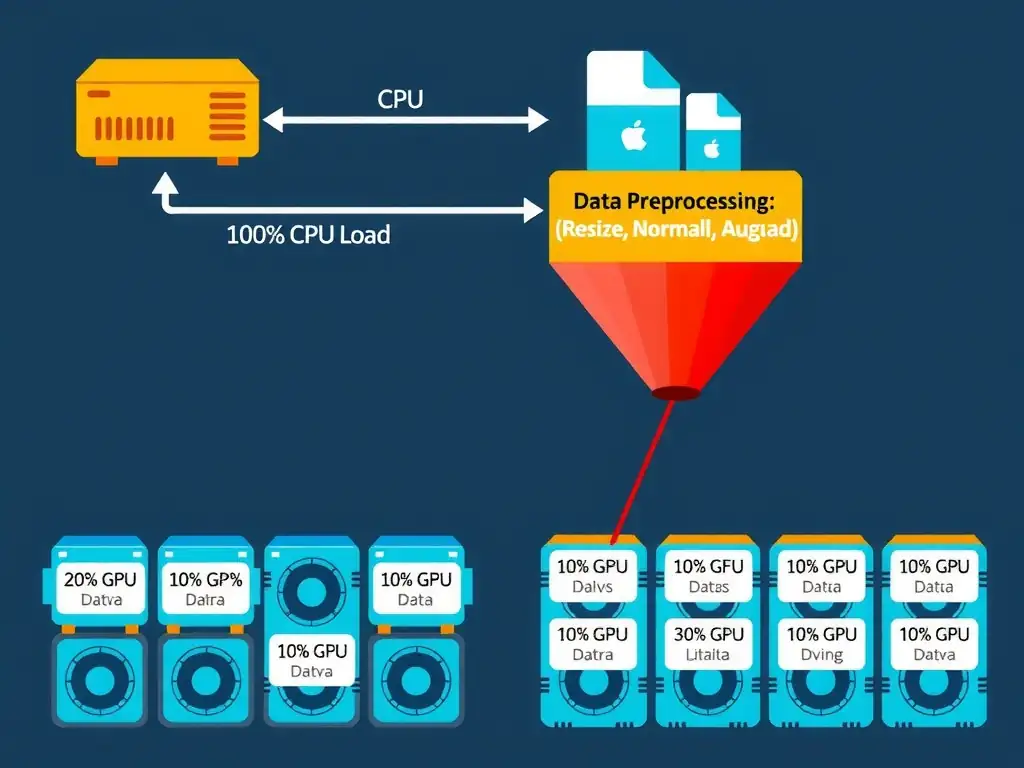
Short Explanation
You added more GPUs, but your training time didn't drop because your CPU is stuck doing on-the-fly data preprocessing and augmentation. The CPUs are pinned near 100%, so your GPUs starve waiting for data instead of computing. Fix the data pipeline, not the GPU count.
Full Explanation
When scaling deep learning training across multiple GPUs, linear speedup is the goal. However, system performance is governed by Amdahl's Law, meaning the non-parallelizable portions of the workload will limit the speedup. If adding more GPUs results in low GPU utilization and maximum CPU utilization, the system is experiencing a data ingestion bottleneck, specifically caused by the host CPU being unable to preprocess and transfer data fast enough to keep the GPUs fed. This matches the root cause of the host CPU being bottlenecked by on-the-fly data preprocessing and augmentation tasks.
During training, the host CPU is responsible for executing the data pipeline, which includes reading raw data from disk, decompressing files, and performing real-time data augmentation (such as rotations, crops, normalization, or tokenization). If these preprocessing steps are computationally expensive and executed sequentially or with insufficient CPU threads, the CPU becomes the system bottleneck. The GPUs finish executing their forward and backward passes quickly and then sit idle (exhibiting low utilization) while waiting for the CPU to deliver the next mini-batch. Adding more GPUs actually exacerbates this issue, as the demand for preprocessed data increases.
The other explanations are less likely. If the machine learning framework lacked multi-GPU execution support, the job would typically fail to compile, run on only a single GPU while leaving others at 0% utilization, or output errors, rather than pinning the CPU at 100%. If the physical NVLink bridge connectors were missing between the GPU sockets, inter-GPU communication speeds would degrade, causing high latency during gradient synchronization, but this would typically result in high GPU wait times without pinning the host CPU at 100% utilization for data preparation. If a mismatched version of the NVIDIA driver were causing device communication errors, the job would likely produce execution failures and runtime driver errors during initialization, preventing it from running at all.