
In an enterprise multi-GPU cluster running concurrent deep learning workloads, telemetry logs show that a subset of GPUs is constantly throttled at 100% compute and memory capacity, while other identical GPUs in the cluster sit idle or operate below 15% utilization. What is the most effective architectural solution to resolve this resource imbalance and optimize job completion times?
Select an answer to reveal the explanation.
Short Explanation
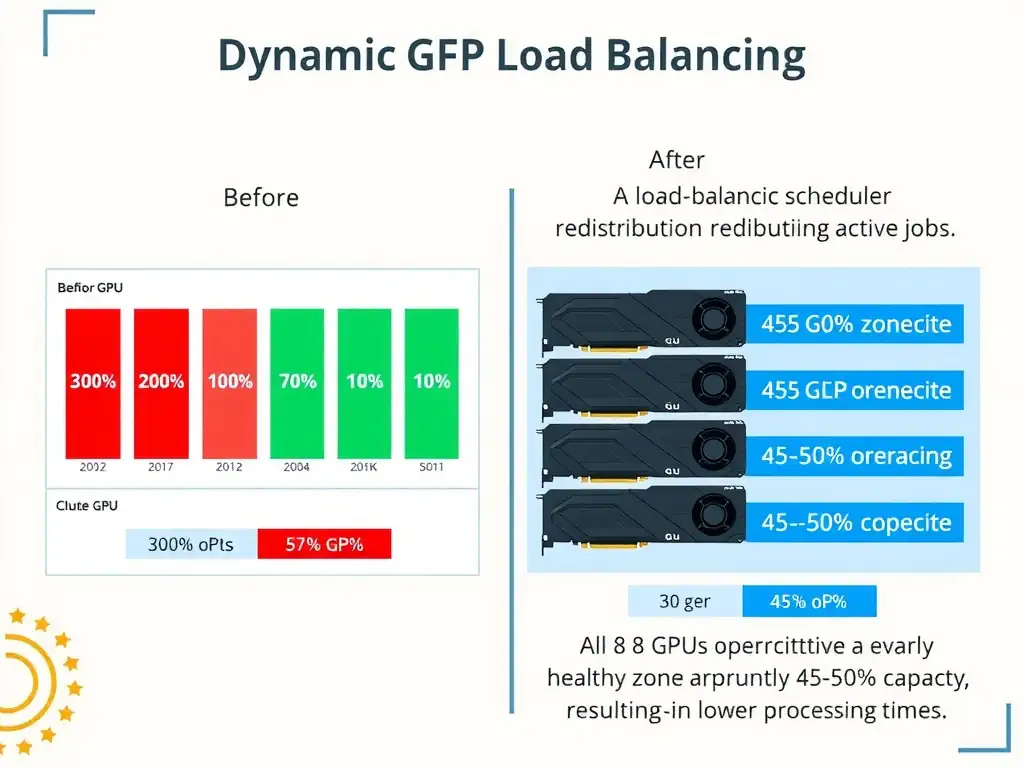
Here's the deal: if half your GPUs are pegged at 100% while identical ones sit idle, you've got a scheduling problem, not a power problem. Implement dynamic GPU load balancing so the scheduler routes work to cards with free headroom. That levels utilization and speeds up job completion.
Full Explanation
In multi-node, multi-GPU environments, unequal workload distribution leads to resource fragmentation, thermal hotspots, and degraded job completion times. When some GPUs are overburdened while others remain underutilized, it indicates a failure in resource orchestration. The most effective solution to correct this imbalance is configuring dynamic GPU load balancing and resource scheduling across the cluster.
Dynamic load balancing utilizes a centralized cluster scheduler, such as Kubernetes with specialized device plugins or Slurm, that continuously monitors real-time telemetry from each GPU, including GPU compute utilization, memory usage, temperature, and power consumption. When a new training or inference job is submitted, the scheduler dynamically routes the workload to the nodes and GPUs with the highest available capacity. Furthermore, advanced schedulers can migrate running tasks or scale instances dynamically to maintain an even distribution of compute stress, maximizing the return on infrastructure investment and reducing execution bottlenecks.
Let's examine the incorrect choices. Increasing the electrical power ceiling on the underutilized GPUs via command-line tools will not increase their usage if the scheduler is not routing workloads to them; power limits control the maximum wattage a GPU can draw under load, but do not generate work. Globally reducing the mini-batch size for all running model instances is a poor workaround that reduces the throughput of the busy GPUs without addressing the fact that other GPUs are sitting idle, ultimately slowing down overall operations. Disabling hardware boost clocks to run all cluster GPUs at a lower base frequency reduces the performance of the busy GPUs to normalize them with the idle ones, which decreases the performance of the entire cluster rather than utilizing the idle capacity.