
You are architecting a multi-node GPU cluster to train a trillion-parameter Large Language Model. Because the model must be distributed across hundreds of GPUs in different physical servers, the nodes must continuously synchronize billions of model weights during backpropagation. Which networking characteristic is absolutely vital to prevent inter-node communication from bottlenecking the entire training cluster?
Select an answer to reveal the explanation.
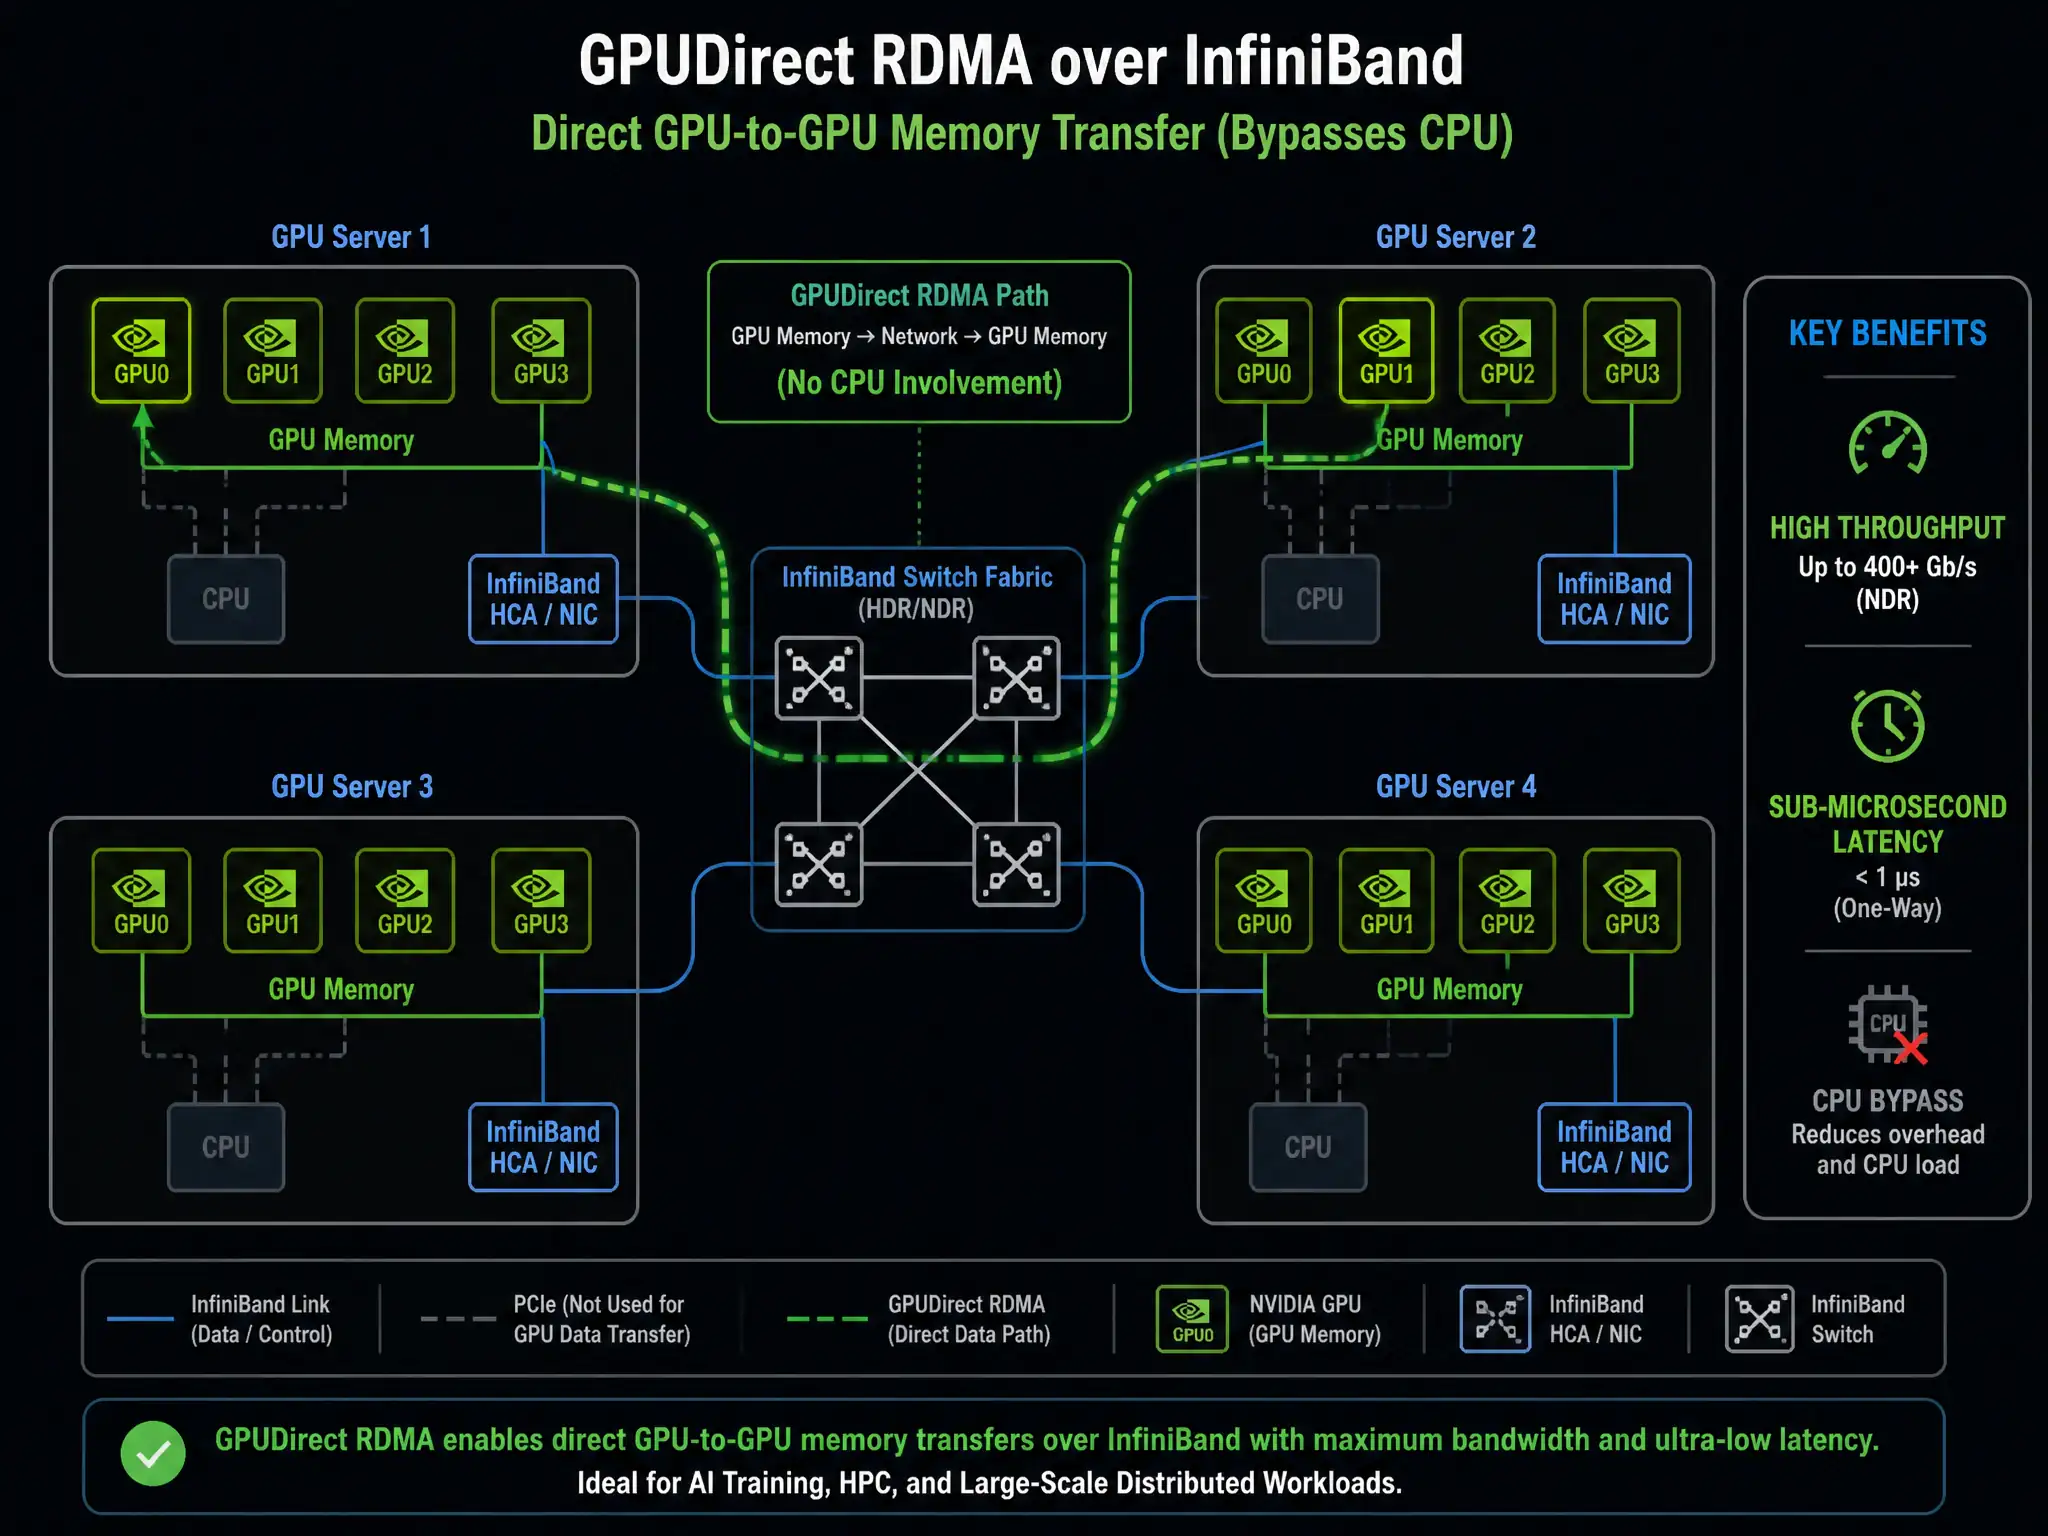
Short Explanation
When you train a trillion-parameter model across hundreds of GPUs, the network has to keep those GPUs fed. You need massive throughput and sub-microsecond latency so gradient and weight syncs don't stall the whole cluster. Anything slower turns your expensive GPUs into idle traffic cops.
Full Explanation
Distributed deep learning training uses techniques like data parallelism, model parallelism, and pipeline parallelism to train large models across multiple physical nodes. During backpropagation, nodes must continuously perform collective communication operations (such as AllReduce, AllGather, and ReduceScatter) to synchronize gradients and model parameters.
Because these operations occur in synchronous loops, the training speed of the entire cluster is bottlenecked by the slowest network link (the 'tail latency' problem). To achieve efficient scaling, the network interface must support high bandwidth, typically 400 Gbps to 800 Gbps per link using technologies like InfiniBand or high-speed Ethernet to move gigabytes of weight parameters quickly; ultra-low latency in the sub-microsecond or low-microsecond range to minimize synchronization wait times; and RDMA (Remote Direct Memory Access), allowing GPUs to transfer data directly from their memory to the memory of a remote GPU without involving the operating system or CPU on either end (using GPUDirect RDMA). High bandwidth combined with sub-microsecond latency between the compute nodes is therefore the vital characteristic.
The option that relies on standard Wi-Fi 6E/7 access points for flexible server placement is wrong because Wi-Fi lacks the bandwidth (caps at a few Gbps), has high latency, and suffers from packet collision and signal degradation, making it completely unsuitable for high-performance computing clusters.
The option that uses redundant physical paths configured using standard spanning-tree loop prevention protocols is wrong because, while physical path redundancy and loops are concerns in traditional enterprise networking, standard Spanning Tree Protocol shuts down active paths, reducing usable bandwidth. Modern high-performance fabrics use active-active multi-pathing or InfiniBand routing (which does not use STP) to maximize bandwidth.
The option that calls for strict network segmentation to isolate administrative traffic from user workloads is wrong because network segmentation isolates administrative traffic for security, but it does not address the core data transfer performance requirements of the model training workload.