
An engineering group is evaluating hardware accelerators for a deep learning project that requires massive tensor matrix multiplications. When comparing a high-end CPU to an enterprise GPU, which architectural difference makes the GPU significantly faster for executing these machine learning calculations?
Select an answer to reveal the explanation.
Short Explanation
You need the GPU because it's built with thousands of smaller cores that chew through matrix math in parallel. The CPU is fast at one complex task, but deep learning needs tons of simple calculations at once. Don't be fooled by power or single-thread myths—the win is parallelism.
Full Explanation
The fundamental difference between central processing units and graphics processing units lies in their design philosophies, which are optimized for different types of computational tasks.
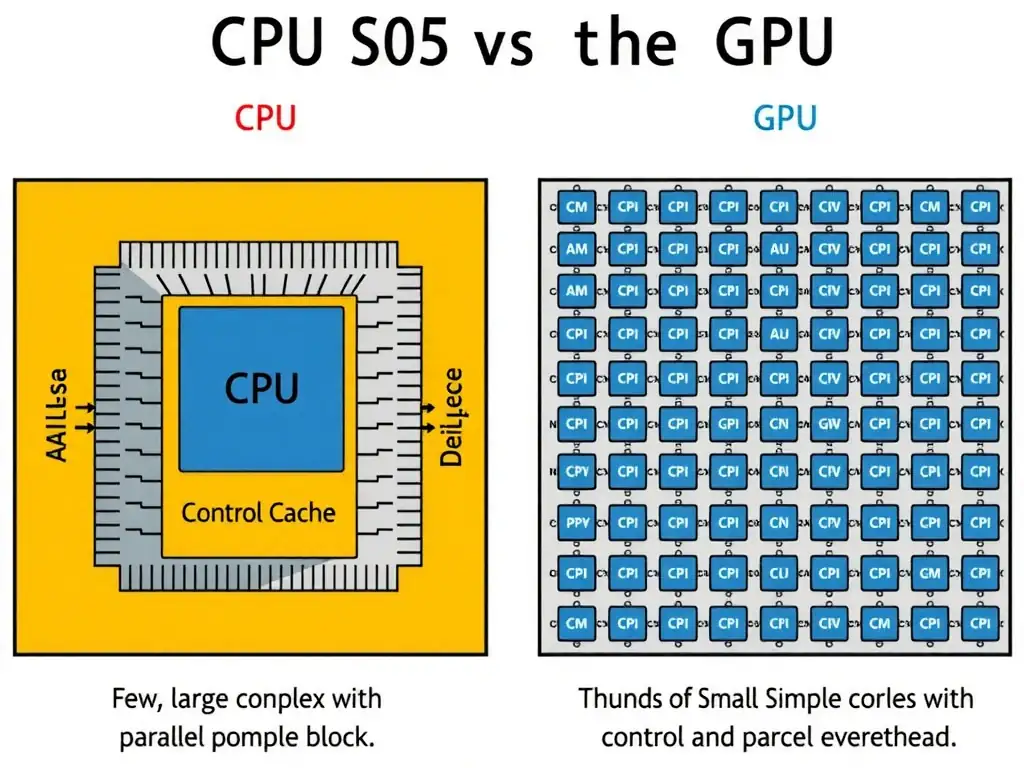
The central processing unit is designed for sequential processing and low-latency execution of complex serial instruction sets. It features a small number of powerful execution cores, large cache hierarchies including level-one, level-two, and level-three caches, and complex control logic such as branch prediction and out-of-order execution. This makes it highly efficient at running operating systems, databases, and serial application code.
The graphics processing unit, conversely, is built for compute-intensive, highly parallel operations. It features a latency-tolerant, high-throughput architecture consisting of thousands of smaller, simpler cores designed to execute the same instruction simultaneously across multiple data points, using single instruction, multiple data or single instruction, multiple threads models. Because deep learning workloads consist primarily of dense matrix mathematics, such as matrix multiplication and convolution operations, that can be computed independently, the graphics processing unit's parallel architecture can process these arrays magnitudes faster than the central processing unit.
The claim that graphics processing units use a sequential architecture with massive level-one and level-two caches to speed up data access loops is wrong because central processing units rely on large caches to reduce memory latency, while graphics processing units dedicate most of their die area to arithmetic logic units rather than large cache structures or complex control units.
The claim that graphics processing units have higher single-thread instruction throughput and clock speeds than central processing units is wrong because central processing units have much higher clock frequencies and far superior single-thread performance compared with individual graphics processing unit cores, which are relatively slow when executing serial tasks.
The claim that graphics processing units draw less peak power per execution unit, reducing thermal overhead during complex calculations, is wrong because under load high-performance graphics processing units draw significant amounts of power, often 300 watts to 700 watts or more per card, and require robust power delivery and cooling systems. While they are more energy-efficient per computation for parallel workloads, they are not inherently low-power devices.
Therefore, the graphics processing unit's highly parallel design with thousands of cores is the primary reason it excels at deep learning workloads.