
An enterprise AI data center requires maximum uptime for its large-scale inference and training services. To ensure high availability and minimal disruption during a hardware failure or maintenance window, which architectural design combines GPU clustering with Data Processing Units (DPUs)?
Select an answer to reveal the explanation.
Short Explanation
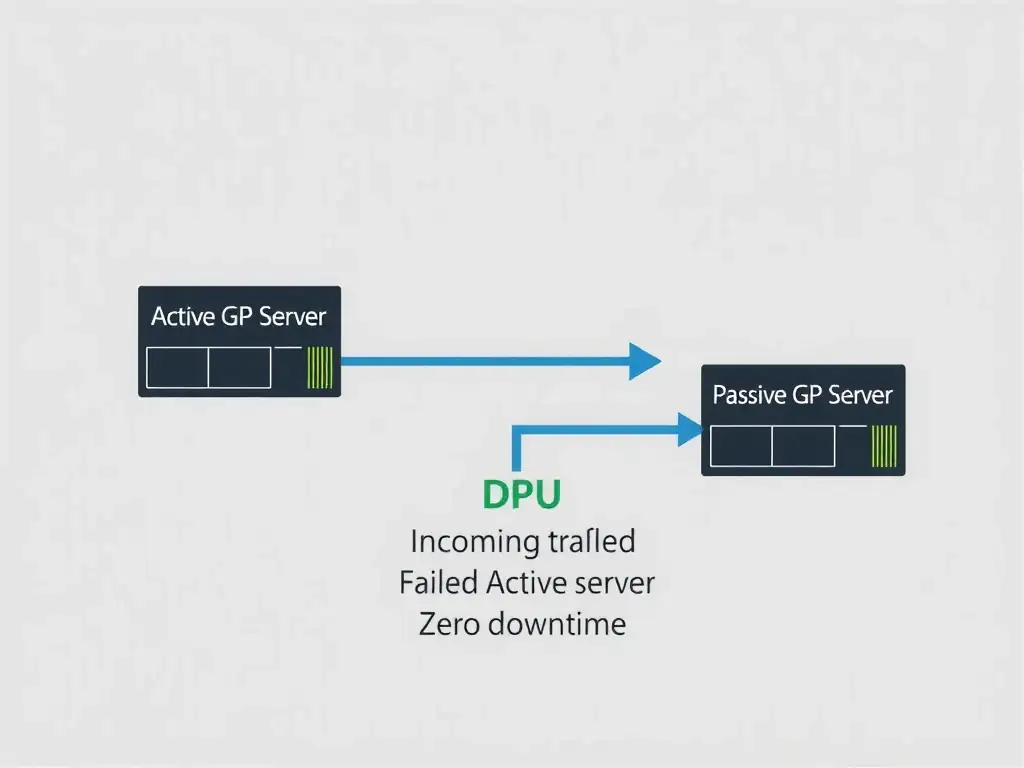
You never want a single point of failure. Pair active-passive GPU clustering with DPUs so standby nodes are ready to take over while DPUs handle routing, security, and instant failover. That's how you keep AI services running 24/7.
Full Explanation
High availability (HA) in modern AI data centers is critical for maintaining SLA-backed services like real-time LLM inference, autonomous driving processing, and financial forecasting. Achieving HA requires redundancy at both the compute (GPU) and network layers.
The optimal strategy involves deploying GPUs in an active-passive clustering configuration, coordinated by Data Processing Units (DPUs) such as NVIDIA BlueField. In this design: 1. Active-Passive Clustering: Active GPU nodes handle the primary computation. Standby (passive) GPU nodes are kept synchronized and ready to take over workloads if an active node fails or undergoes scheduled maintenance. 2. DPU-Offloaded Failover: DPUs act as smart network interfaces that sit in front of the servers. They run their own lightweight operating systems and handle tasks like virtual routing, encryption, firewalling, and telemetry. Because the DPU manages the network interface independent of the host CPU and GPU, it can detect host failures immediately. Upon detecting a failure, the DPU updates routing tables and redirects incoming network traffic to the passive standby node with sub-millisecond latency. This architecture keeps the data plane separate from the control plane, ensuring continuous operations without interrupting the client.
The single-large-GPU-node design with CPU-emulated software failover over standard gigabit copper Ethernet is incorrect because it lacks hardware redundancy. If the node fails, the service goes down. CPU-emulated failover over standard gigabit copper Ethernet is far too slow and lacks the necessary bandwidth for AI data streams.
The active-active GPU design where DPUs are disabled to prevent packet overhead during deep learning training is incorrect because disabling DPUs would force the host CPU and GPU to handle network routing, packet parsing, and security tasks. This introduces latency, reduces the GPU compute capacity available for AI tasks, and removes the offloaded failover capabilities.
The design that runs all workloads on virtualized CPUs while using GPUs solely for background logging and system health diagnostics is incorrect because CPUs are not suitable for running heavy deep learning workloads at scale. Using GPUs only for background diagnostics is a massive waste of accelerated hardware resources.