
A data science team wants to accelerate their entire machine learning workflow—including data ingestion, preprocessing (dataframes), and model training (e.g., XGBoost, K-means)—directly on GPUs without abandoning their existing Python-based APIs. Which open-source NVIDIA suite of libraries should they adopt?
Select an answer to reveal the explanation.
Short Explanation
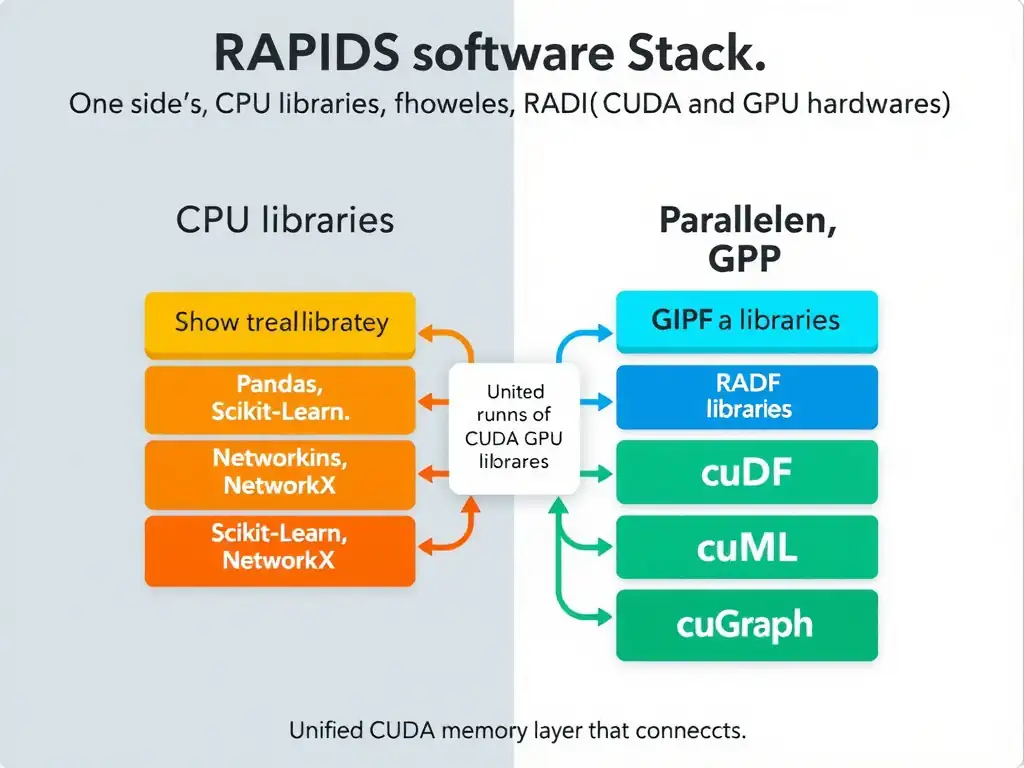
You want NVIDIA RAPIDS because it gives you GPU-accelerated drop-in replacements for Pandas, Scikit-Learn, and NetworkX while keeping the Python APIs you already know. It speeds up dataframes, feature engineering, and model training like XGBoost and K-means without forcing you to rewrite everything. Trust me, once you go RAPIDS, you'll never want to wait on a CPU again.
Full Explanation
Data science workflows typically involve several stages: data loading, cleaning, feature engineering, model training, and visualization. Traditionally, these stages are executed on CPUs using libraries such as Pandas for data manipulation, Scikit-Learn for machine learning algorithms, and NetworkX for graph analytics. As datasets grow into gigabytes or terabytes, these CPU-bound libraries become major bottlenecks.
NVIDIA RAPIDS is an open-source suite of software libraries and APIs designed to execute end-to-end data science pipelines entirely on GPUs. It achieves this by providing GPU-accelerated drop-in replacements for standard Python data science libraries: cuDF replaces Pandas for DataFrame operations, providing up to 10x-100x speedups; cuML replaces Scikit-Learn for machine learning algorithms such as Random Forests, K-means, and XGBoost; and cuGraph replaces NetworkX for parallel graph analysis. By leveraging GPU parallelism and high-speed HBM (High Bandwidth Memory), RAPIDS minimizes the overhead of moving data between CPU host memory and GPU device memory. This allows data scientists to build, train, and deploy machine learning models at scale with drastically reduced execution times.
The NVIDIA CUDA-X choice is a broader collection of libraries, tools, and technologies built on top of CUDA, such as cuBLAS, cuDNN, and TensorRT. It is not a dedicated data science and machine learning library suite like RAPIDS. The NVIDIA TensorRT choice is an SDK for high-performance deep learning inference. It optimizes trained deep learning models for deployment on GPUs but does not handle data preprocessing, tabular manipulations, or traditional machine learning algorithms like RAPIDS does. The NVIDIA Riva choice is a GPU-accelerated SDK for building conversational AI applications, such as automatic speech recognition (ASR) and text-to-speech (TTS), which is unrelated to general data analytics and machine learning pipeline acceleration.