
You're working with a data science team on a transaction dataset with over five hundred features. Before you feed this mountain of data into your model, your lead data scientist tells you to prune the features to improve training speed and prevent overfitting. You need to identify and strip out redundant variables that carry duplicate information. Which feature selection technique should you use?
Select an answer to reveal the explanation.
Short Explanation
Here's the deal: more data isn't always better. You need to find and drop features that duplicate each other, so correlation analysis is the right move. Random sampling, skipping selection, or squashing everything into one component either risks losing signal or destroys detail.
Full Explanation
In machine learning, feature selection is a critical preprocessing step, particularly when dealing with high-dimensional datasets. Feeding too many variables into a model can cause the curse of dimensionality, where the model overfits to noise in the training data, struggles to generalize, and requires excessive compute resources to train.
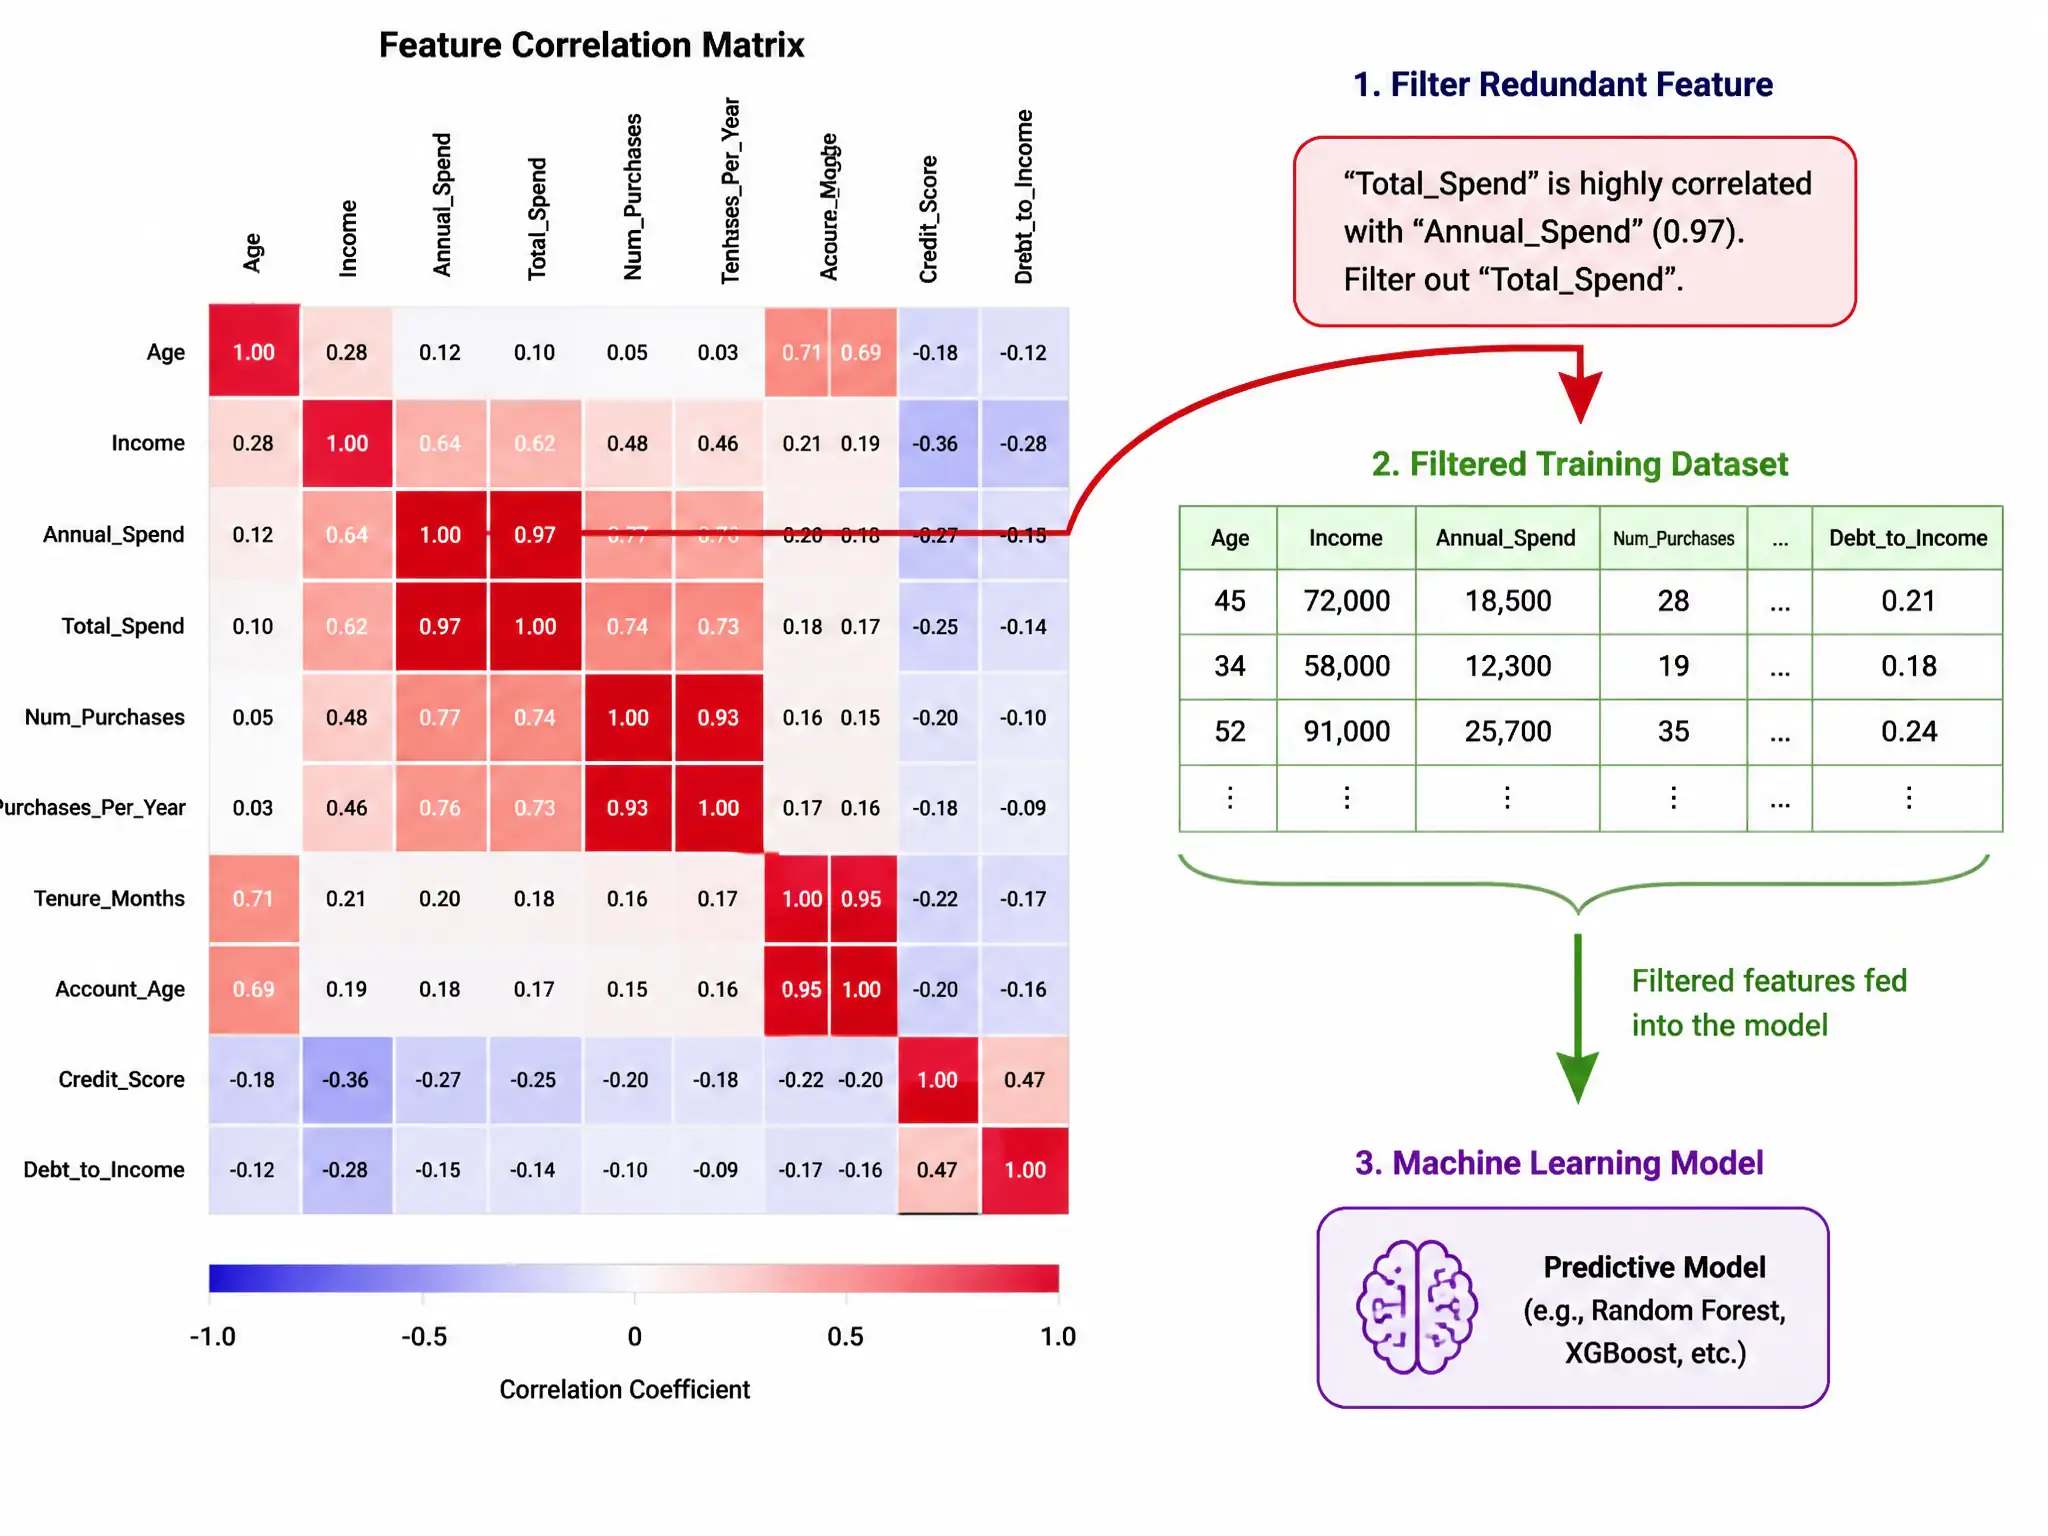
Correlation analysis is an effective statistical technique for feature selection. It calculates the correlation coefficient, such as Pearson's or Spearman's, between all pairs of numerical features in the dataset. When two features exhibit a high correlation, close to 1.0 or -1.0, they are collinear, meaning they carry redundant information. By identifying these collinear pairs and removing one of the redundant features, you minimize multicollinearity, which improves the stability and interpretability of model coefficients; reduce the dimensionality of the input space without losing significant unique information; and lower the training and inference time of the model.
Evaluating the incorrect approaches: - The random sampling approach has no statistical basis and risks discarding critical predictive features while keeping irrelevant noise. - The skip-selection approach leads to sub-optimal model performance and high training latency. - The Principal Component Analysis approach is a dimensionality reduction technique that projects features into a new space of principal components. Compressing hundreds of features into a single component throws away the vast majority of the dataset's variance, rendering any subsequent model ineffective. Furthermore, Principal Component Analysis is a feature extraction method, not a feature selection method, as it transforms the input variables, making the resulting model less interpretable.
Thus, correlation analysis provides a systematic and interpretable method for removing redundant features.