
You're deploying a machine learning model to spot credit card fraud in real time. Fraudsters are smart—they constantly change their tactics, meaning a model that works great today might be completely useless next month due to data drift. To make sure your fraud detection system stays sharp and adapts to these changing tricks on the fly, how should you structure your training pipeline?
Select an answer to reveal the explanation.
Short Explanation
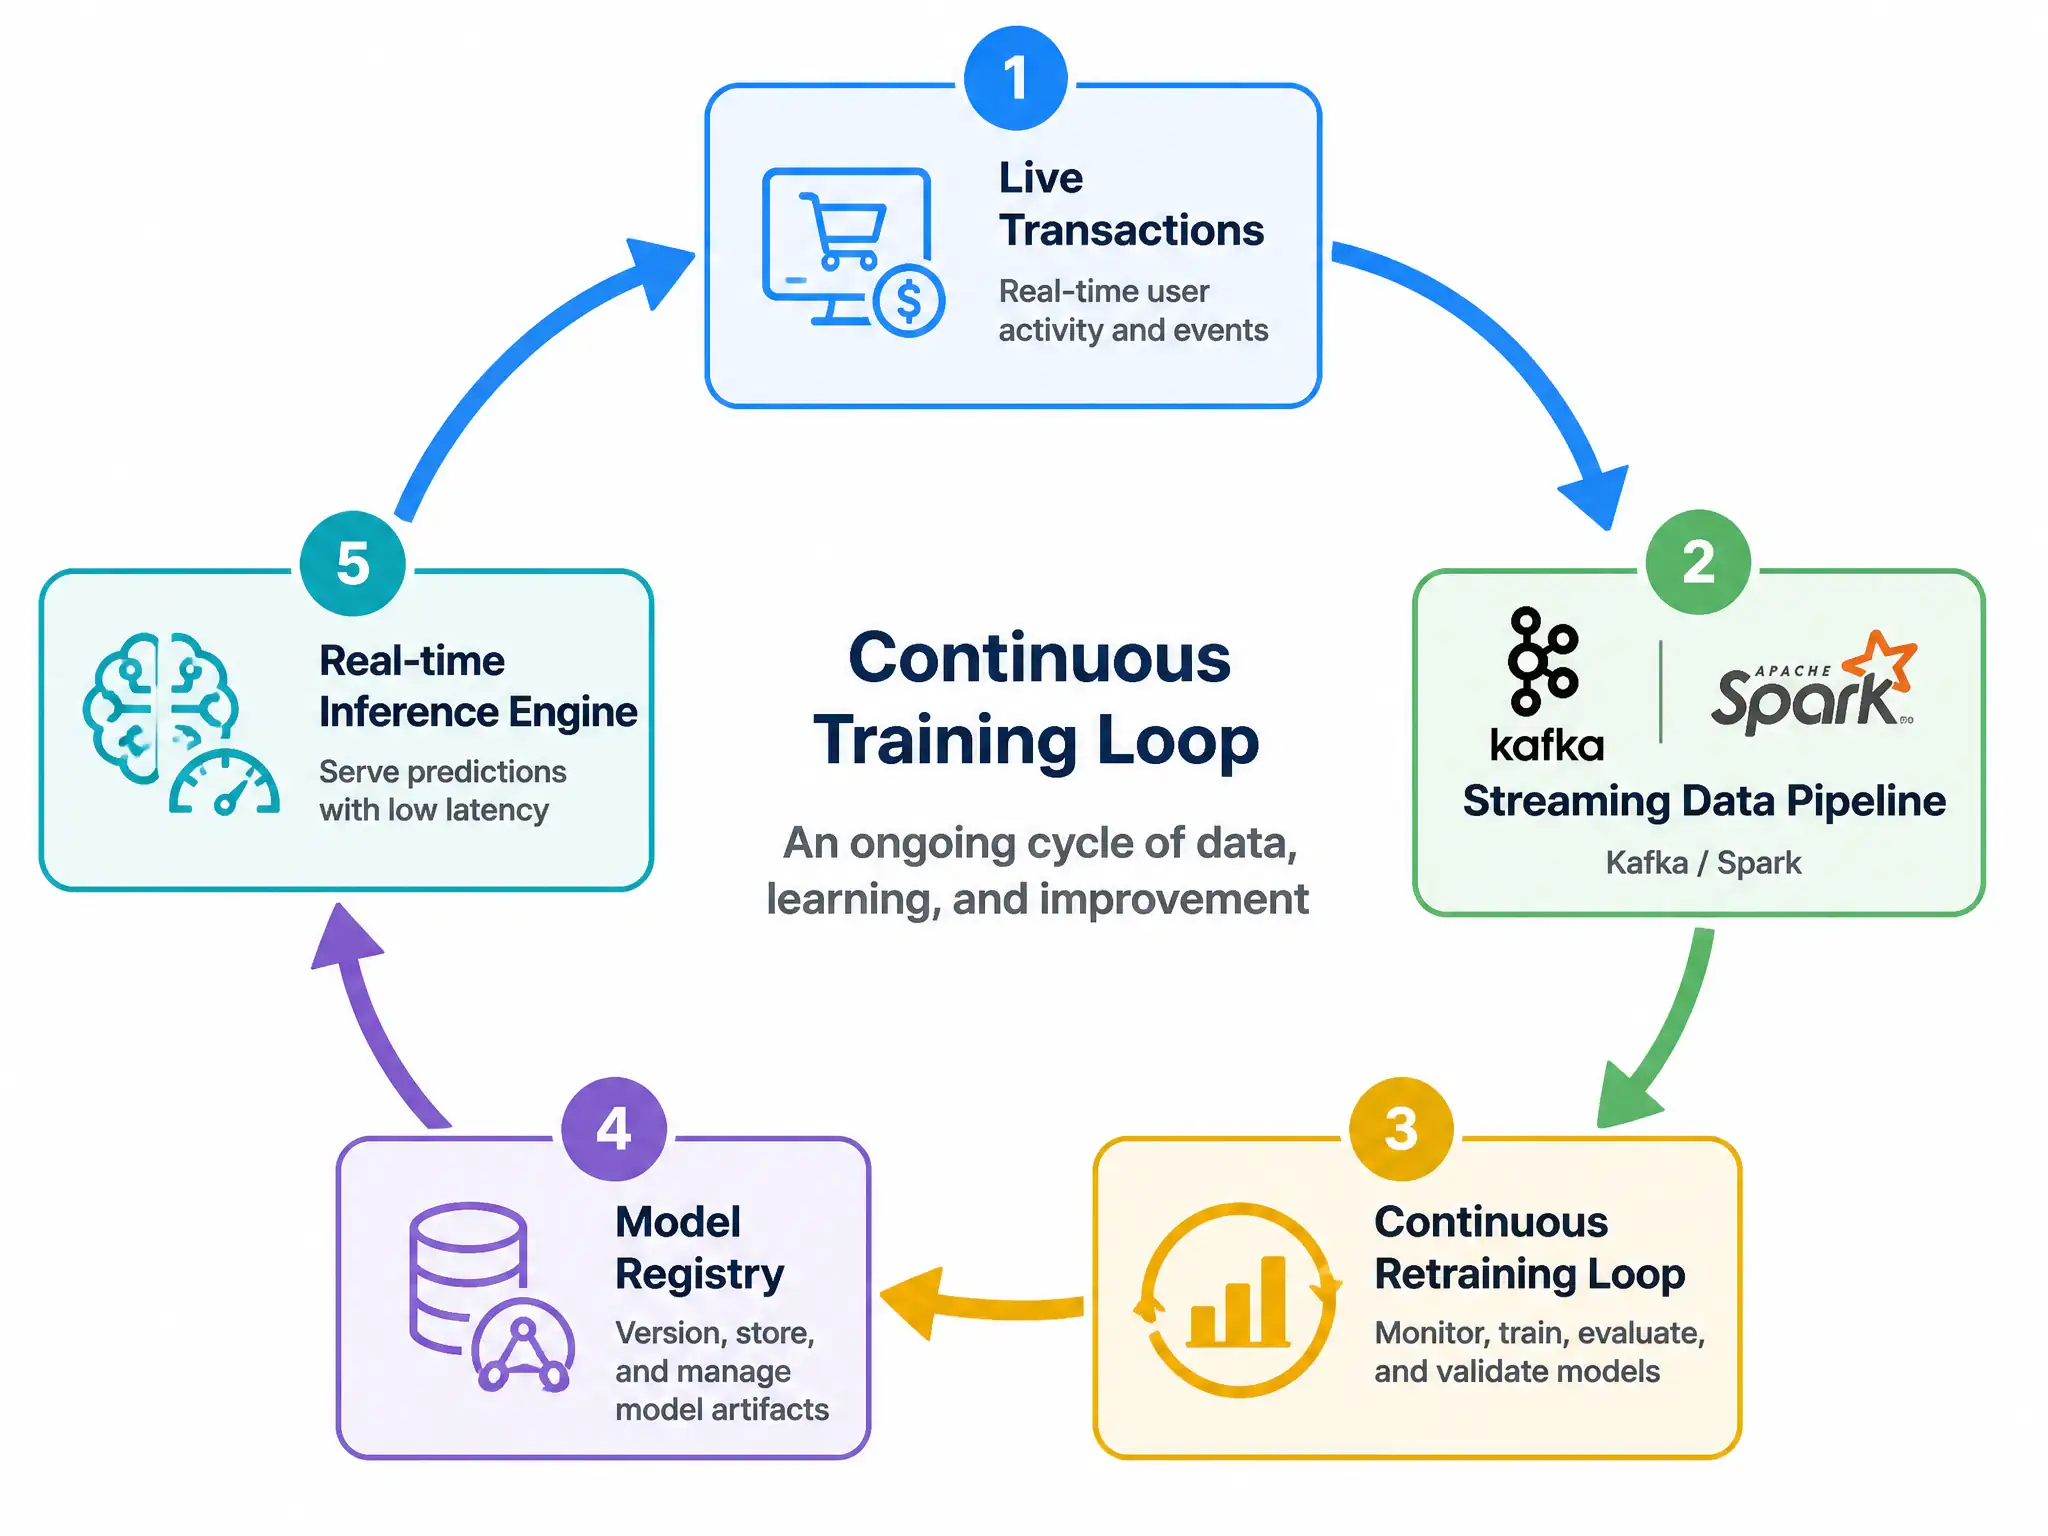
In fraud detection, the bad guys keep moving the goalposts. If you deploy a model and leave it alone, or retrain it on stale monthly data, you'll get cleaned out. A streaming data pipeline feeds fresh transactions into the training loop continuously, so the model adapts to new tricks in near real time.
Full Explanation
In real-world machine learning deployments, data drift and concept drift represent significant challenges. Concept drift occurs when the statistical properties of the target variable change over time, rendering a model trained on historical data increasingly inaccurate. In adversarial domains like credit card fraud detection, this drift is accelerated by bad actors actively trying to evade detection.
To address concept drift, organizations must implement a continuous retraining architecture using a streaming data pipeline. This architecture continuously ingests new transactional data, labels it via feedback loops, chargebacks, or manual reviews, and updates the model's weights in near real-time. This continuous loop ensures that the model learns new fraudulent patterns as they emerge, maintaining high precision and recall.
Analyzing the alternative methods: - The approach that deploys the initial model and only triggers a rebuild when a major breach occurs—or only after a significant accuracy drop—is a reactive strategy. By the time a metric drop or breach is identified at scale, significant financial damage has already occurred. - The monthly retraining job using a fixed, historically archived dataset creates a lag between the emergence of a new fraud tactic and the model's ability to recognize it. During this lag window, the system is highly vulnerable. - Running the model alongside a static, rule-based system helps catch known, static fraud patterns, but it does not prevent the underlying machine learning model from becoming stale and obsolete.
Continuous training via streaming data pipelines is the standard design pattern for maintaining model relevance in highly dynamic environments.