
After modifying an AHV bond and management bridge on a Nutanix cluster, one CVM becomes unreachable from Prism Element, while VMs on other VLANs remain reachable. Which action best isolates the management-plane connectivity problem?
Select an answer to reveal the explanation.
Short Explanation
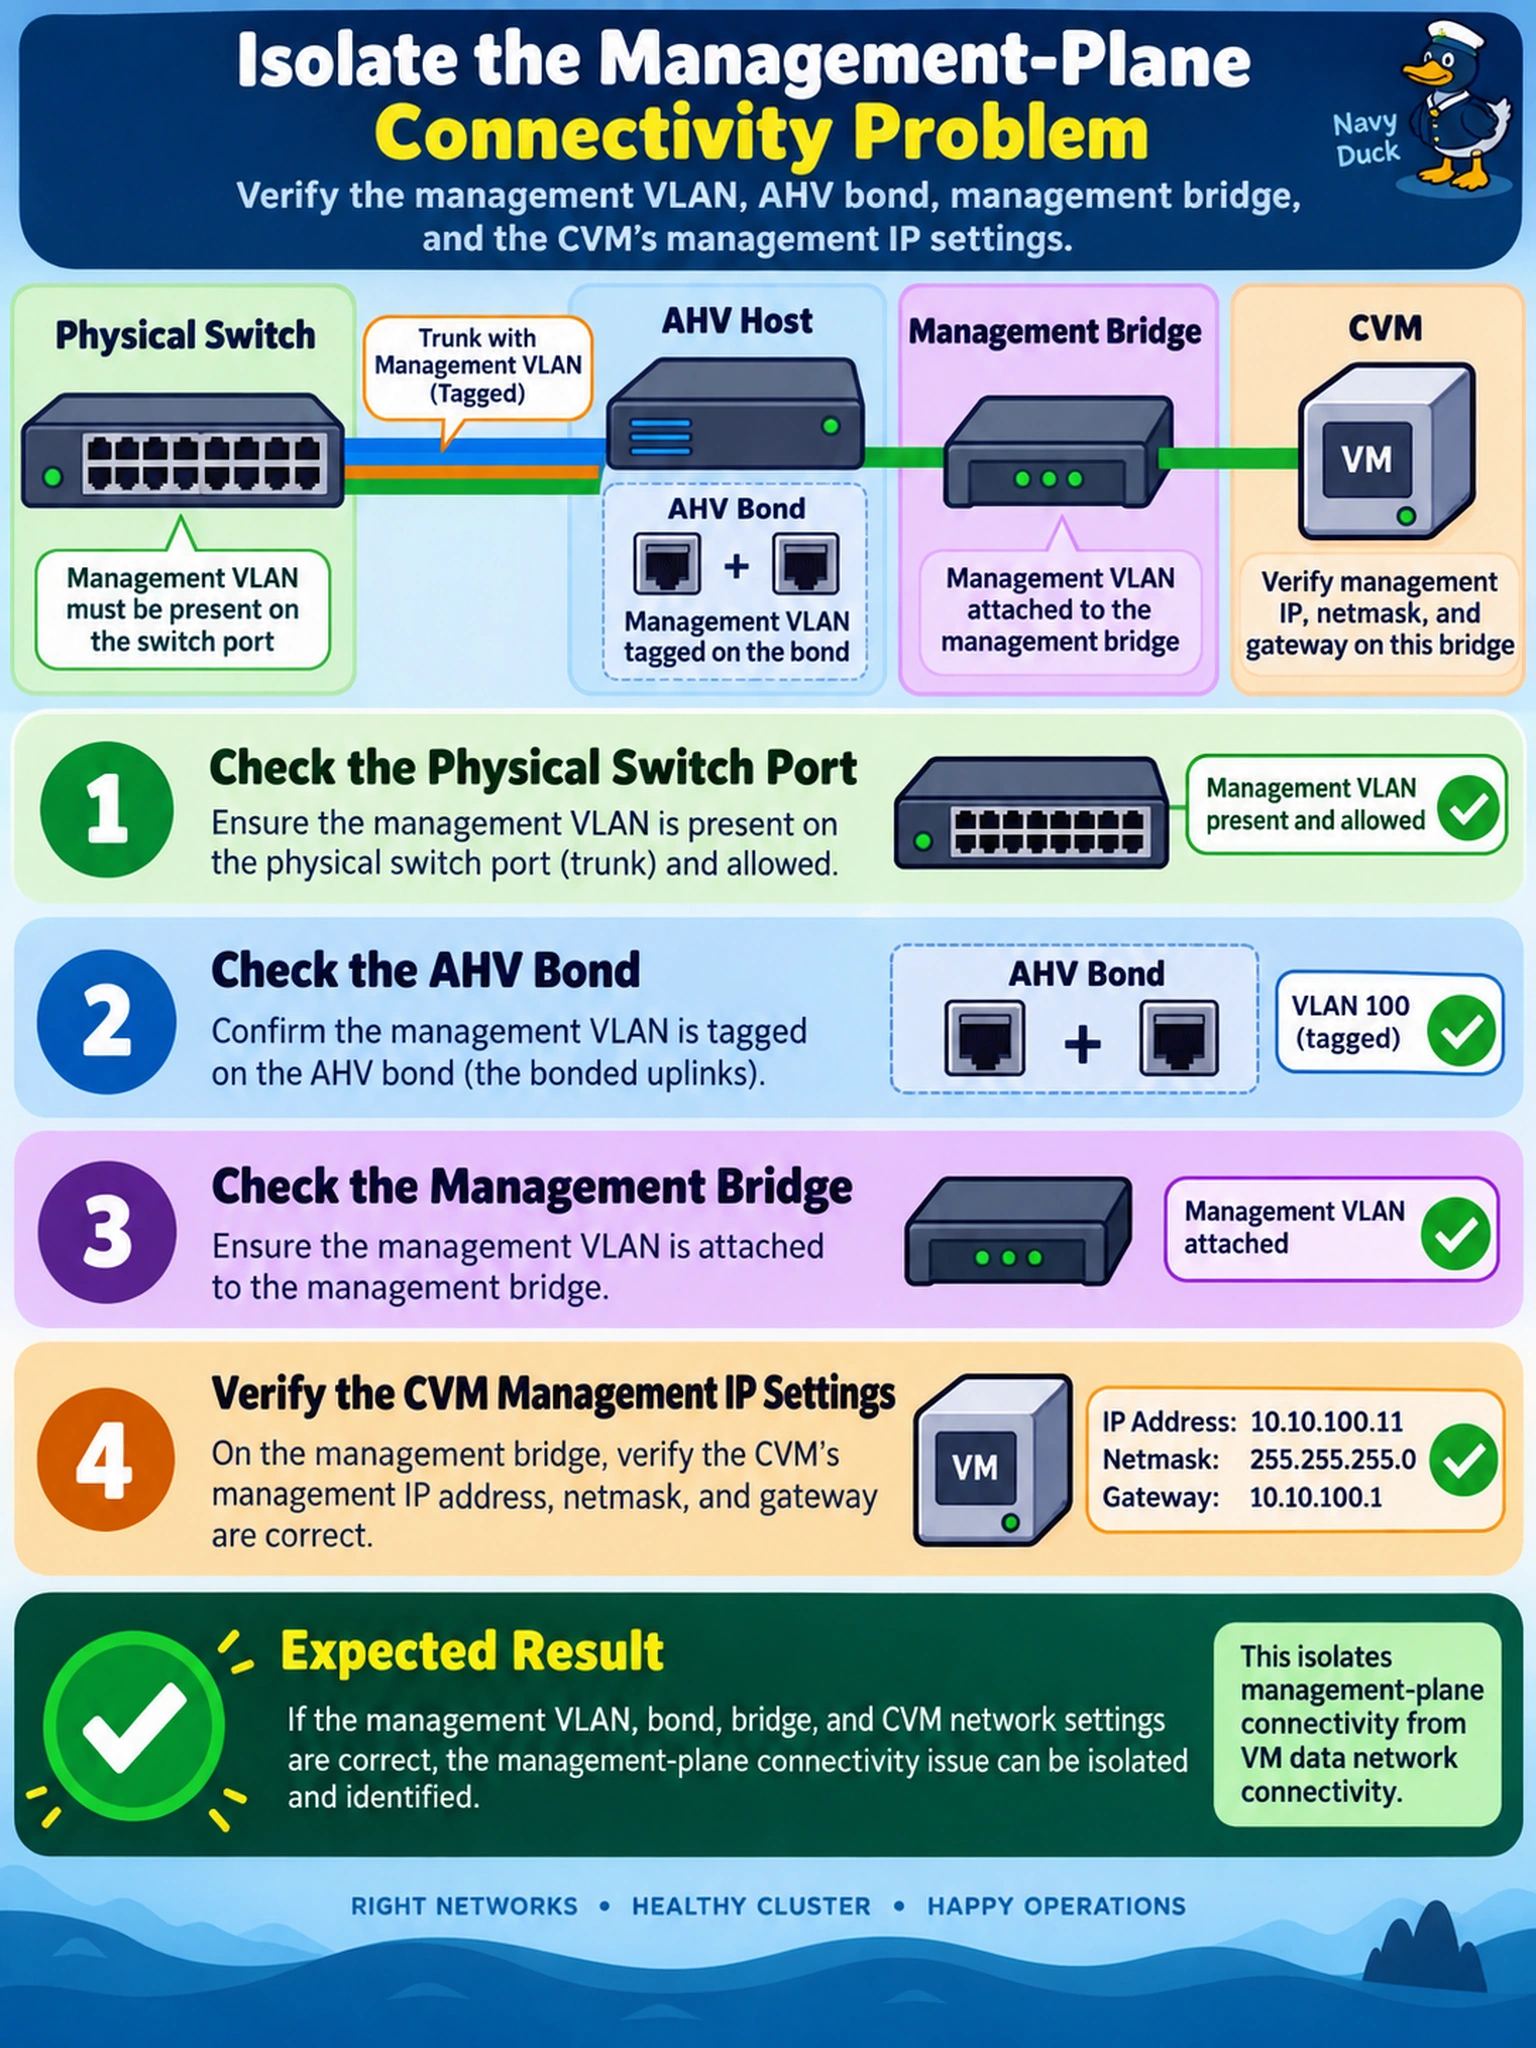
Think of it like this: if you move a CVM to a new VLAN but don't tag the bond or bridge, the management packet never leaves the host. You need to trace the path from physical VLAN to bridge to CVM IP before blaming services.
Full Explanation
A management CVM relies on a clear Layer 2 path from its management interface to the gateway. When a bond or bridge changes, the first failure point is usually VLAN membership: the switch port must permit the management VLAN, the AHV bond must tag or carry it, and the management bridge must include that VLAN before the CVM's static or DHCP address can communicate. The CVM's IP address, netmask, and gateway must also remain aligned with the new bridge and subnet. Restarting the CVM may restore a service, but it does not repair a missing VLAN tag or bridge attachment, so it can mask the underlying network misconfiguration. Enabling Flow gateway or assigning a floating IP addresses workload or cluster VIP behavior, not the CVM's own management interface reachability. Running Cassandra and Zookeeper health checks is useful for cluster quorum symptoms, yet those checks do not validate the physical VLAN, bond, or bridge path that just changed. Exam caveat: treat CVM unreachable after a network change as a connectivity isolation problem first, not a cluster database outage. Operational check: from the AHV host, confirm the management bridge and bond VLAN configuration, then ping or test the CVM management gateway and IP from the intended management network.