
A bead-furnace project “uses the GPU” through a modern deep learning framework. What does that imply for associate work?
Select an answer to reveal the explanation.
Short Explanation
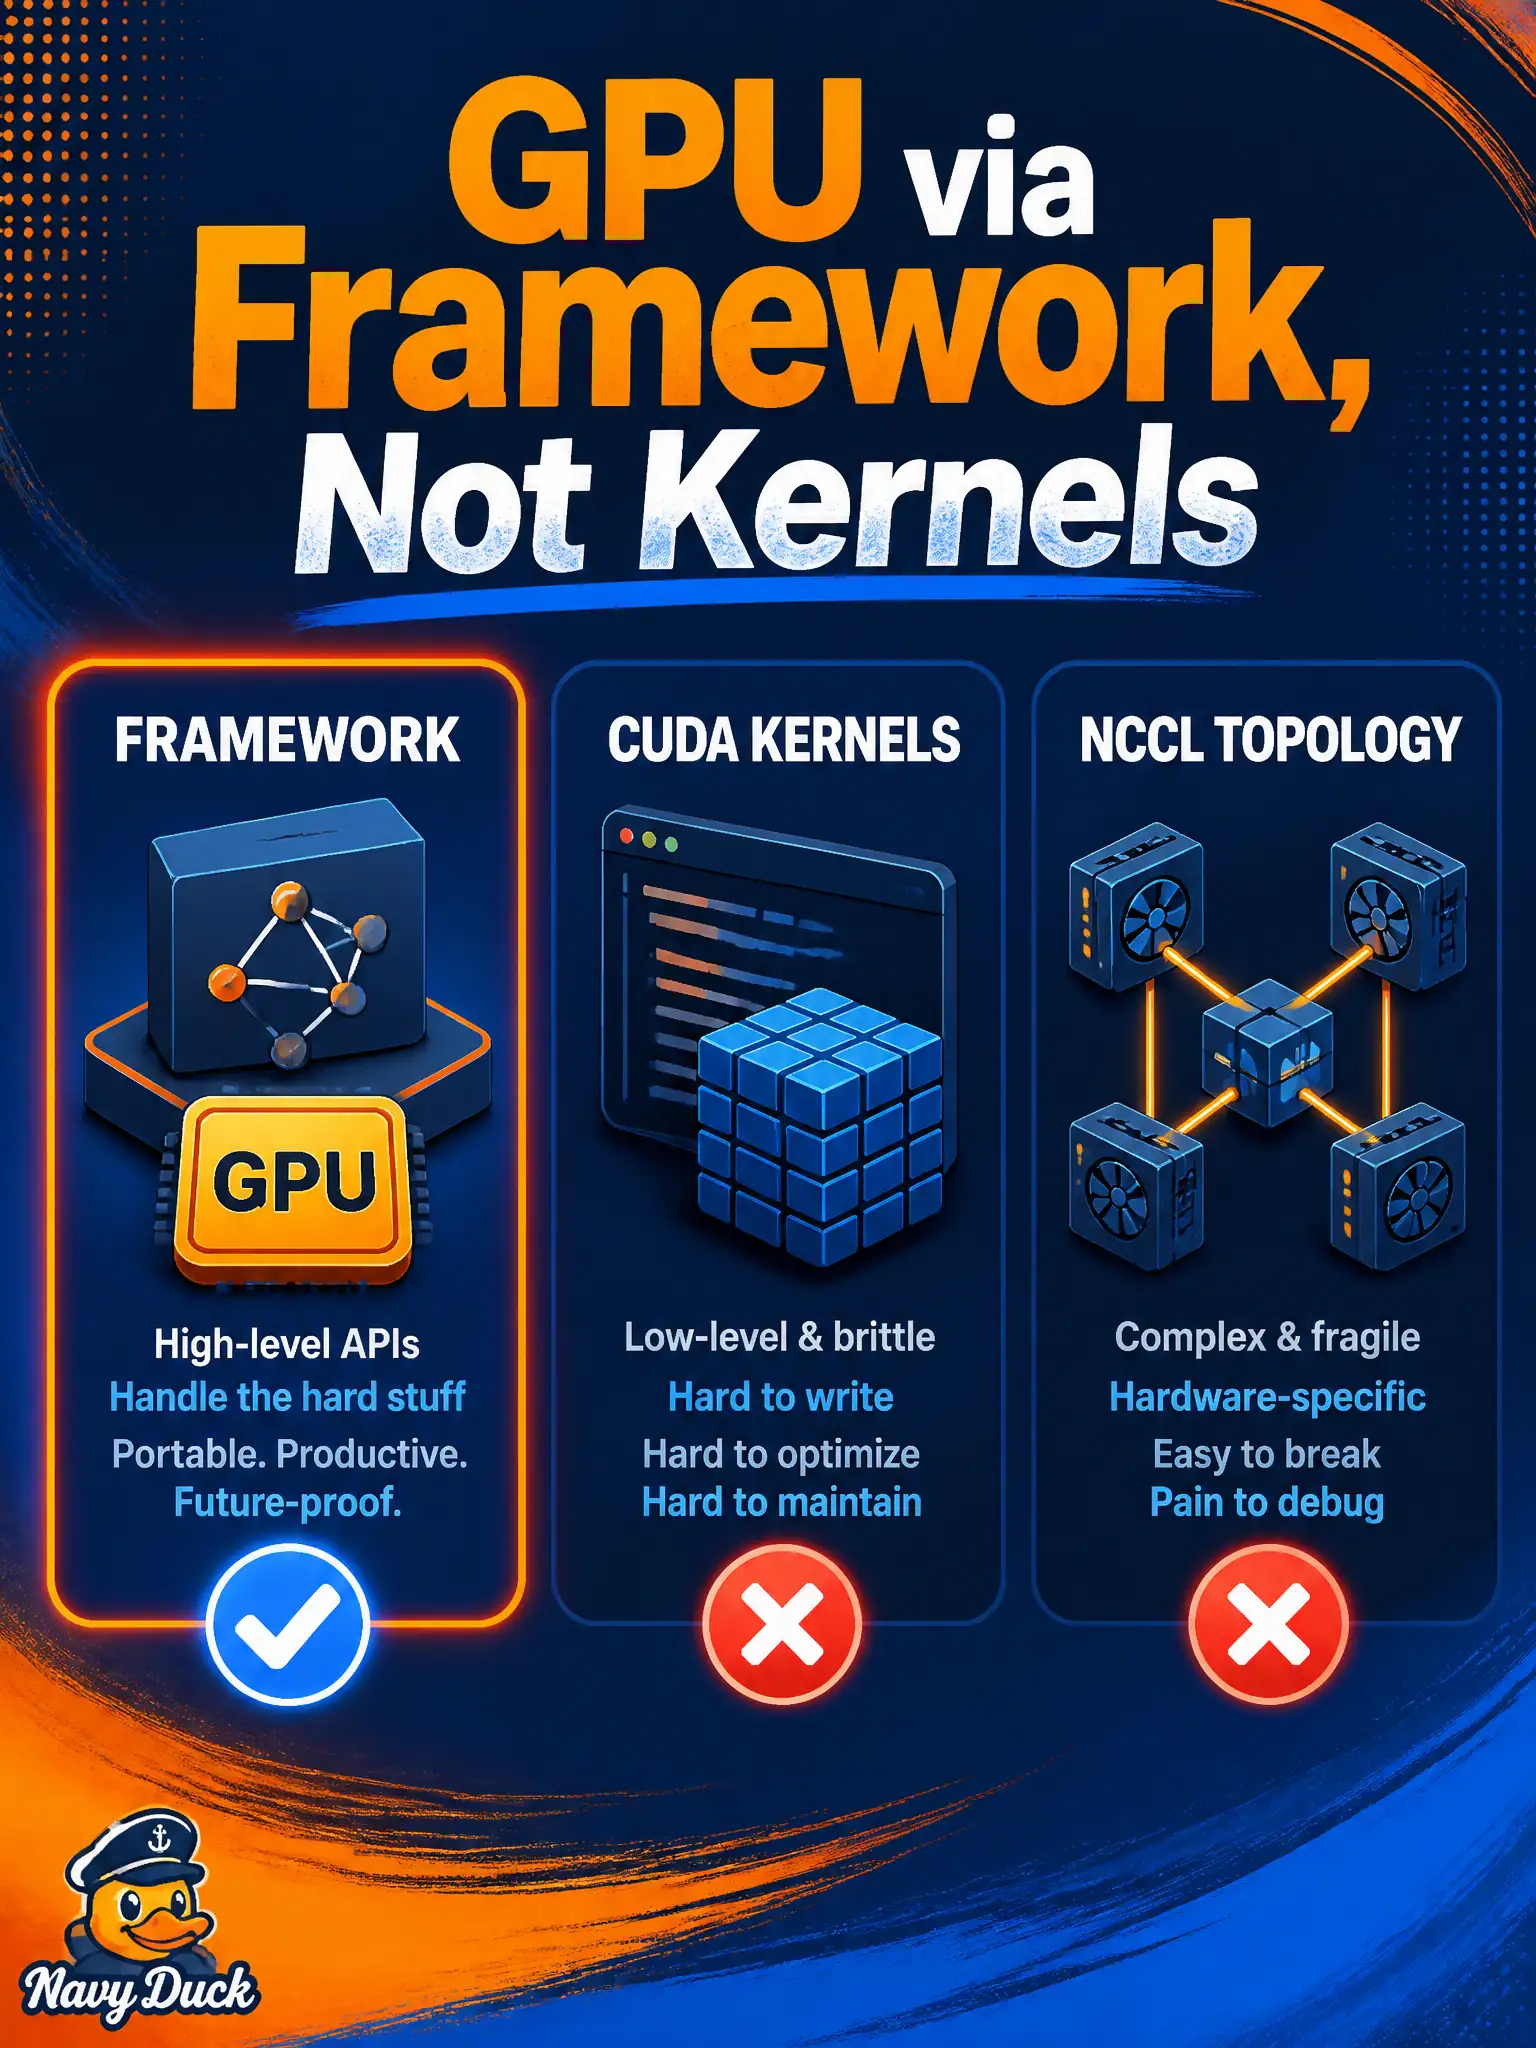
Letting the framework drive the GPU is CUDA awareness with training wheels—allowed and expected. You’re still not writing kernels or drawing NCCL maps.
Full Explanation
Using the GPU through a modern deep learning framework implies GPU-accelerated framework execution is fine; do not turn the item into kernel or NCCL work. That implication is correct for the bead-furnace project and civic multimodal apps that rightly use GPUs without becoming CUDA courses.
Requiring a handwritten CUDA kernel before the first forward pass fails associate scope. Forbidding framework GPU use until an NCCL topology diagram is submitted fails similarly. Claiming GPU use forces immediate Domain 6 Helm migration fails domain sequencing.
Exam caveat: framework GPU use is allowed and expected; kernels/NCCL are out. Operational check: run civic training/inference on GPUs via the framework; reject kernel/NCCL tickets filed as NCA-GENM associate tasks. Align this choice with the agency’s published multimodal runbook so civic operators can audit why the configuration was accepted. Record the civic software choice in the service README—named modules, inputs, and domain—so operators can replay the same path during audits and handoffs. Prefer explicit, reversible civic decisions over silent assumptions when multimodal data or software paths move toward production. Review the decision in the next multimodal working group.