
A button mill already has a stills loader and needs a text arm for care sentences. How should that text module be added?
Select an answer to reveal the explanation.
Short Explanation
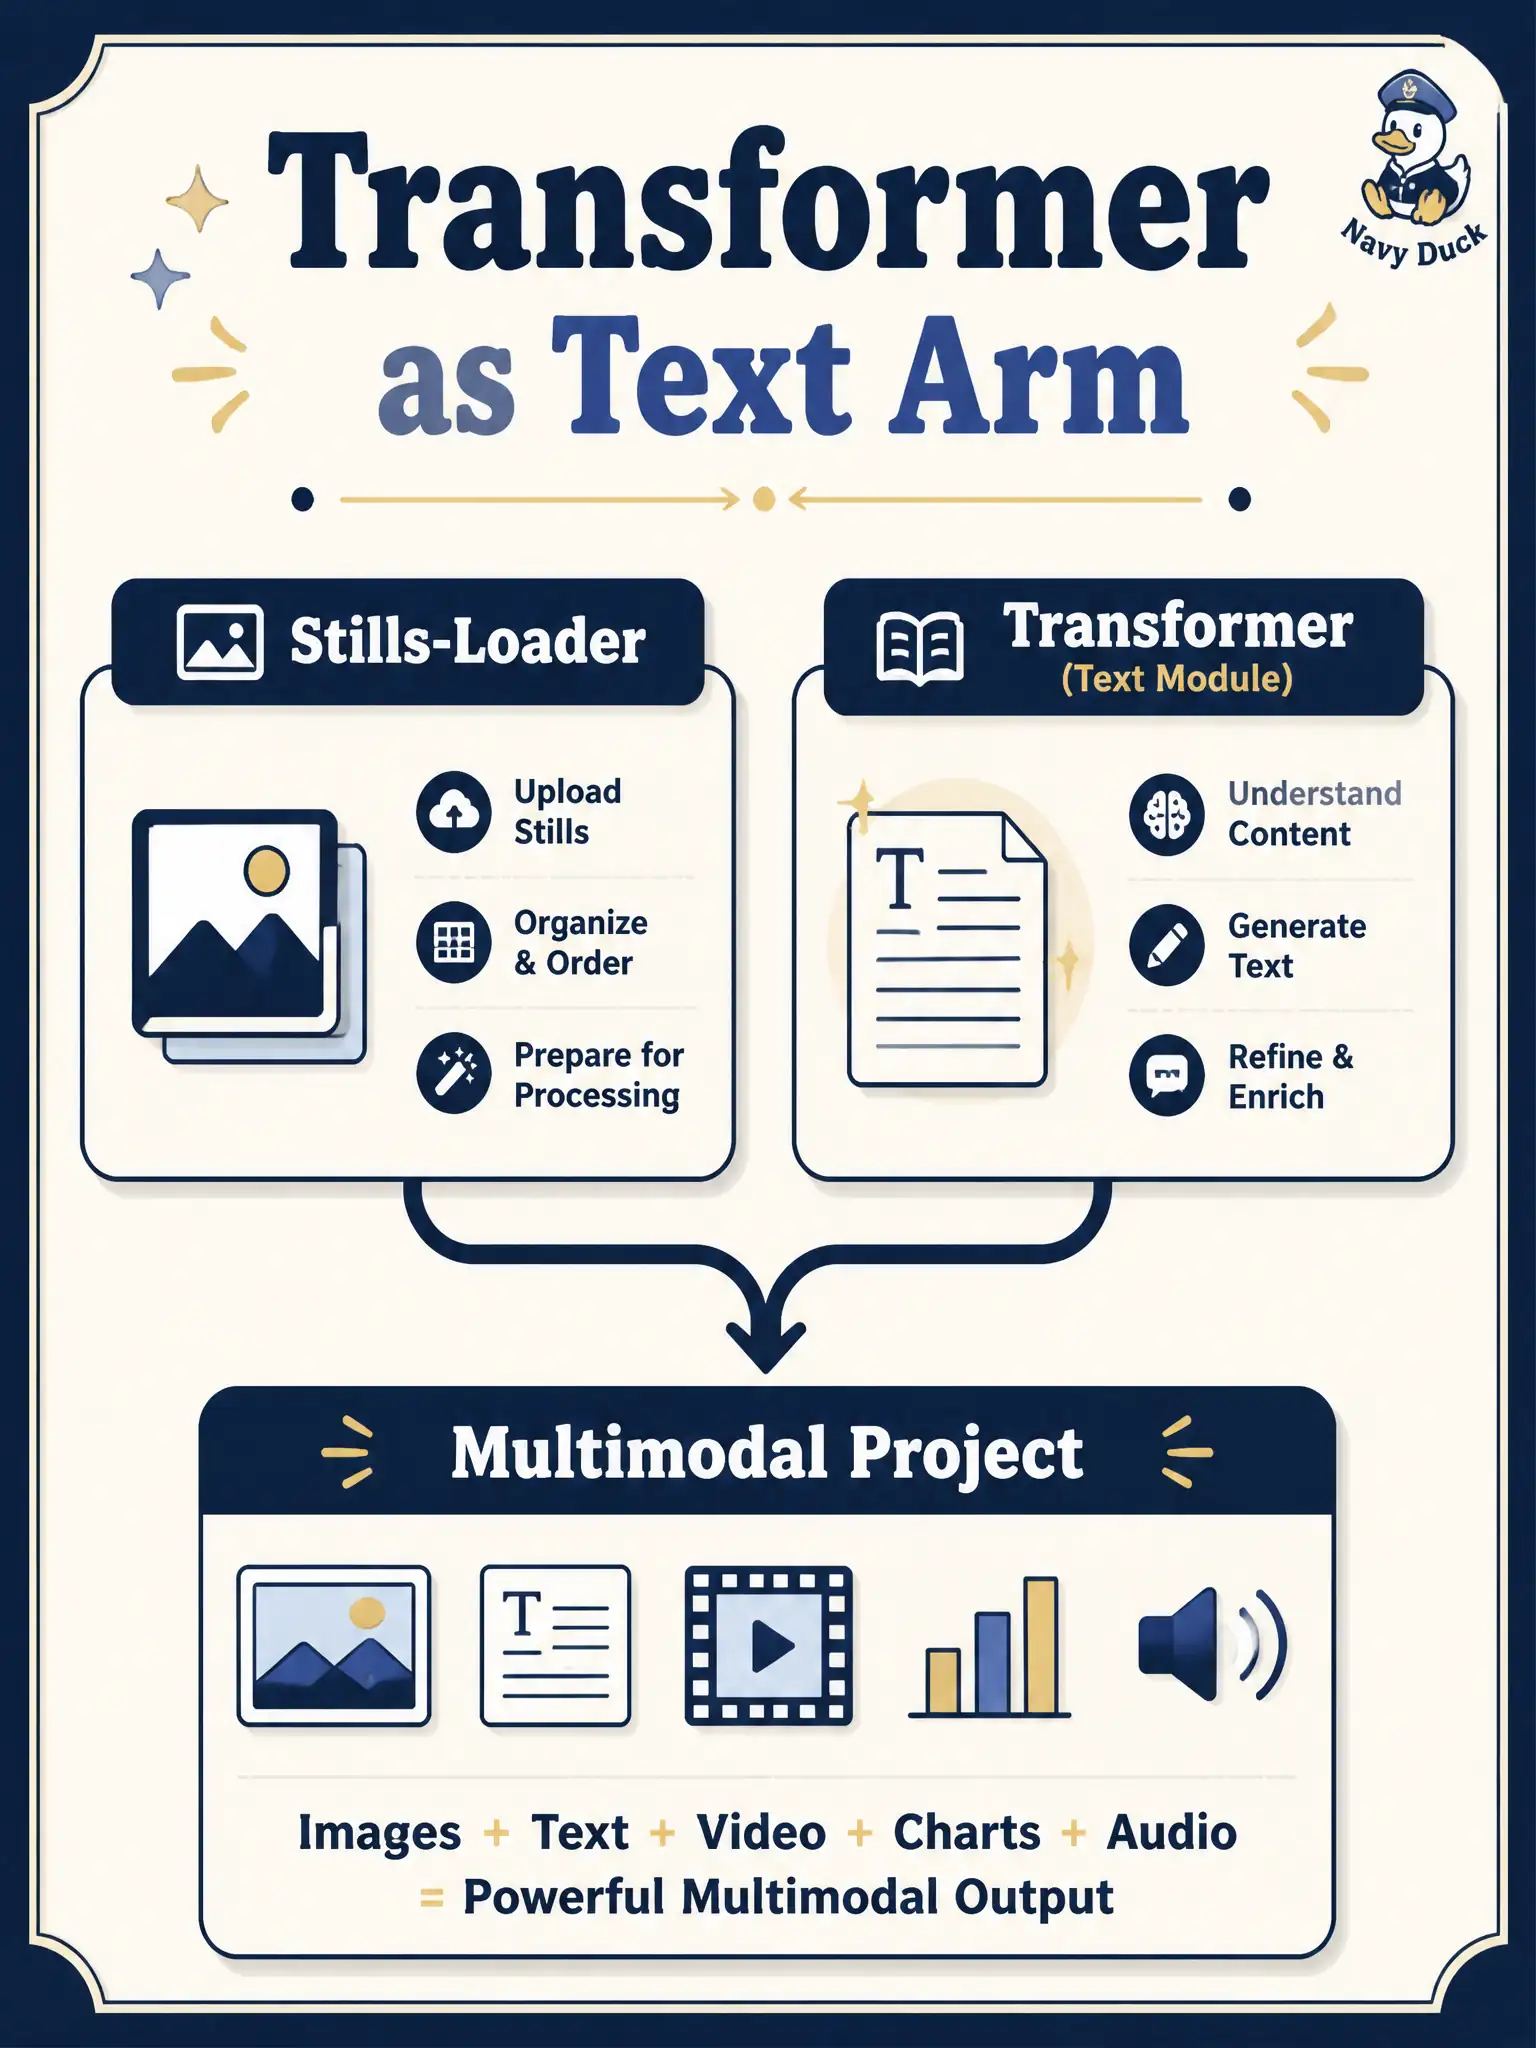
The text arm is a library you plug in, not a new language exam. Bring in a pretrained transformer from the framework so care sentences have a place to go.
Full Explanation
Adding a text arm for care sentences beside an existing stills loader means importing a pretrained transformer from a modern deep learning framework as the text module. That approach is correct for the button mill: associate implementation uses packaged text encoders, not custom kernels or off-exam product swaps. Civic care-label text beside product stills needs that text arm in the same project.
Opening an NCA-GENL prompt-catalog product instead of a multimodal text module fails exam boundary. Writing a custom CUDA attention kernel before any library import fails associate scope. Replacing the stills loader with a Riva microphone stream for every sentence fails by destroying the vision path the mill already had.
Exam caveat: multimodal text arms are framework transformers, not GENL catalog detours. Operational check: import a pretrained text encoder, keep the stills loader, and join civic care sentences to stills in one framework project. Keep municipal reviewers in the loop whenever modality claims, fusion labels, or agent scripts are promoted from lab notes into the production corpus used by public-facing services. Record the decision, owner, and date beside the dataset manifest.