
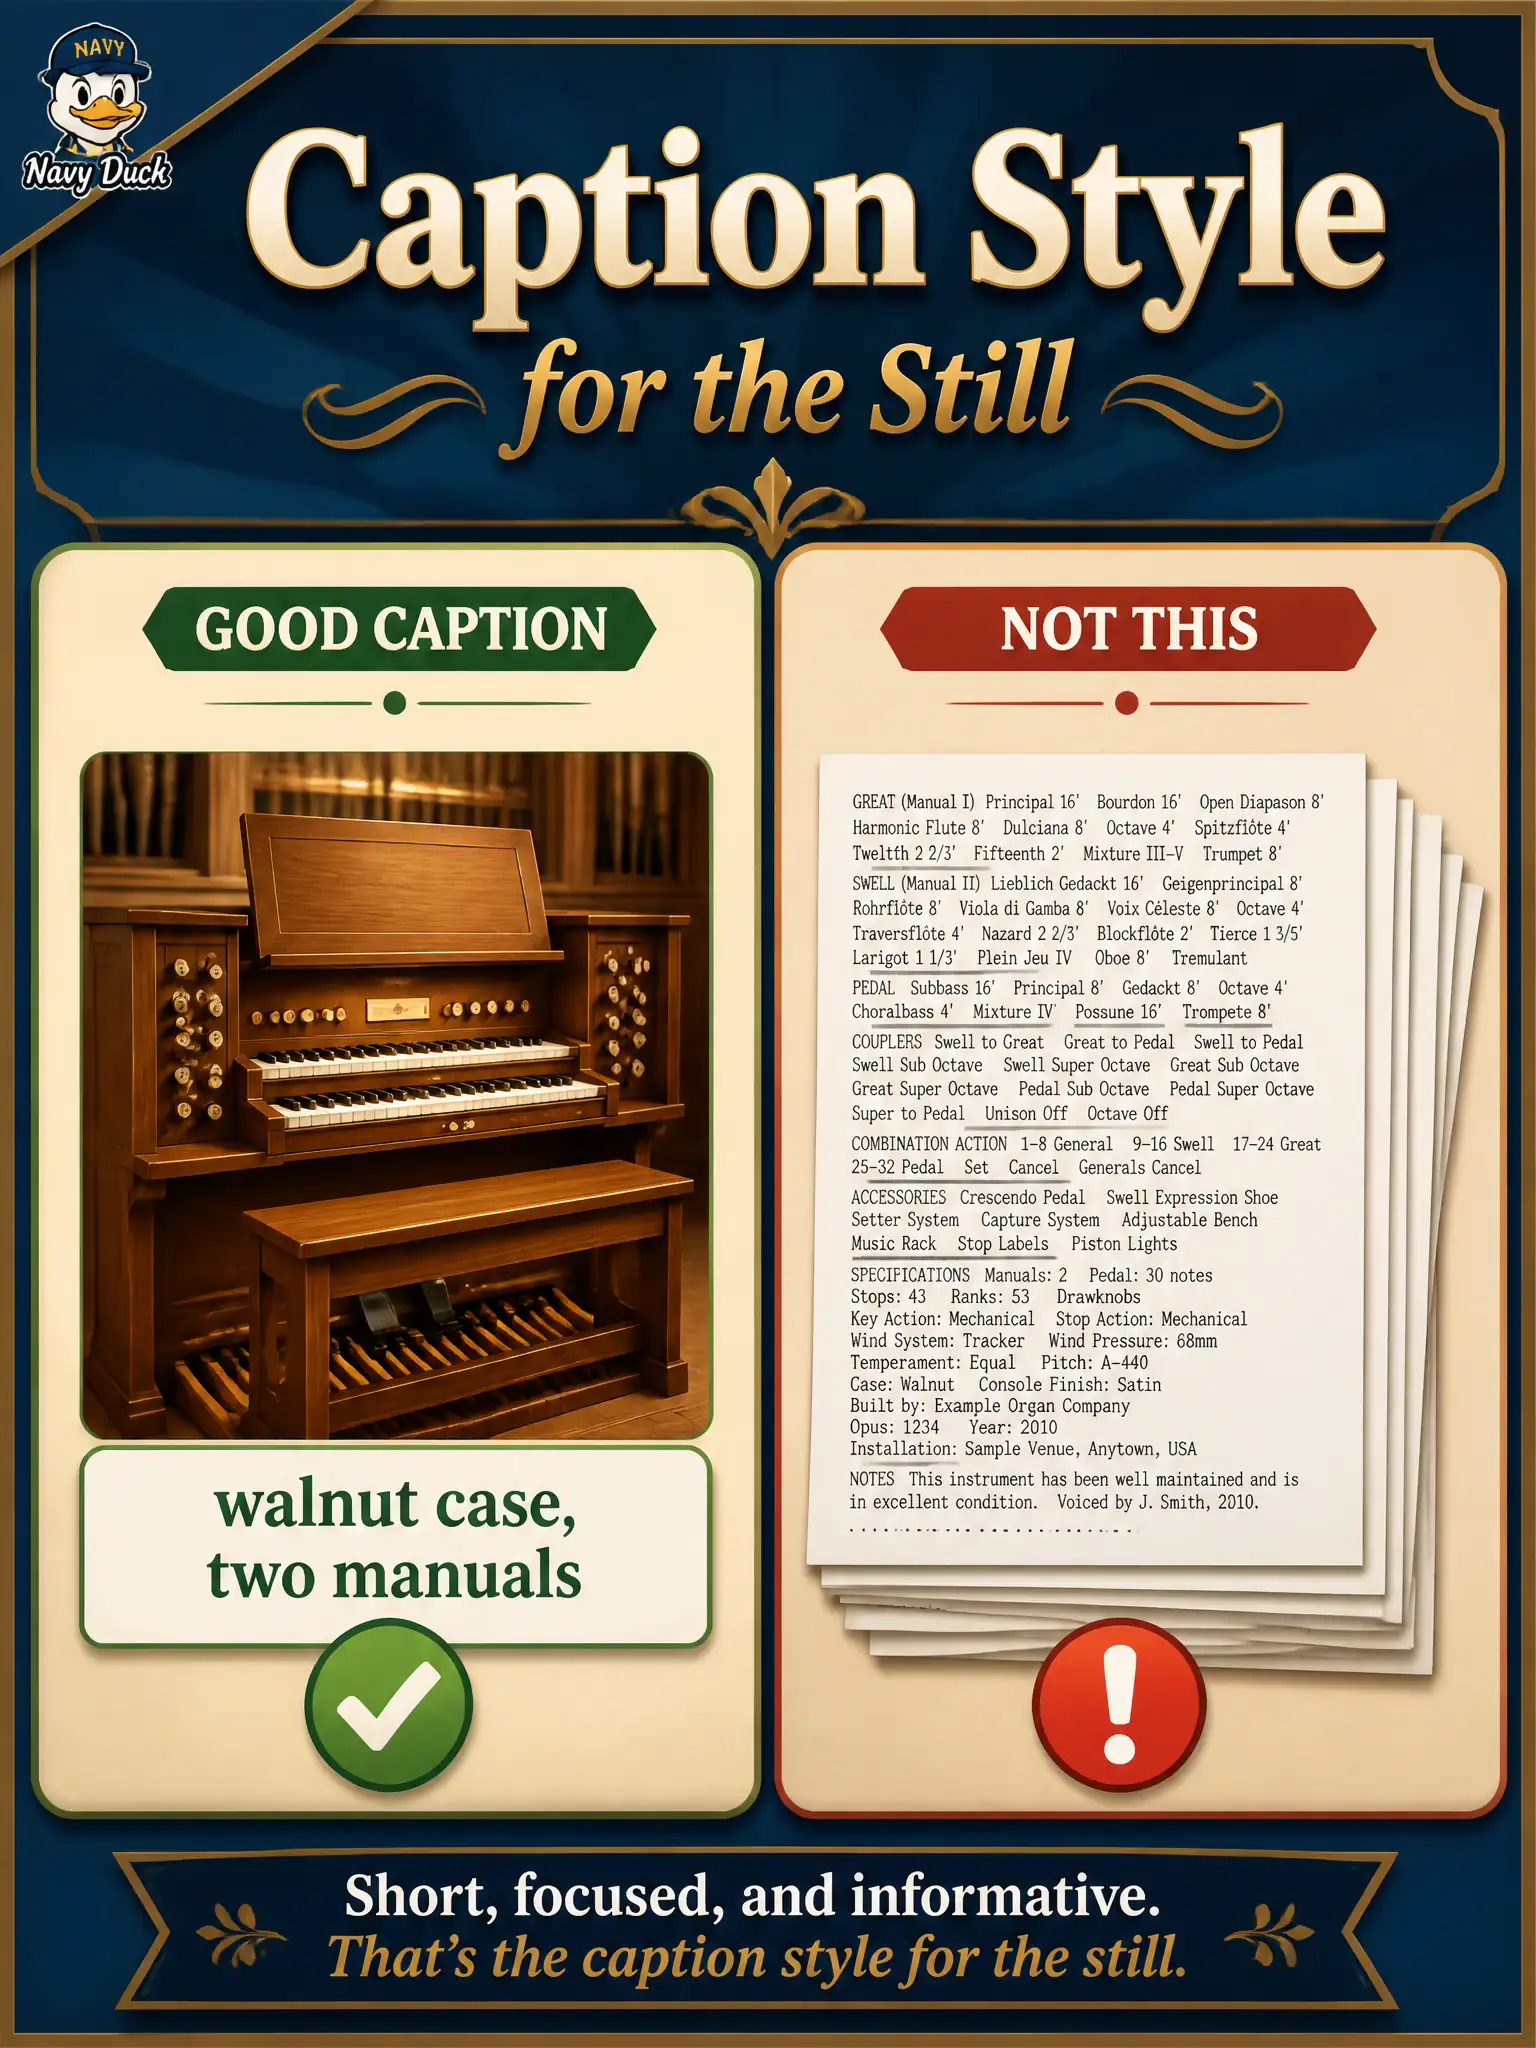
A reed-organ loft can caption a still “walnut case, two manuals” or paste a three-page parts inventory. How should caption length and focus be treated?
Select an answer to reveal the explanation.
Short Explanation
A short, clear label for what’s in the frame beats a parts catalog novel. Caption style is a text-arm data choice—keep it about the picture.
Full Explanation
Caption length and focus are a text-arm data-style choice for CLIP. Preferring a focused English description of the attached reed-organ still over a three-page parts inventory is correct because the text should describe the scene the model must ground, not dump every spare part. Civic asset captions work the same way: a clear label of what is in frame beats an inventory novel that buries the visual subject.
Treating caption style as a Domain 2 transformer definition that rewrites network layers fails by confusing data style with architecture. Claiming longer inventory dumps are always better CLIP captions fails; verbosity without focus can dilute alignment. Making every caption a Riva ASR requirement to be spoken aloud first fails by adding an irrelevant speech constraint to an image–text pair. Focused captions also keep evaluation readable when civic reviewers spot-check model retrievals against the still.
Exam caveat: longer is not automatically better for associate CLIP text arms. Operational check: define a civic caption style guide—subject, materials, distinctive visible traits—and reject inventory dumps that do not describe the still. Re-verify join keys and modality completeness on every promotion from lab shelf to civic production corpus.