
A clog shop keeps stills in one drawer and English slogans in another with no shared identifier. What is required before those piles can become a CLIP paired corpus?
Select an answer to reveal the explanation.
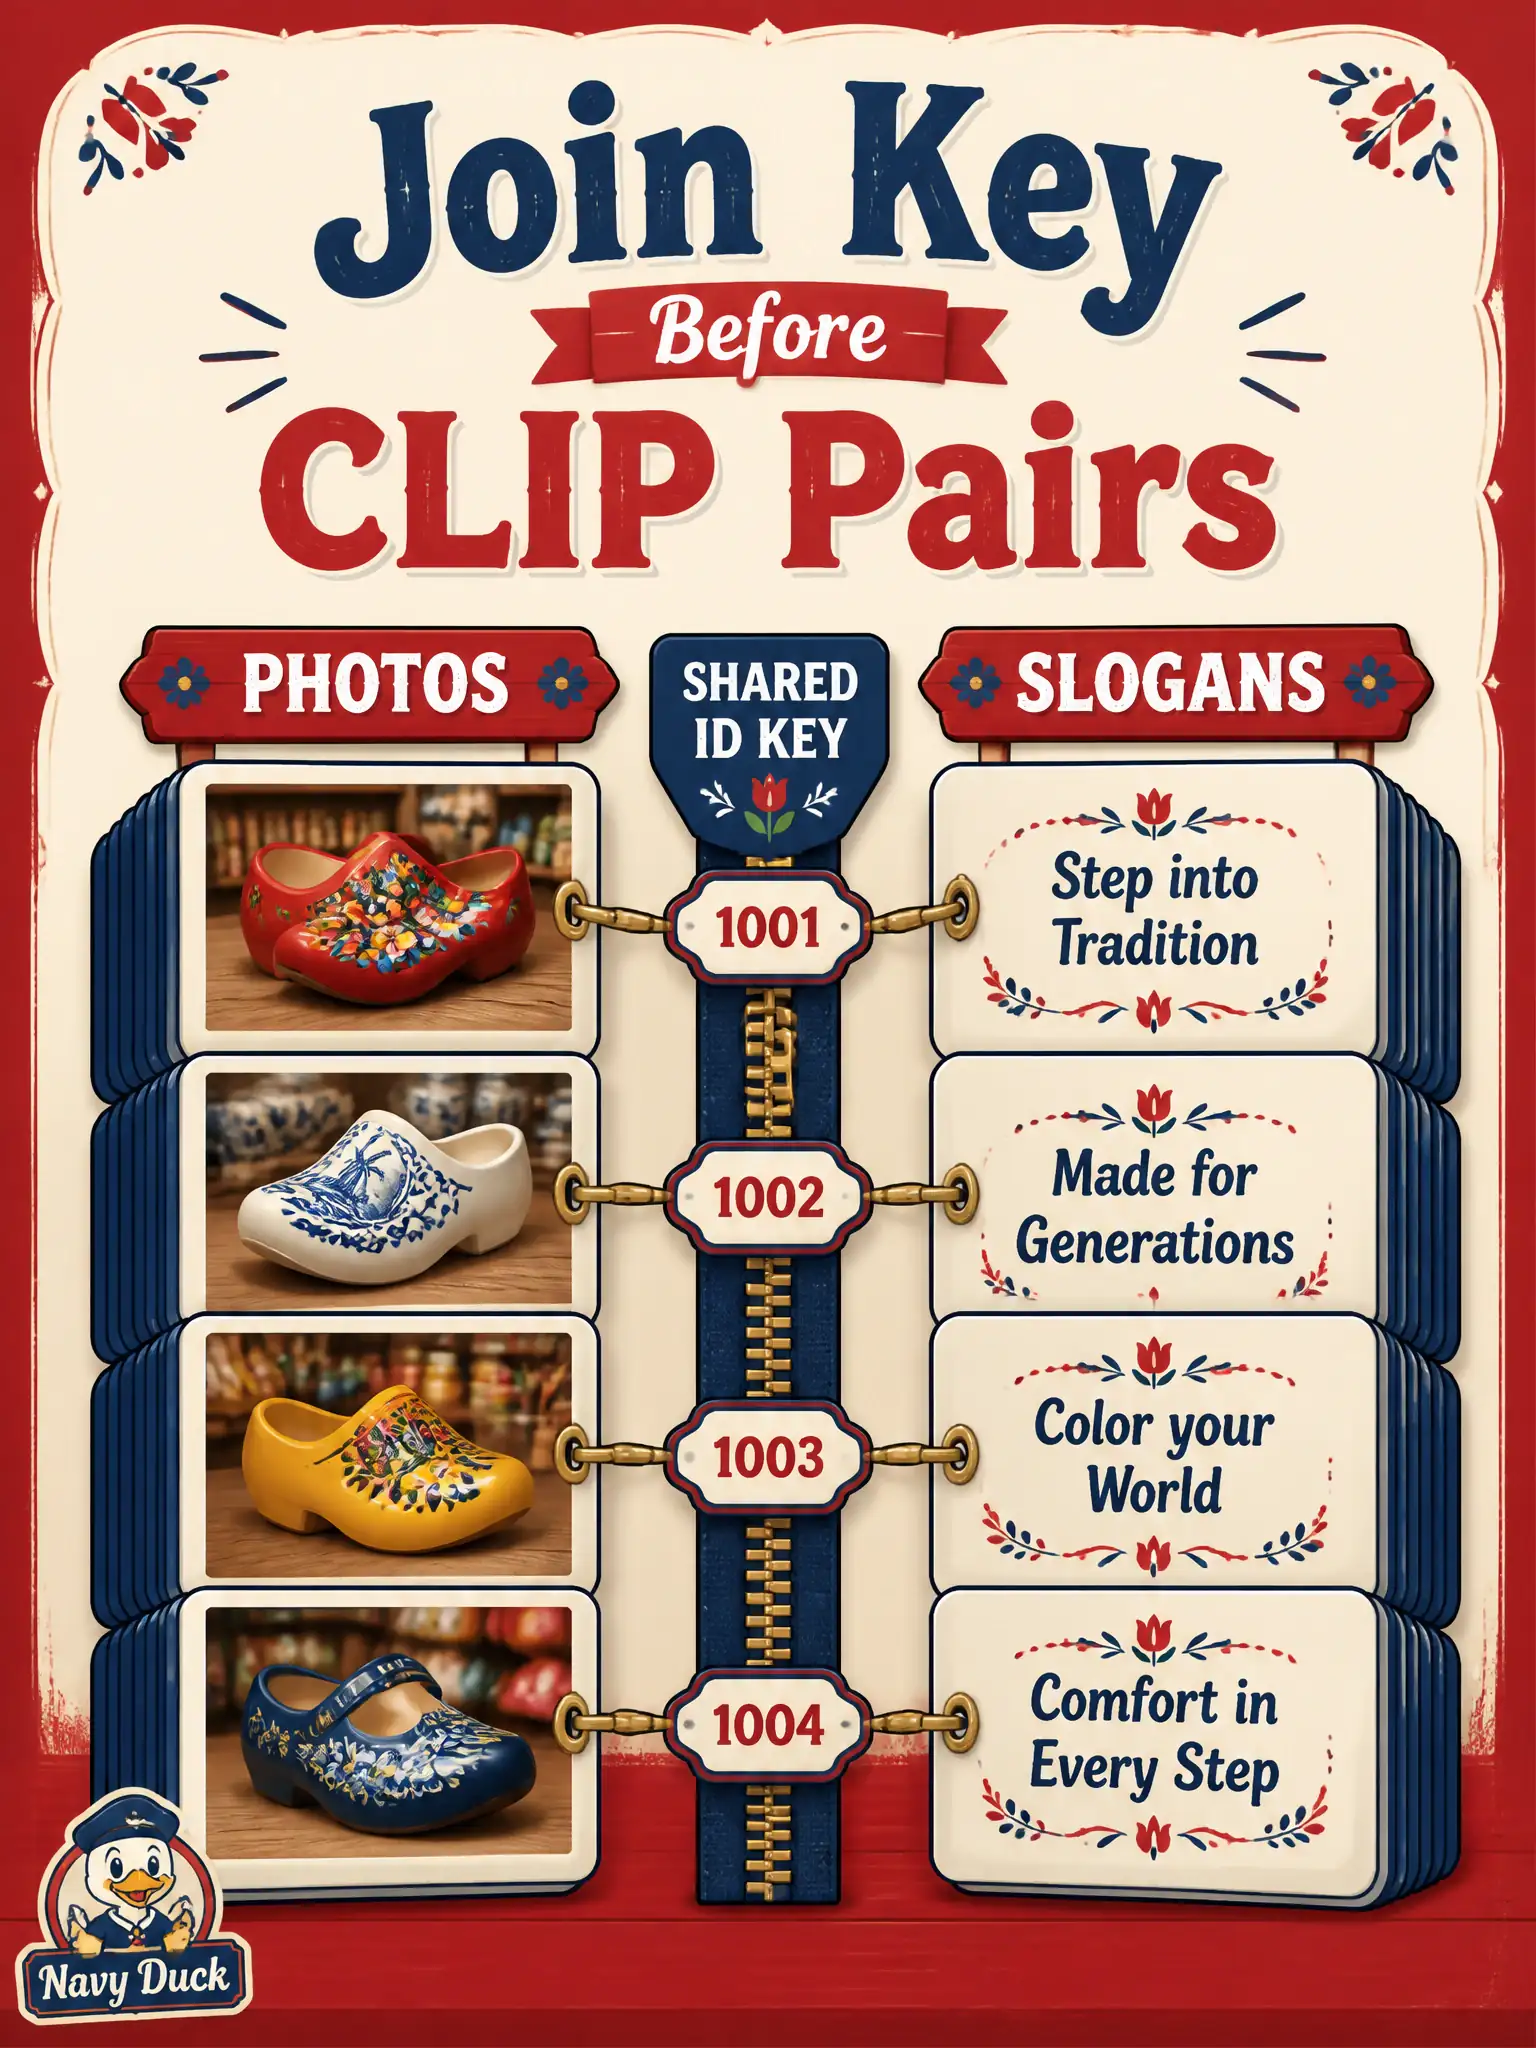
Short Explanation
Two drawers with no shared ticket number are not a paired set. Add a join key so each photo finds its sentence before anyone claims a CLIP corpus.
Full Explanation
Paired corpora require an explicit join between modalities. Requiring an explicit join key that links each clog-shop still to its English caption row is correct because separate drawers with no shared identifier are two unpaired piles, not a CLIP corpus. Civic data lakes often accumulate photos and captions in different systems; without a shared ticket, training silently learns random associations and public-facing retrieval becomes unreliable.
A Domain 2 late-fusion redesign so unpaired drawers train automatically fails by hoping architecture vocabulary will invent joins. Deleting all slogans so only stills remain fails by removing the text arm needed for pairs. A Helm redeploy that invents captions from filenames alone fails operationally and conceptually: packaging cannot manufacture faithful English descriptions. Shared identifiers are the same discipline agencies already use for case numbers and work orders—apply it to multimodal rows.
Exam caveat: folder adjacency is not a join key. Operational check: assign stable example ids across civic still and caption stores, verify one-to-one (or documented many-to-one) links, then mark the set as paired. Re-verify join keys and modality completeness on every promotion from lab shelf to civic production corpus.