
A coble yard has slogan lines such as “tarred bottom, oak strake” ready but no photographs. Can that slogan list be called a CLIP corpus?
Select an answer to reveal the explanation.
Short Explanation
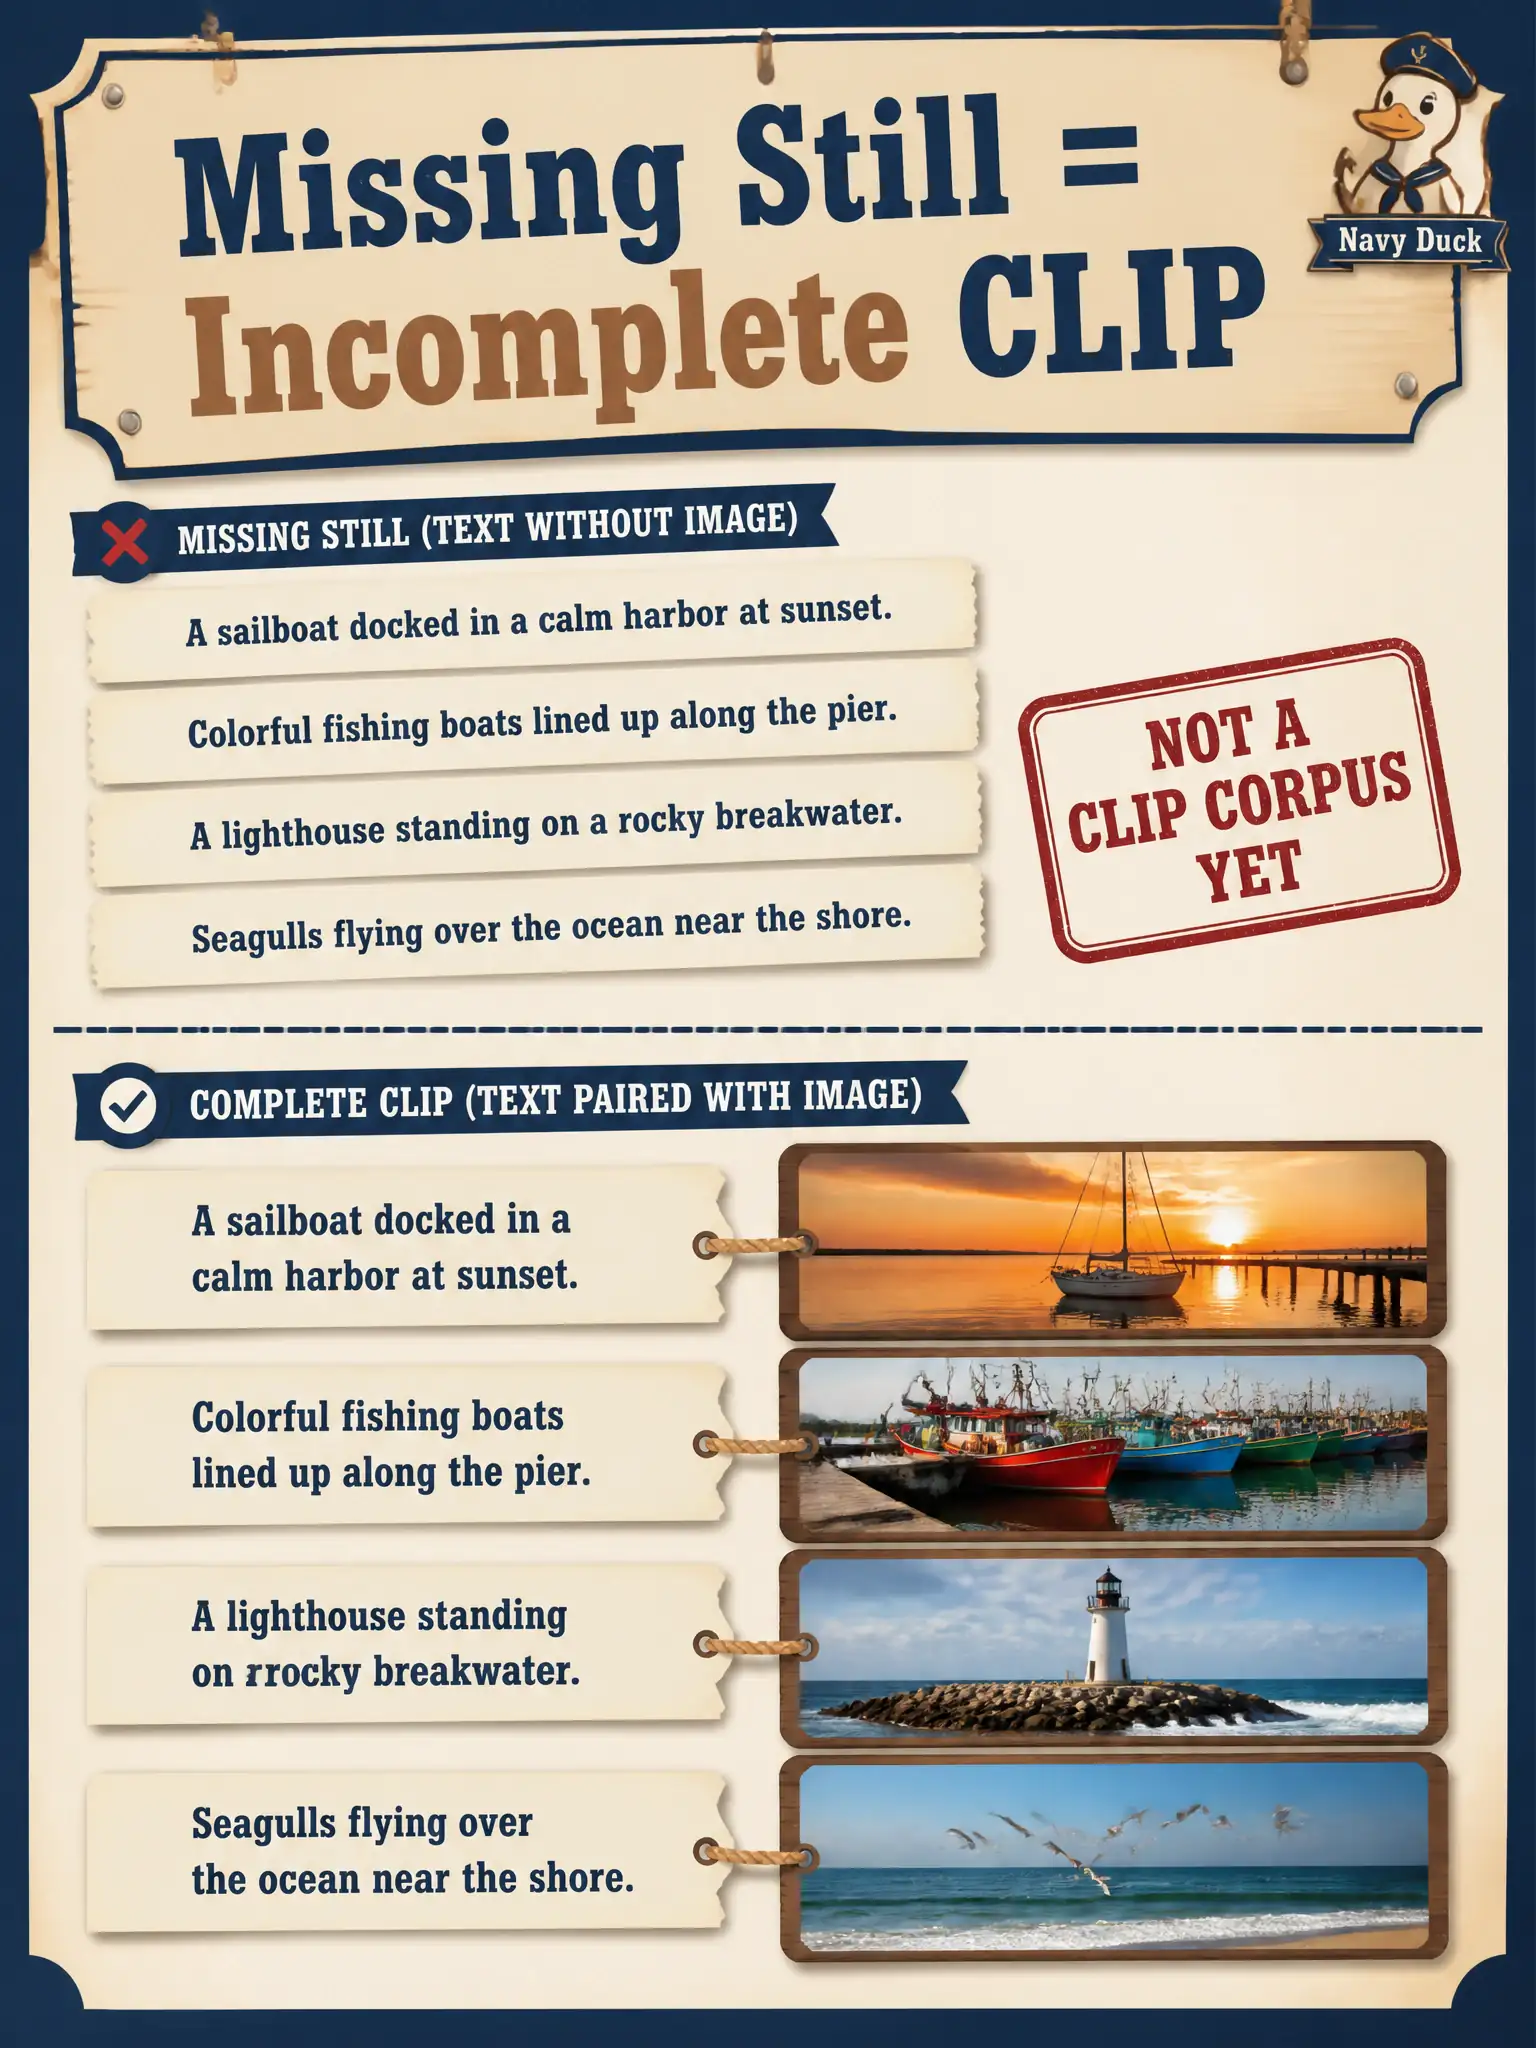
Words without pictures are a slogan list, not a CLIP set. Either attach a still to each line or admit the text is standing alone—don’t fake the pair.
Full Explanation
A CLIP corpus is built from aligned image–text pairs, not from text standing alone. Answering that the coble-yard slogan list cannot be called a CLIP corpus until each line has an image—or is clearly held as text-only, not as CLIP pairs—is correct. Civic slogan banks and marketing lines without photographs are useful text assets, but claiming they are CLIP pairs misrepresents the modality contract and breaks downstream training assumptions.
Saying English text alone is a complete CLIP pair fails the image-arm requirement. Converting slogans into Riva TTS scripts first fails by changing the problem into speech synthesis rather than creating image–text pairs. Attaching a pronunciation lexicon fails for the same conceptual reason: speech resources do not supply stills. Clear labeling prevents false dashboards that claim CLIP coverage for a public catalog that still lacks photographs.
Exam caveat: label text-only civic assets honestly; do not inflate them into CLIP corpora. Operational check: either capture matching stills for each slogan under a join key or file the list as text-only outside the CLIP training set. Re-verify join keys and modality completeness on every promotion from lab shelf to civic production corpus.