
A lime-kiln camp has hundreds of pot stills and empty English caption fields. How should those rows be classified for CLIP?
Select an answer to reveal the explanation.
Short Explanation
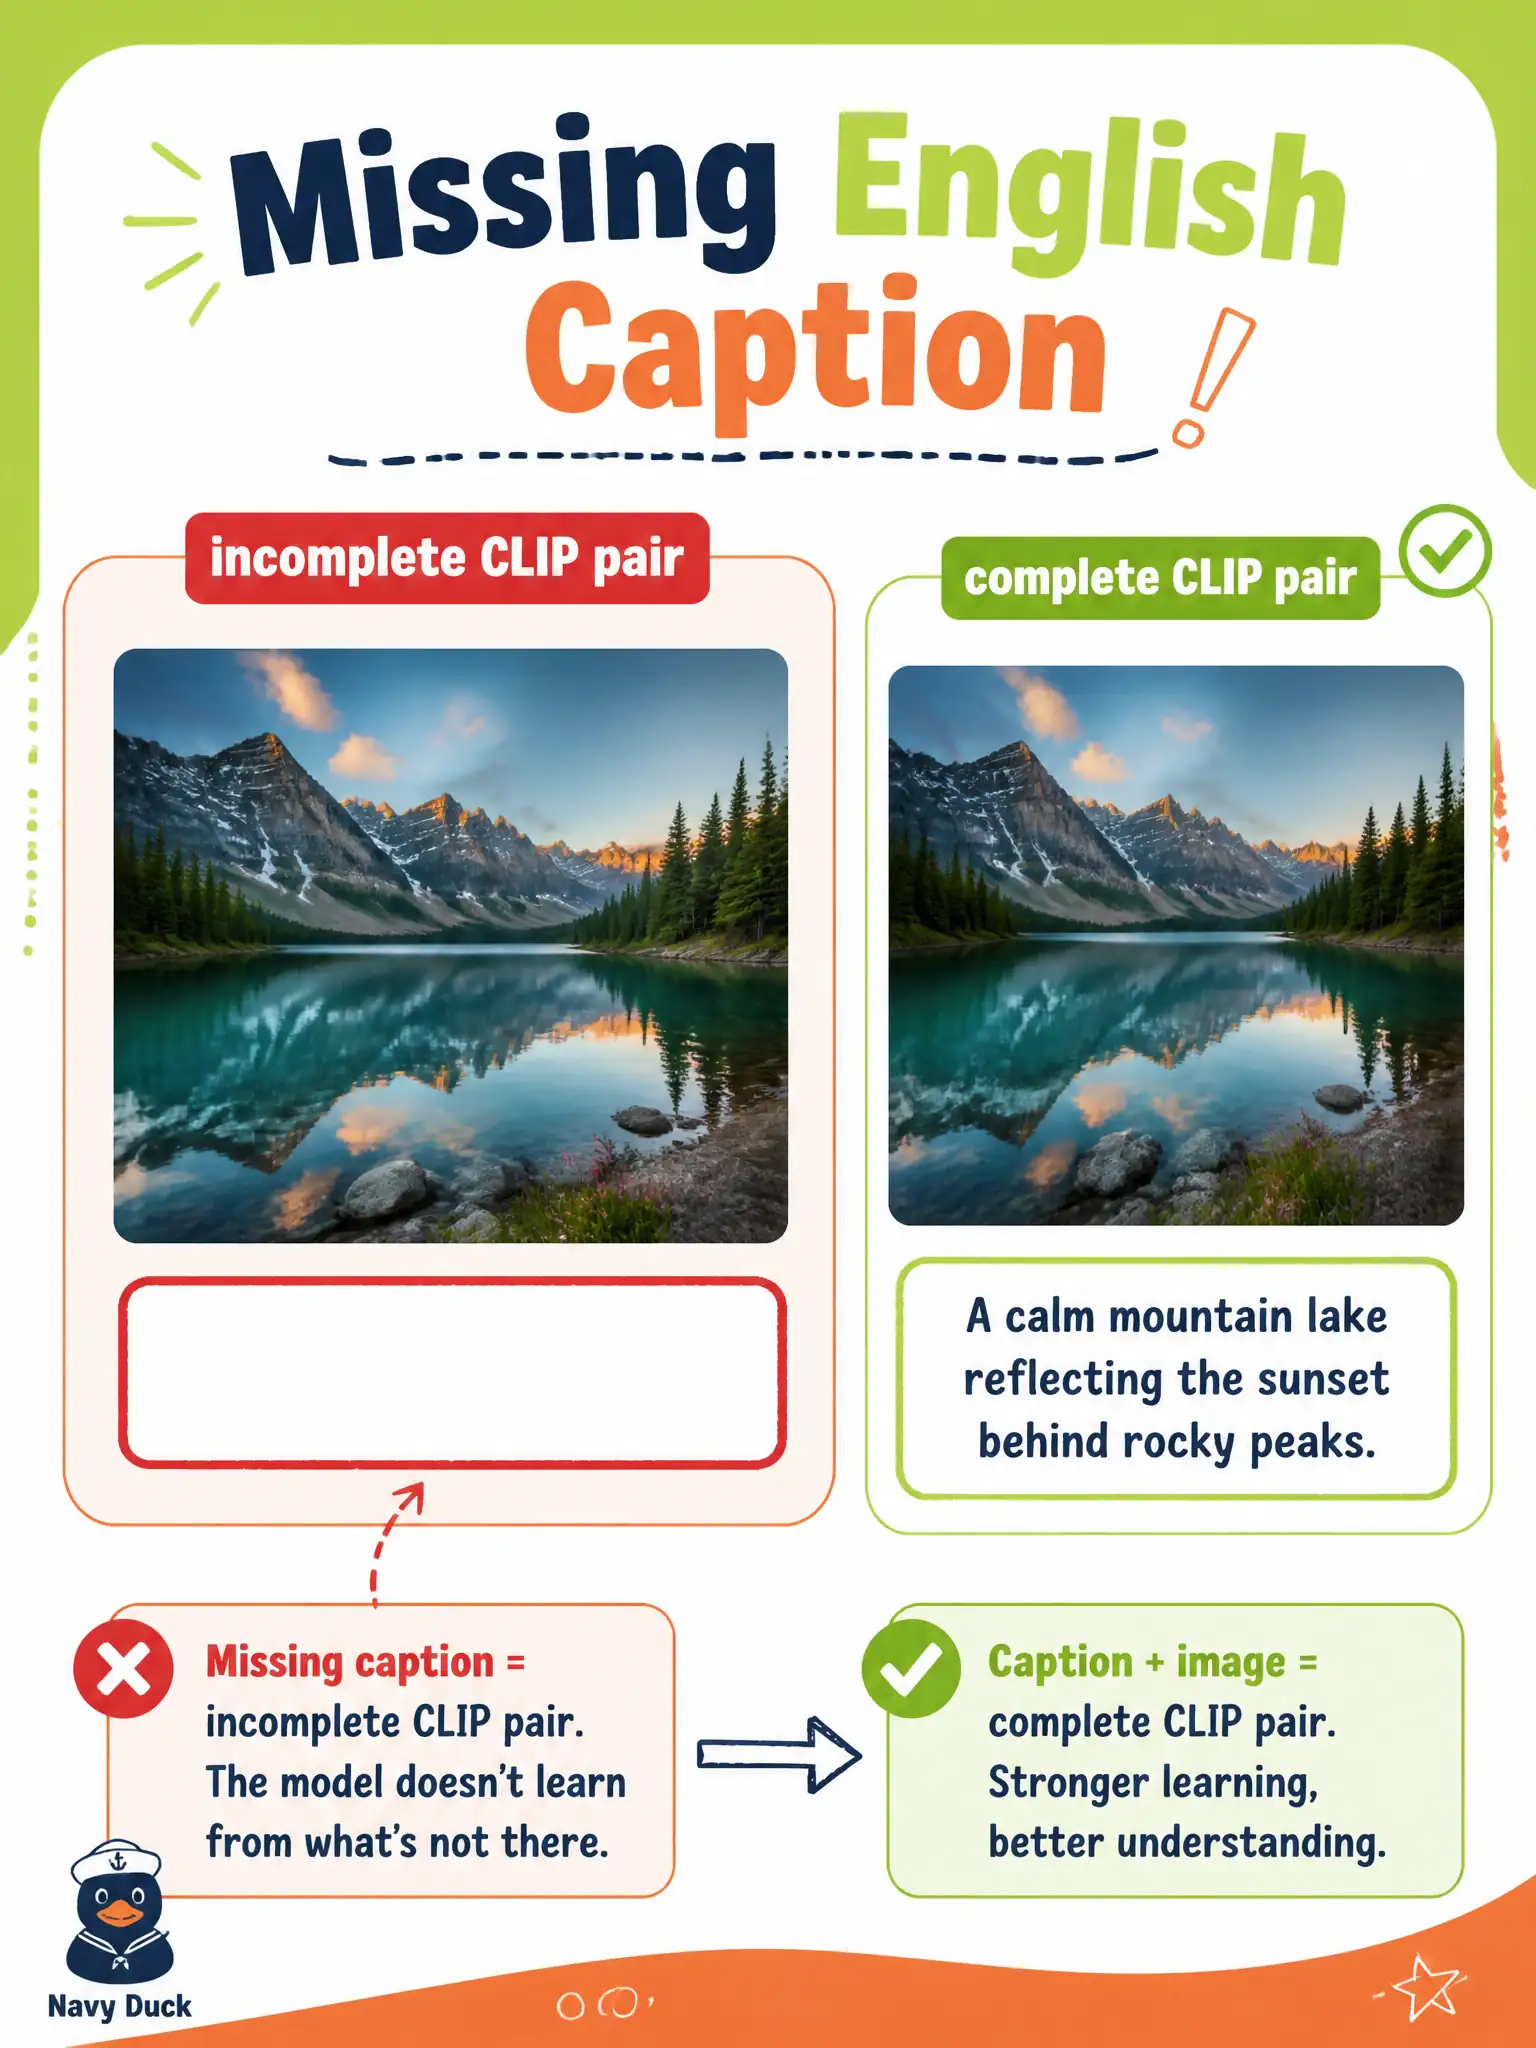
A picture without its English sentence is only half a CLIP card. Empty caption fields mean the text arm is missing—fill them before calling the rows pairs.
Full Explanation
CLIP pairs need both the image arm and the English text arm. Classifying hundreds of lime-kiln pot stills with empty English caption fields as incomplete CLIP pairs with a missing-modality problem on the text arm is correct because images alone are not finished pairs. Civic photo dumps without captions cannot support the official text–image path until the missing text modality is filled or the rows are explicitly held outside the CLIP corpus.
Calling them finished CLIP pairs because images alone are enough fails the two-arm definition. Treating empty captions as Riva ASR pairs fails by inventing a speech transcript where none exists. Calling them Domain 2 transformer definitions that need no captions fails by confusing architecture study with multimodal data completeness. Budget captioning as first-class civic data work rather than hoping empty fields will be ignored at train time.
Exam caveat: empty string fields are missing modality, not optional decoration. Operational check: gate civic CLIP ingestion on non-empty English captions; quarantine incomplete rows and assign captioning work before any pair-based training. Re-verify join keys and modality completeness on every promotion from lab shelf to civic production corpus.