
A cider-press card must be generated from an English line. Which official path turns that line into a visual condition for the image experiment?
Select an answer to reveal the explanation.
Short Explanation
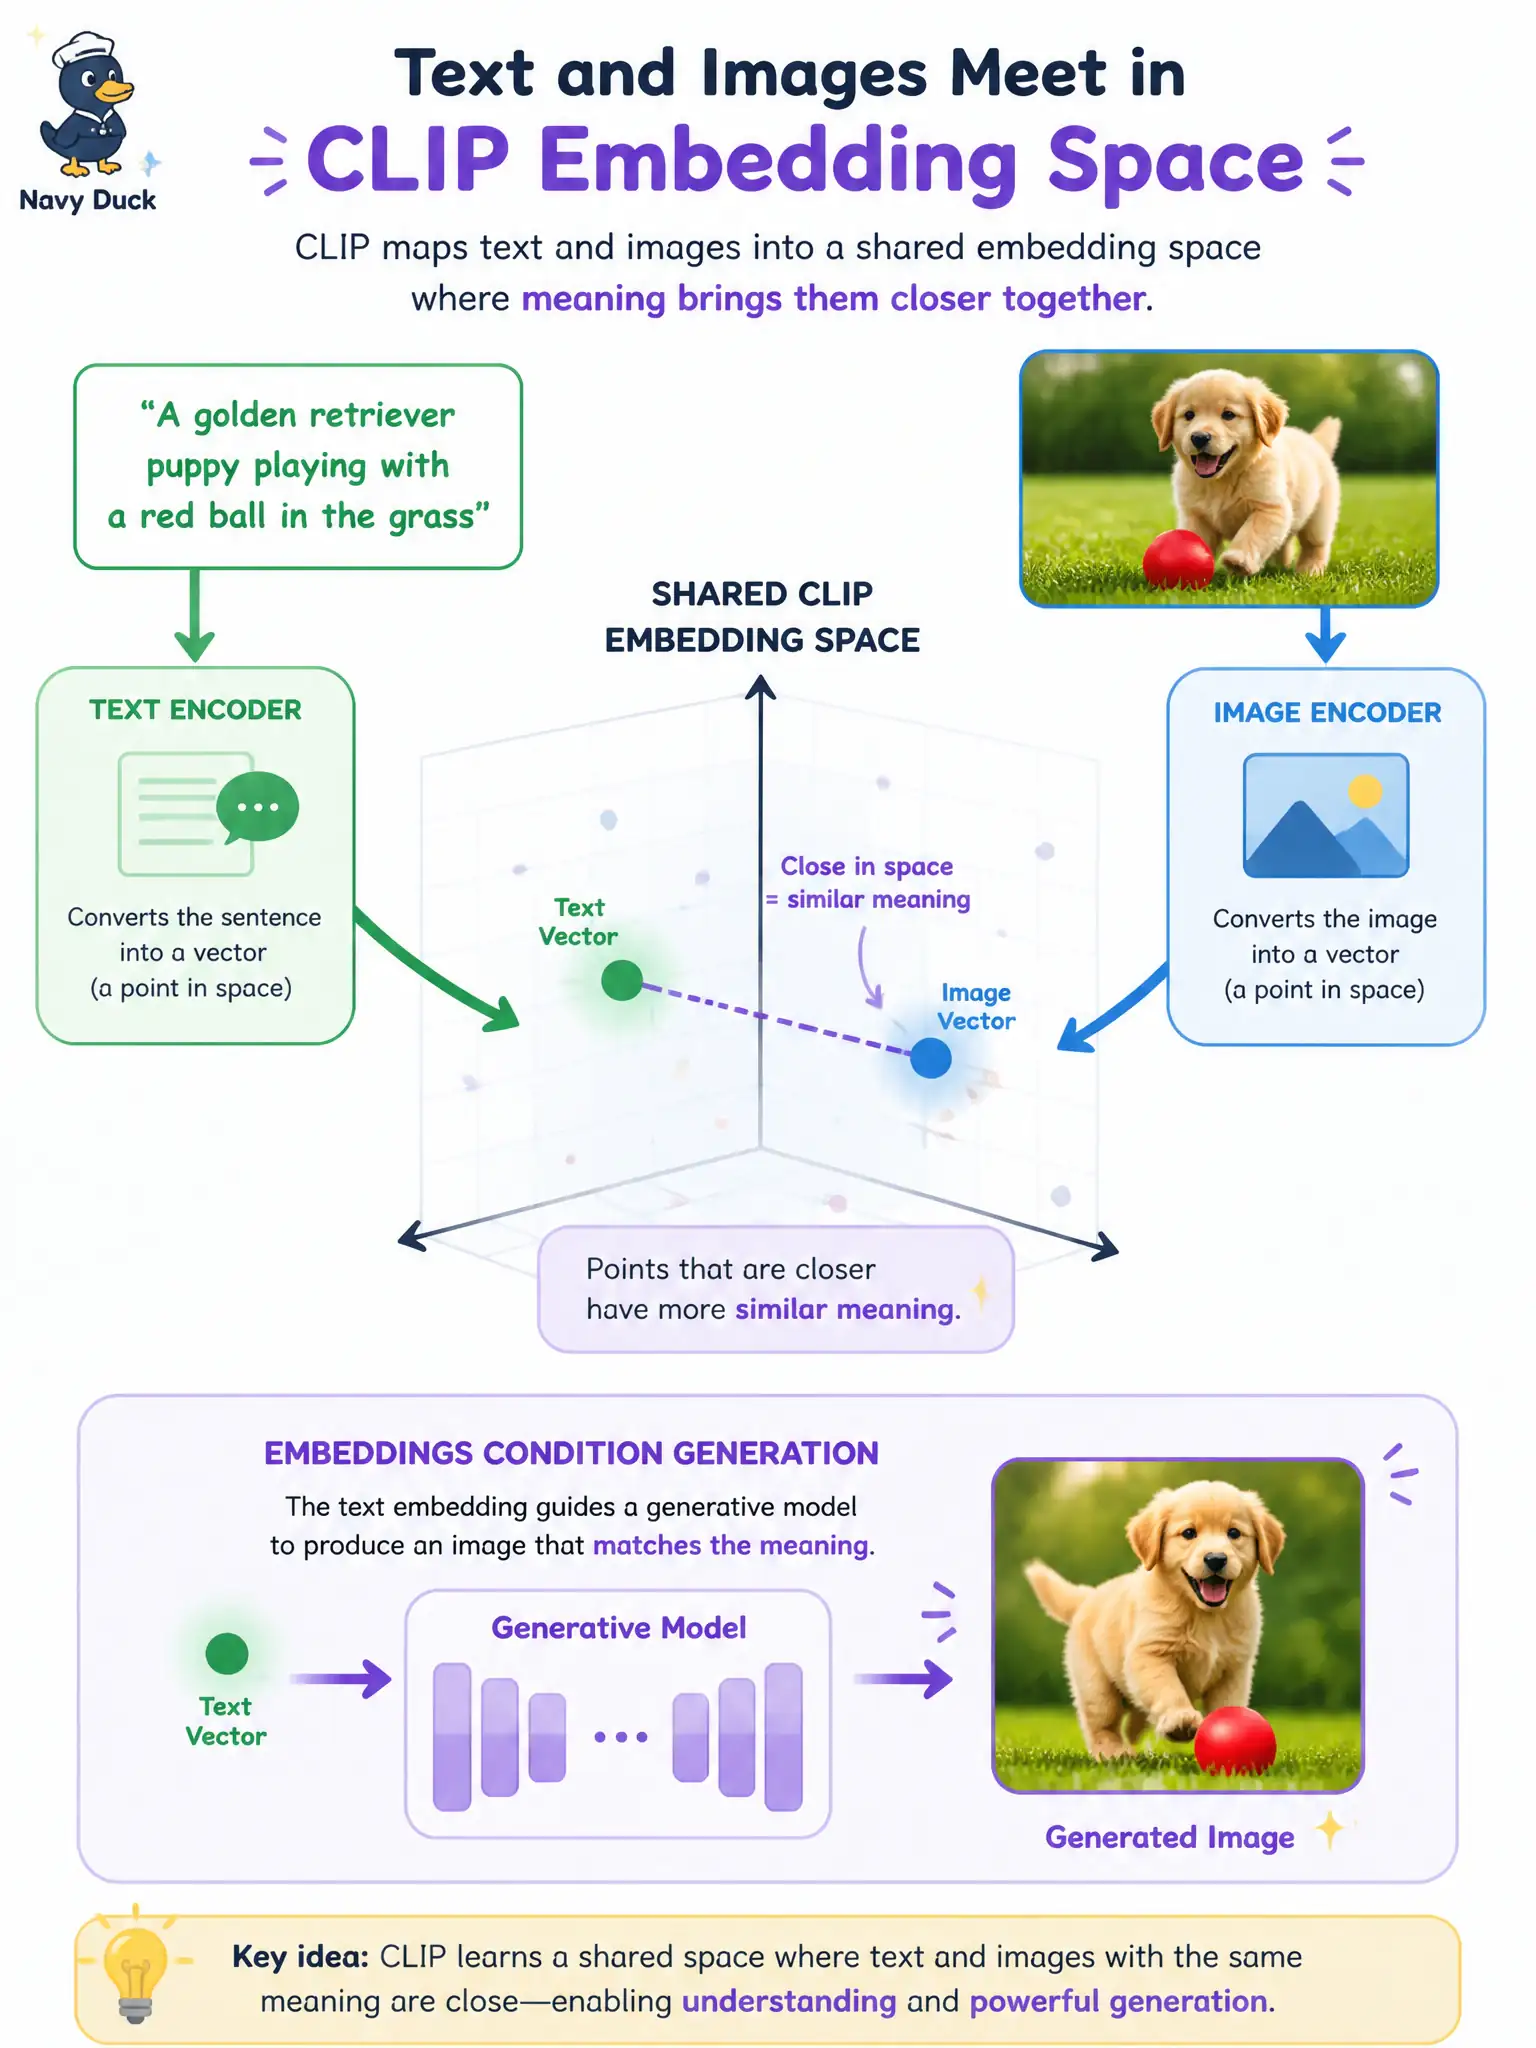
CLIP is the bridge that lets an English sentence tug an image generator toward matching visuals. It is not a speech stack and not an invented photo-app brand.
Full Explanation
A cider-press card that must be generated from an English line should use contrastive language-image pretraining (CLIP) as the official English text-prompt path that turns the line into a visual condition for the image experiment. Civic marketing and farm-stand cards need that named bridge from English sentences to matching visuals without inventing consumer photo brands or substituting speech ASR for image conditioning. Keeping the official CLIP path honest protects public creative pipelines from wrong-stack substitutions.
Using NVIDIA Riva ASR alone without any image conditioning fails by offering speech recognition where visual text–image conditioning is required. Naming an invented consumer image brand not on the exam materials fails by expanding scope with unofficial products. Using RAPIDS cuDF joins over press-yield tables fails by importing tabular dataframe tooling from other exam families into an image conditioning question.
Exam caveat: CLIP is the associate English text-prompt path for image conditioning—not Riva ASR, invented photo apps, or RAPIDS joins. Operational check: embed the English marketing line with the official CLIP text path, condition the generator, and score whether renders agree with the sentence before accepting the card pipeline.