
A cider-press room runs both a Riva booth and a pour-shot generator. An intern pastes the booth’s results into the same “quality” column as the pictures. What should happen?
Select an answer to reveal the explanation.
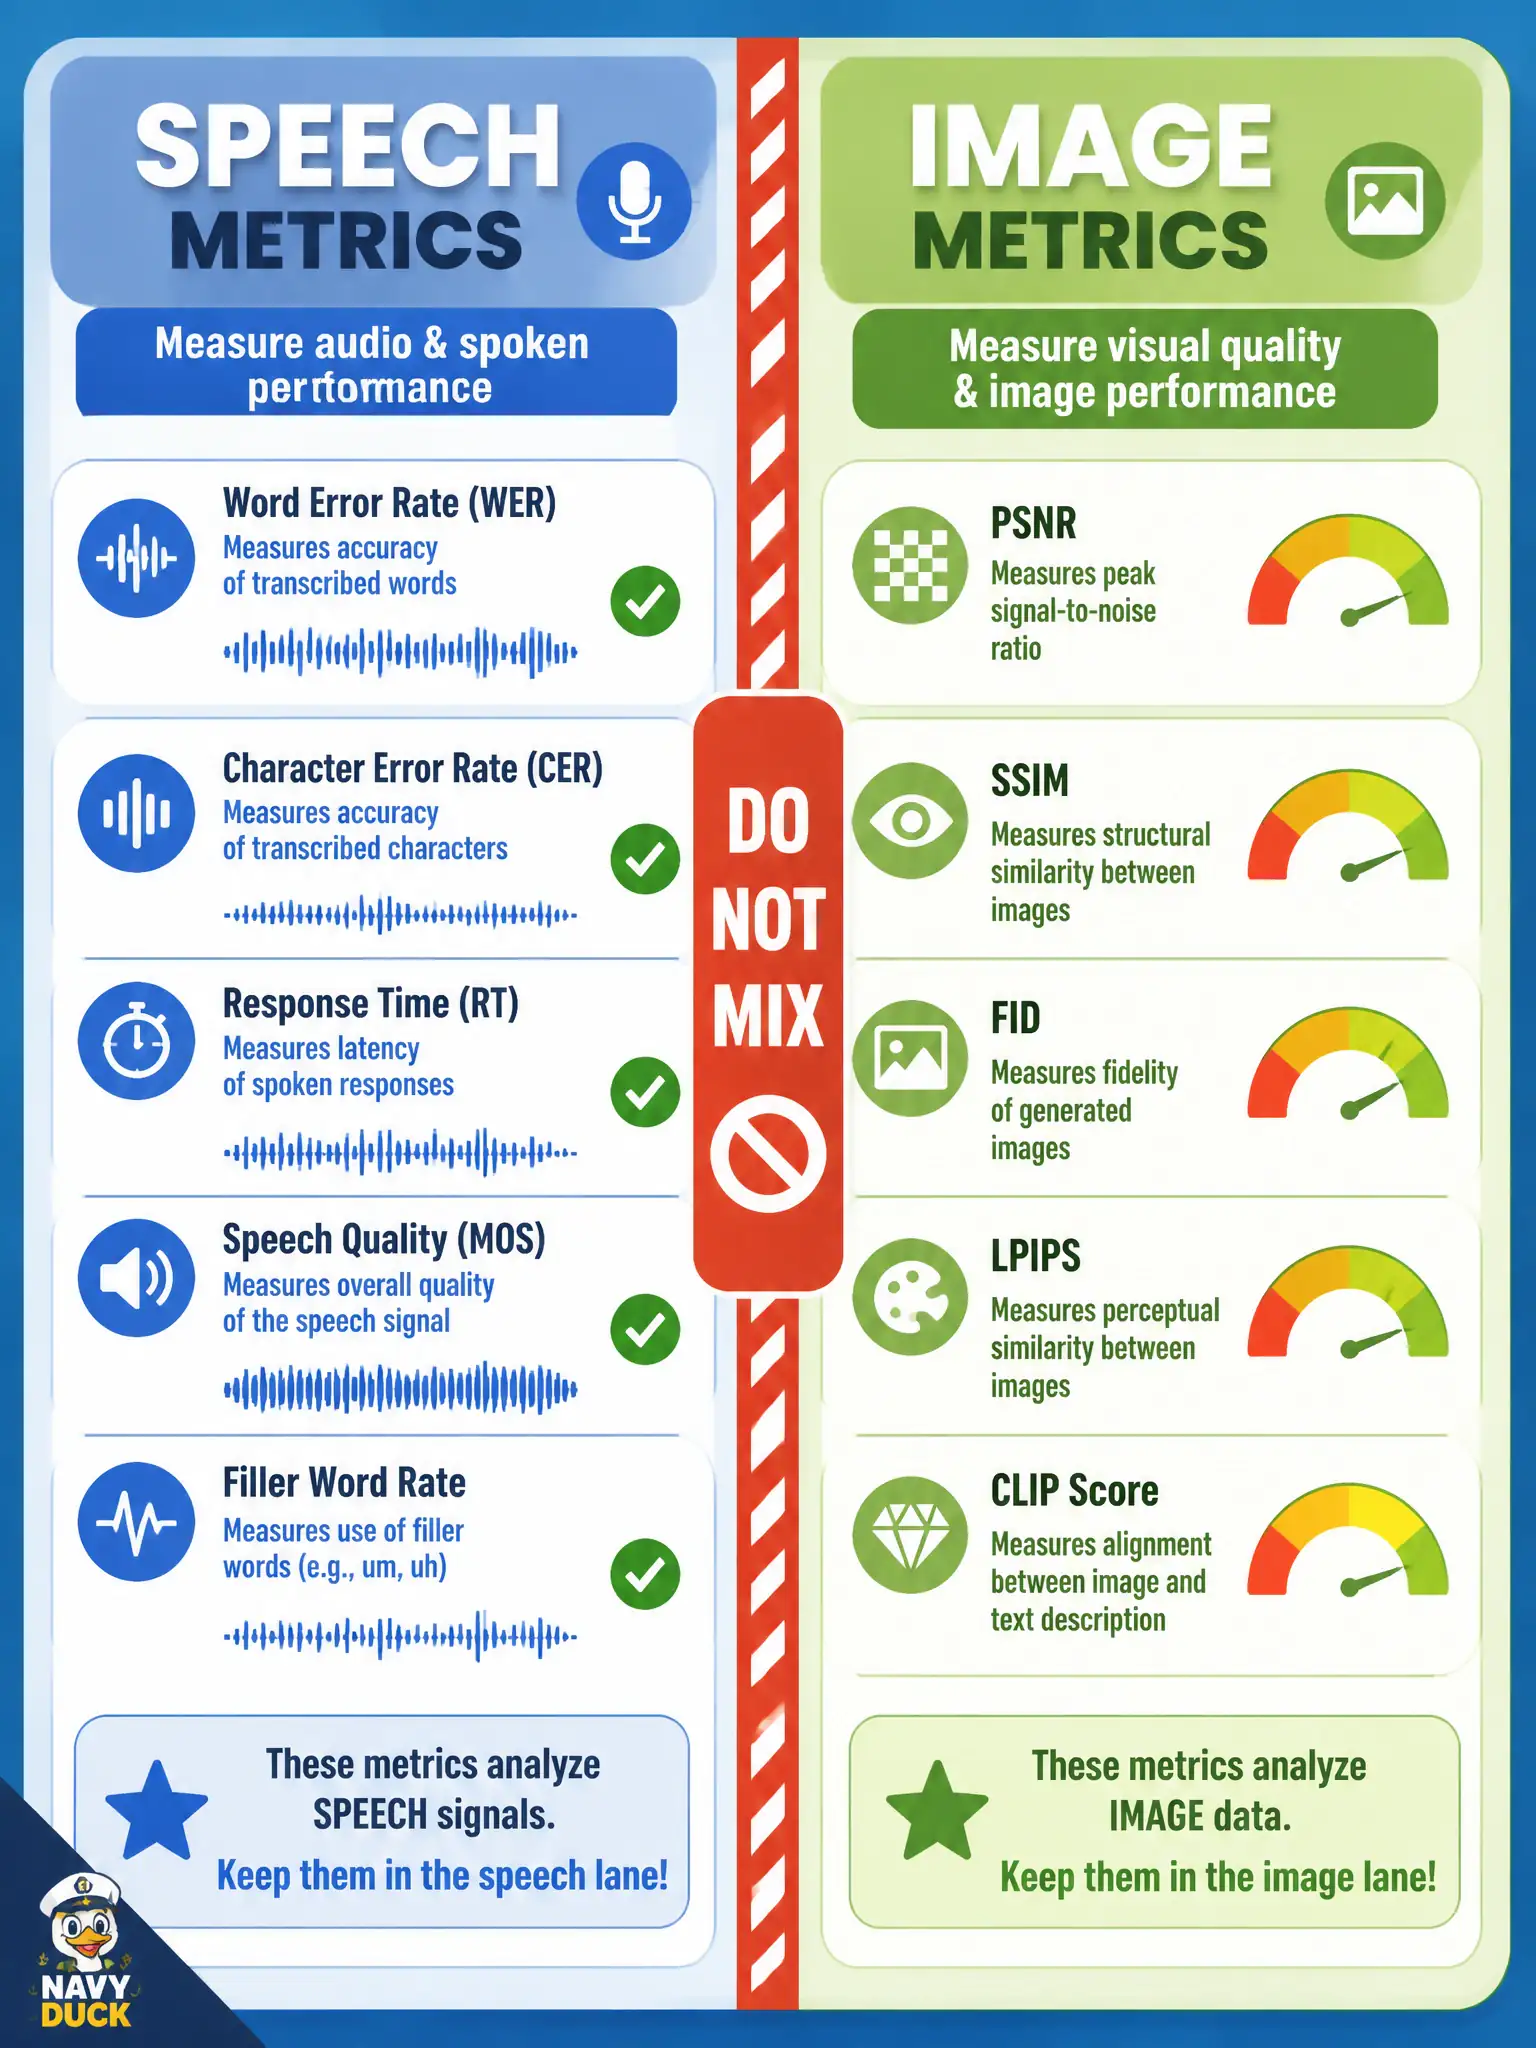
Short Explanation
Lumping a spoken booth and a pour photo into one “quality” cell is like scoring soup and stained glass with the same ruler. Speech needs transcription, task success, or listener ratings. Pictures keep their own scores.
Full Explanation
A cider-press room that runs both a Riva booth and a pour-shot generator should separate speech-pipeline outcomes (transcription, task success, listener ratings) from image-generation outcomes when an intern pastes both into one “quality” column. Civic multimodal programs fail go/no-go decisions when soup and stained glass share one ruler; matching metrics to modality keeps public dashboards honest about what actually improved for visitors and staff.
Keeping one quality column so multimodal dashboards stay simple regardless of modality fails by hiding modality-specific signal under false simplicity. Scoring the speech booth only with image FID so both projects share a vendor metric fails by forcing a generative vision score onto conversational performance. Dropping speech metrics entirely to judge the booth by how pretty its status LEDs look fails by substituting cosmetics for transcription and listener success.
Exam caveat: Riva success uses speech-appropriate measures; image generators use image metrics—do not collapse them on the associate multimodal path. Operational check: split dashboard columns into speech metrics versus image metrics, map each project to its column, and require modality-matched scores before any shared “quality” summary for leadership.