
A linotype shop’s repair sentence must be multiplied by weight matrices inside a language model. What conversion makes that text neural-network ready?
Select an answer to reveal the explanation.
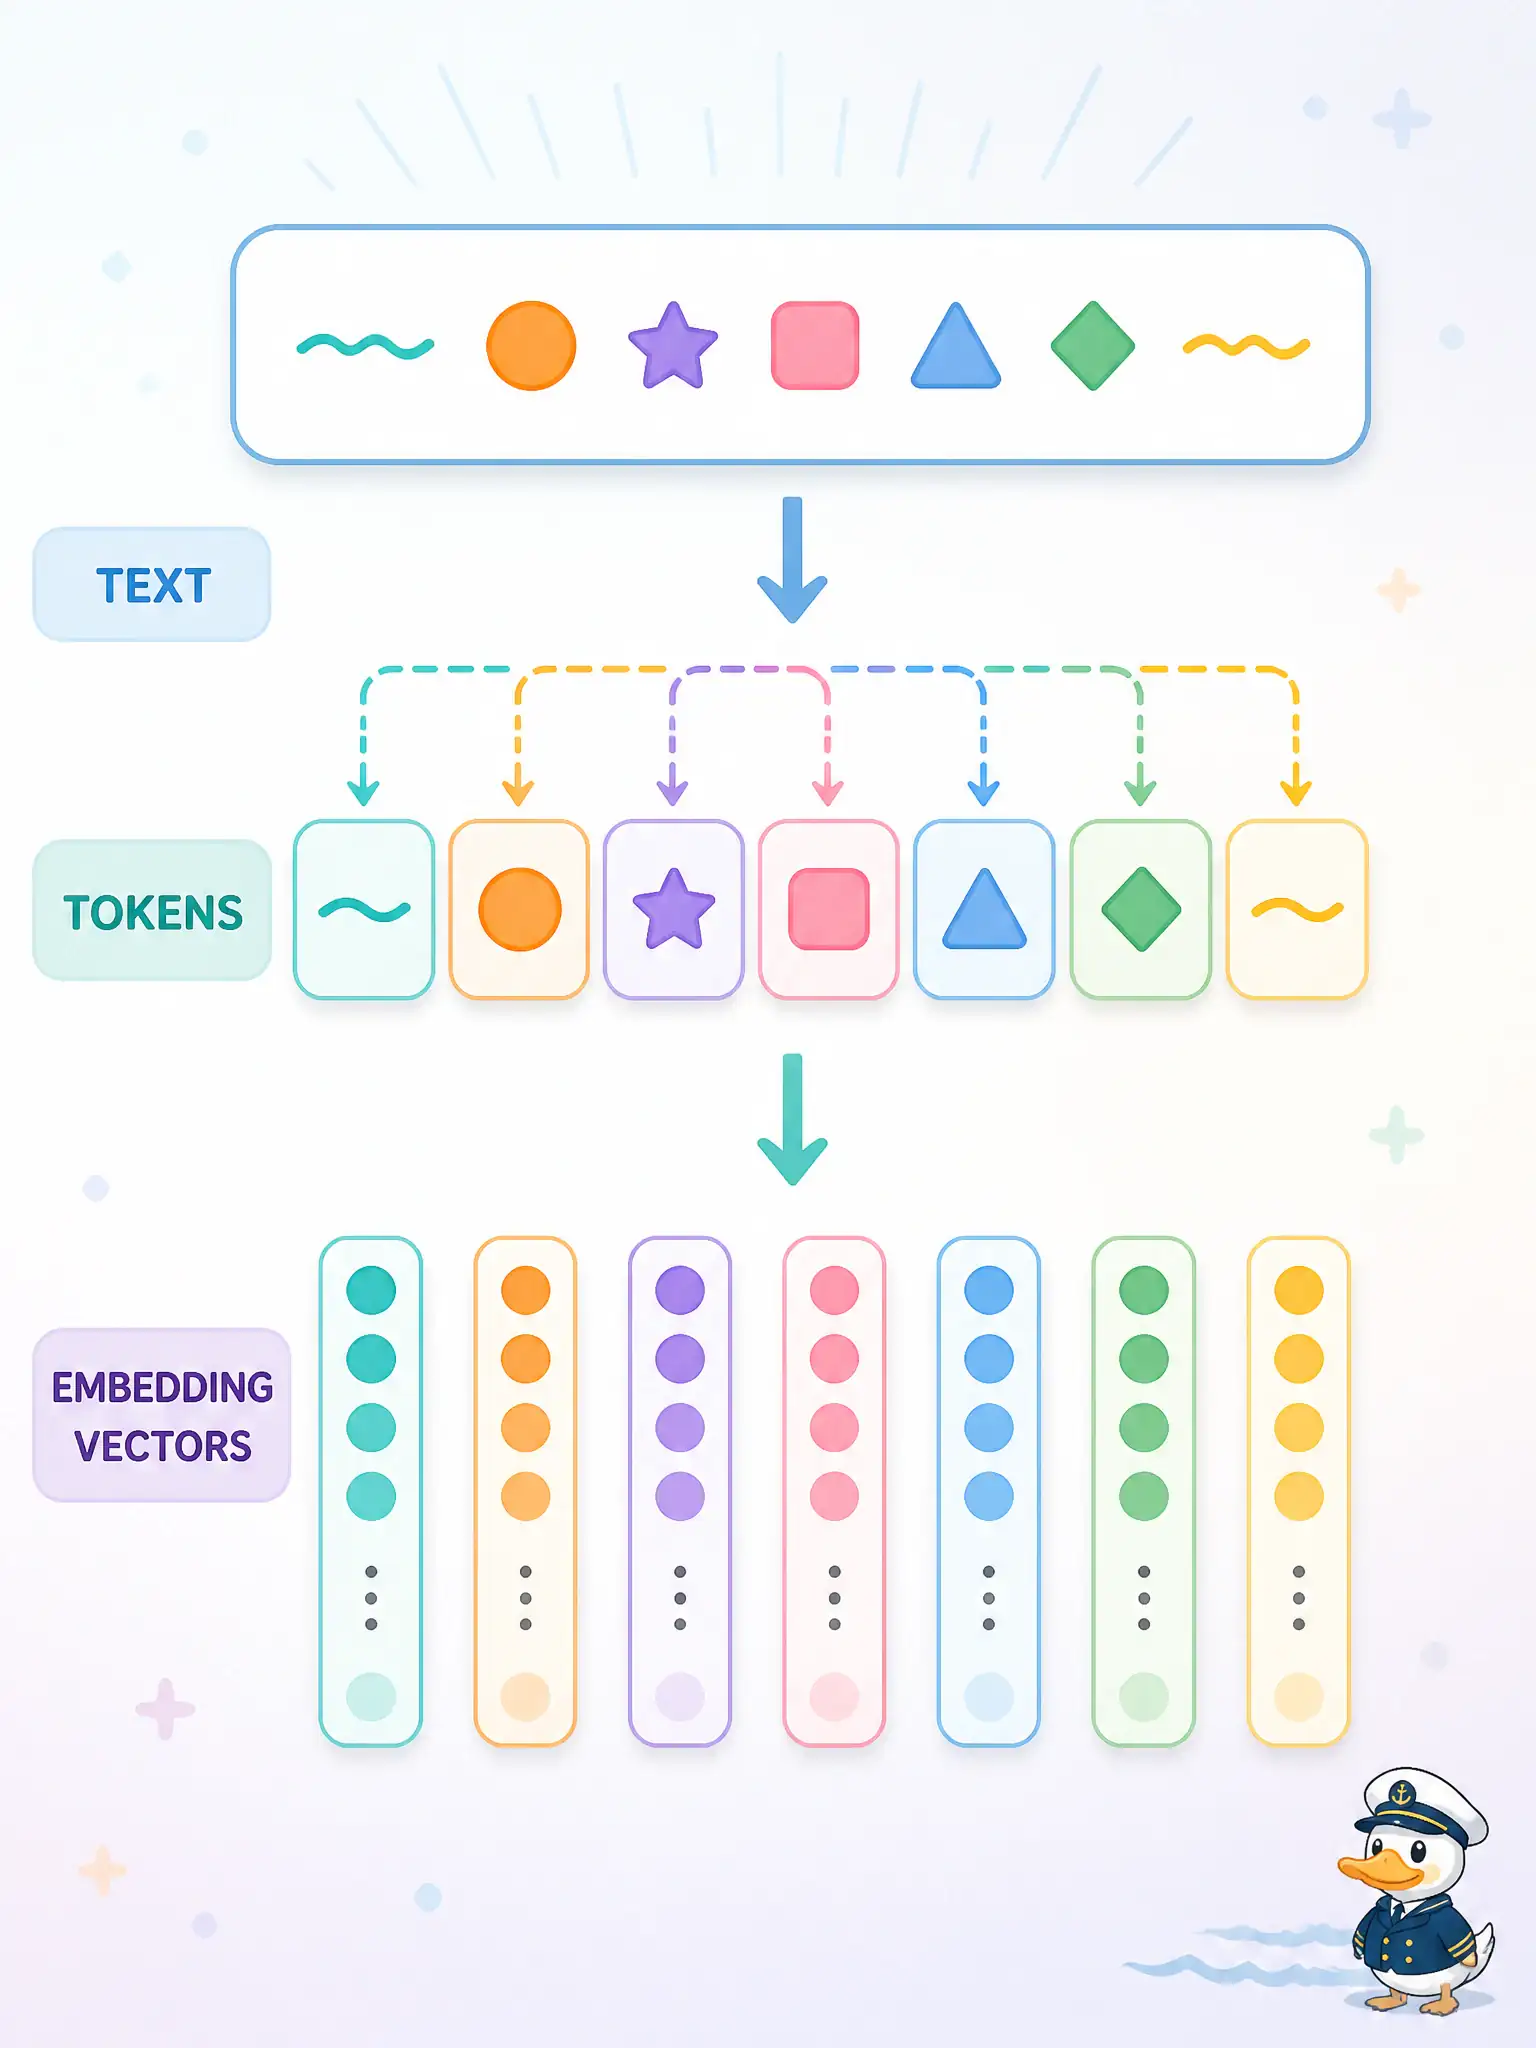
Short Explanation
Text has to become chips the matrix can multiply. Tokenize the sentence, then embed those tokens as vectors—raw bytes or street addresses will not do.
Full Explanation
A linotype shop’s repair sentence must be tokenized and embedded as vectors before weight matrices inside a language model can multiply it. Leaving the sentence as a raw PDF byte blob without tokenization is not neural-network ready text. Feeding the printer’s street address as the only feature ignores the repair sentence. Converting the sentence into a spectrogram treats text as if it were audio and skips the language interface. Exam caveat: text readiness is tokens plus embeddings even in multimodal civic shops. Operational check: run the repair sentence through the model’s tokenizer and embedding table; verify tensor shapes match the first language-block input before any matrix multiply. Assert tokenizer vocabulary coverage on linotype repair jargon before training. Linotype repair text becomes matrix-ready only after tokenization and embedding—not as PDF bytes or spectrograms. Gate linotype language training on a tokenizer smoke test that embeds a sample repair sentence and asserts the expected tensor rank and vocabulary hits on shop terms. Close q109 with a municipal evidence note that records why the correct mechanism fits this civic multimodal scenario, why each of the three distractors fails by a distinct concept, and which operational check was observed in logs or dataset cards before promotion. File that note with the run packet so later maintenance cannot silently revive a rejected framing.