
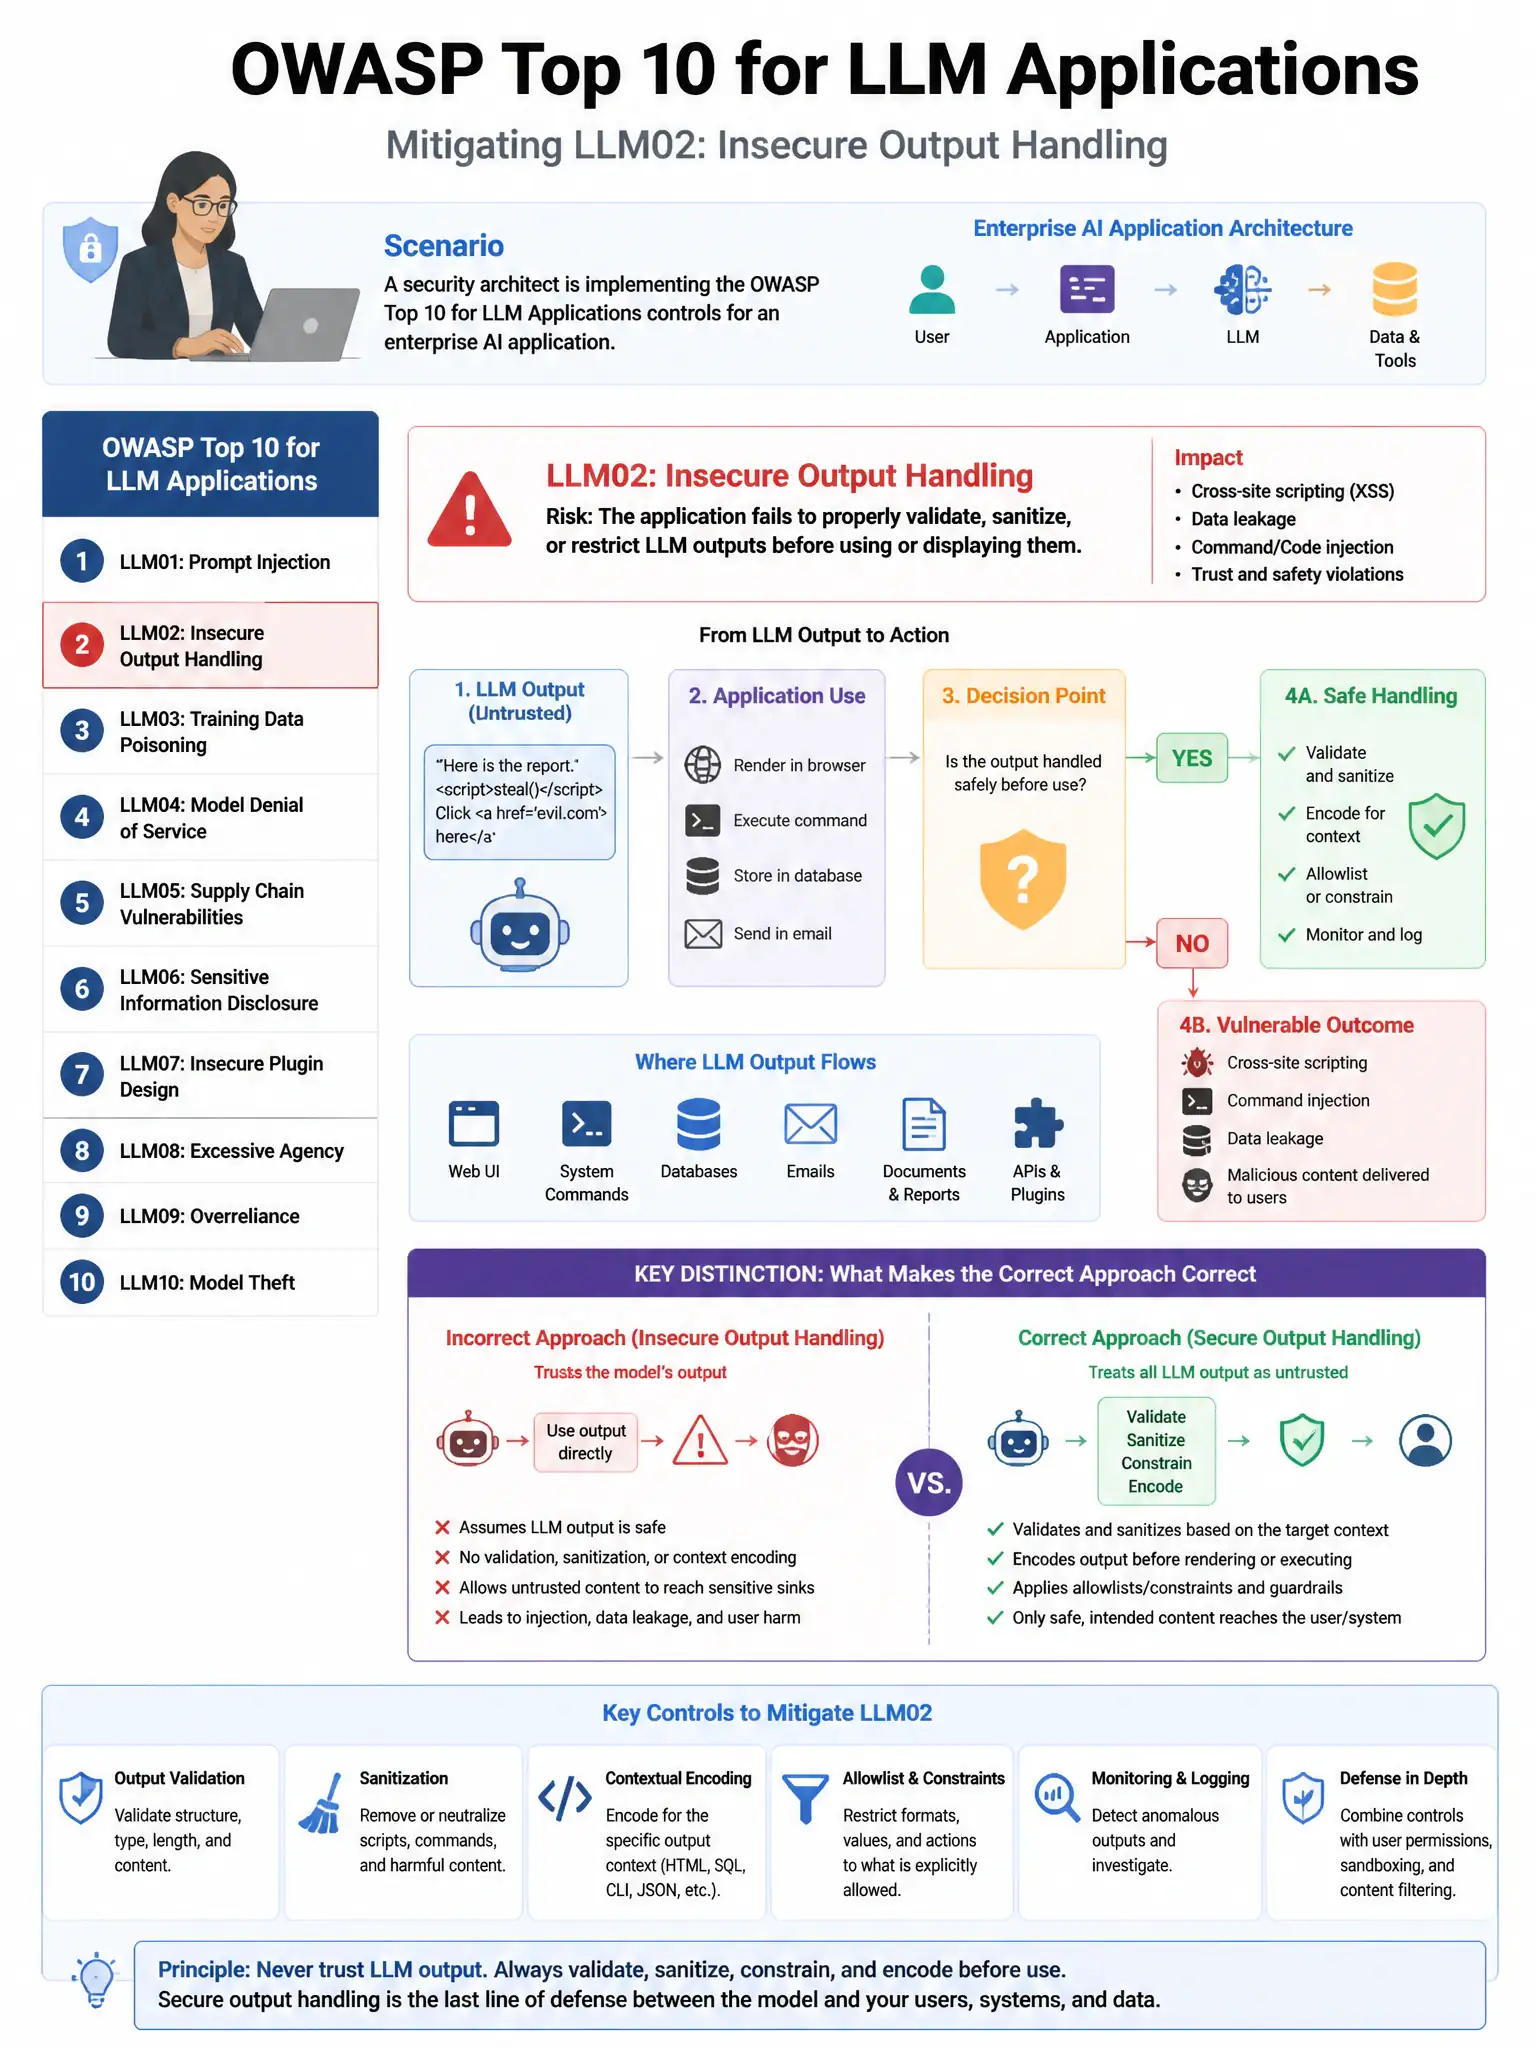
A security architect is implementing the OWASP Top 10 for LLM Applications controls for an enterprise AI application. The application is at risk of 'LLM02: Insecure Output Handling' which could lead to XSS or SQL injection via AI-generated content. Which control addresses this risk?
Select an answer to reveal the explanation.
Short Explanation
Here's the deal — you need to treat AI-generated output as untrusted input and encode or sanitize it before rendering it in a web application or passing it to downstream systems. That's exactly what LLM02: Insecure Output Handling is about, because it stops XSS or SQL injection from model output.
Full Explanation
The output encoding/sanitization control is correct because LLM02: Insecure Output Handling specifically addresses the risk that AI-generated output containing code, markup, or query fragments is passed directly to interpreters, such as web browsers rendering HTML/JavaScript or databases executing SQL, without proper encoding or sanitization. The control is to treat AI outputs as untrusted input and apply appropriate encoding or sanitization before rendering or executing. The Azure AI Content Safety option is incorrect because it filters for harmful content categories such as violence or hate speech, but it does not sanitize XSS or SQL injection payloads that a model might generate while following legitimate instructions. The Azure OpenAI content filtering option is incorrect because it also targets harmful content categories, not code injection payloads in model outputs. The strict input validation option is incorrect because input validation addresses LLM01: Prompt Injection, not LLM02, which is specifically about unsafe handling of the model's output.