
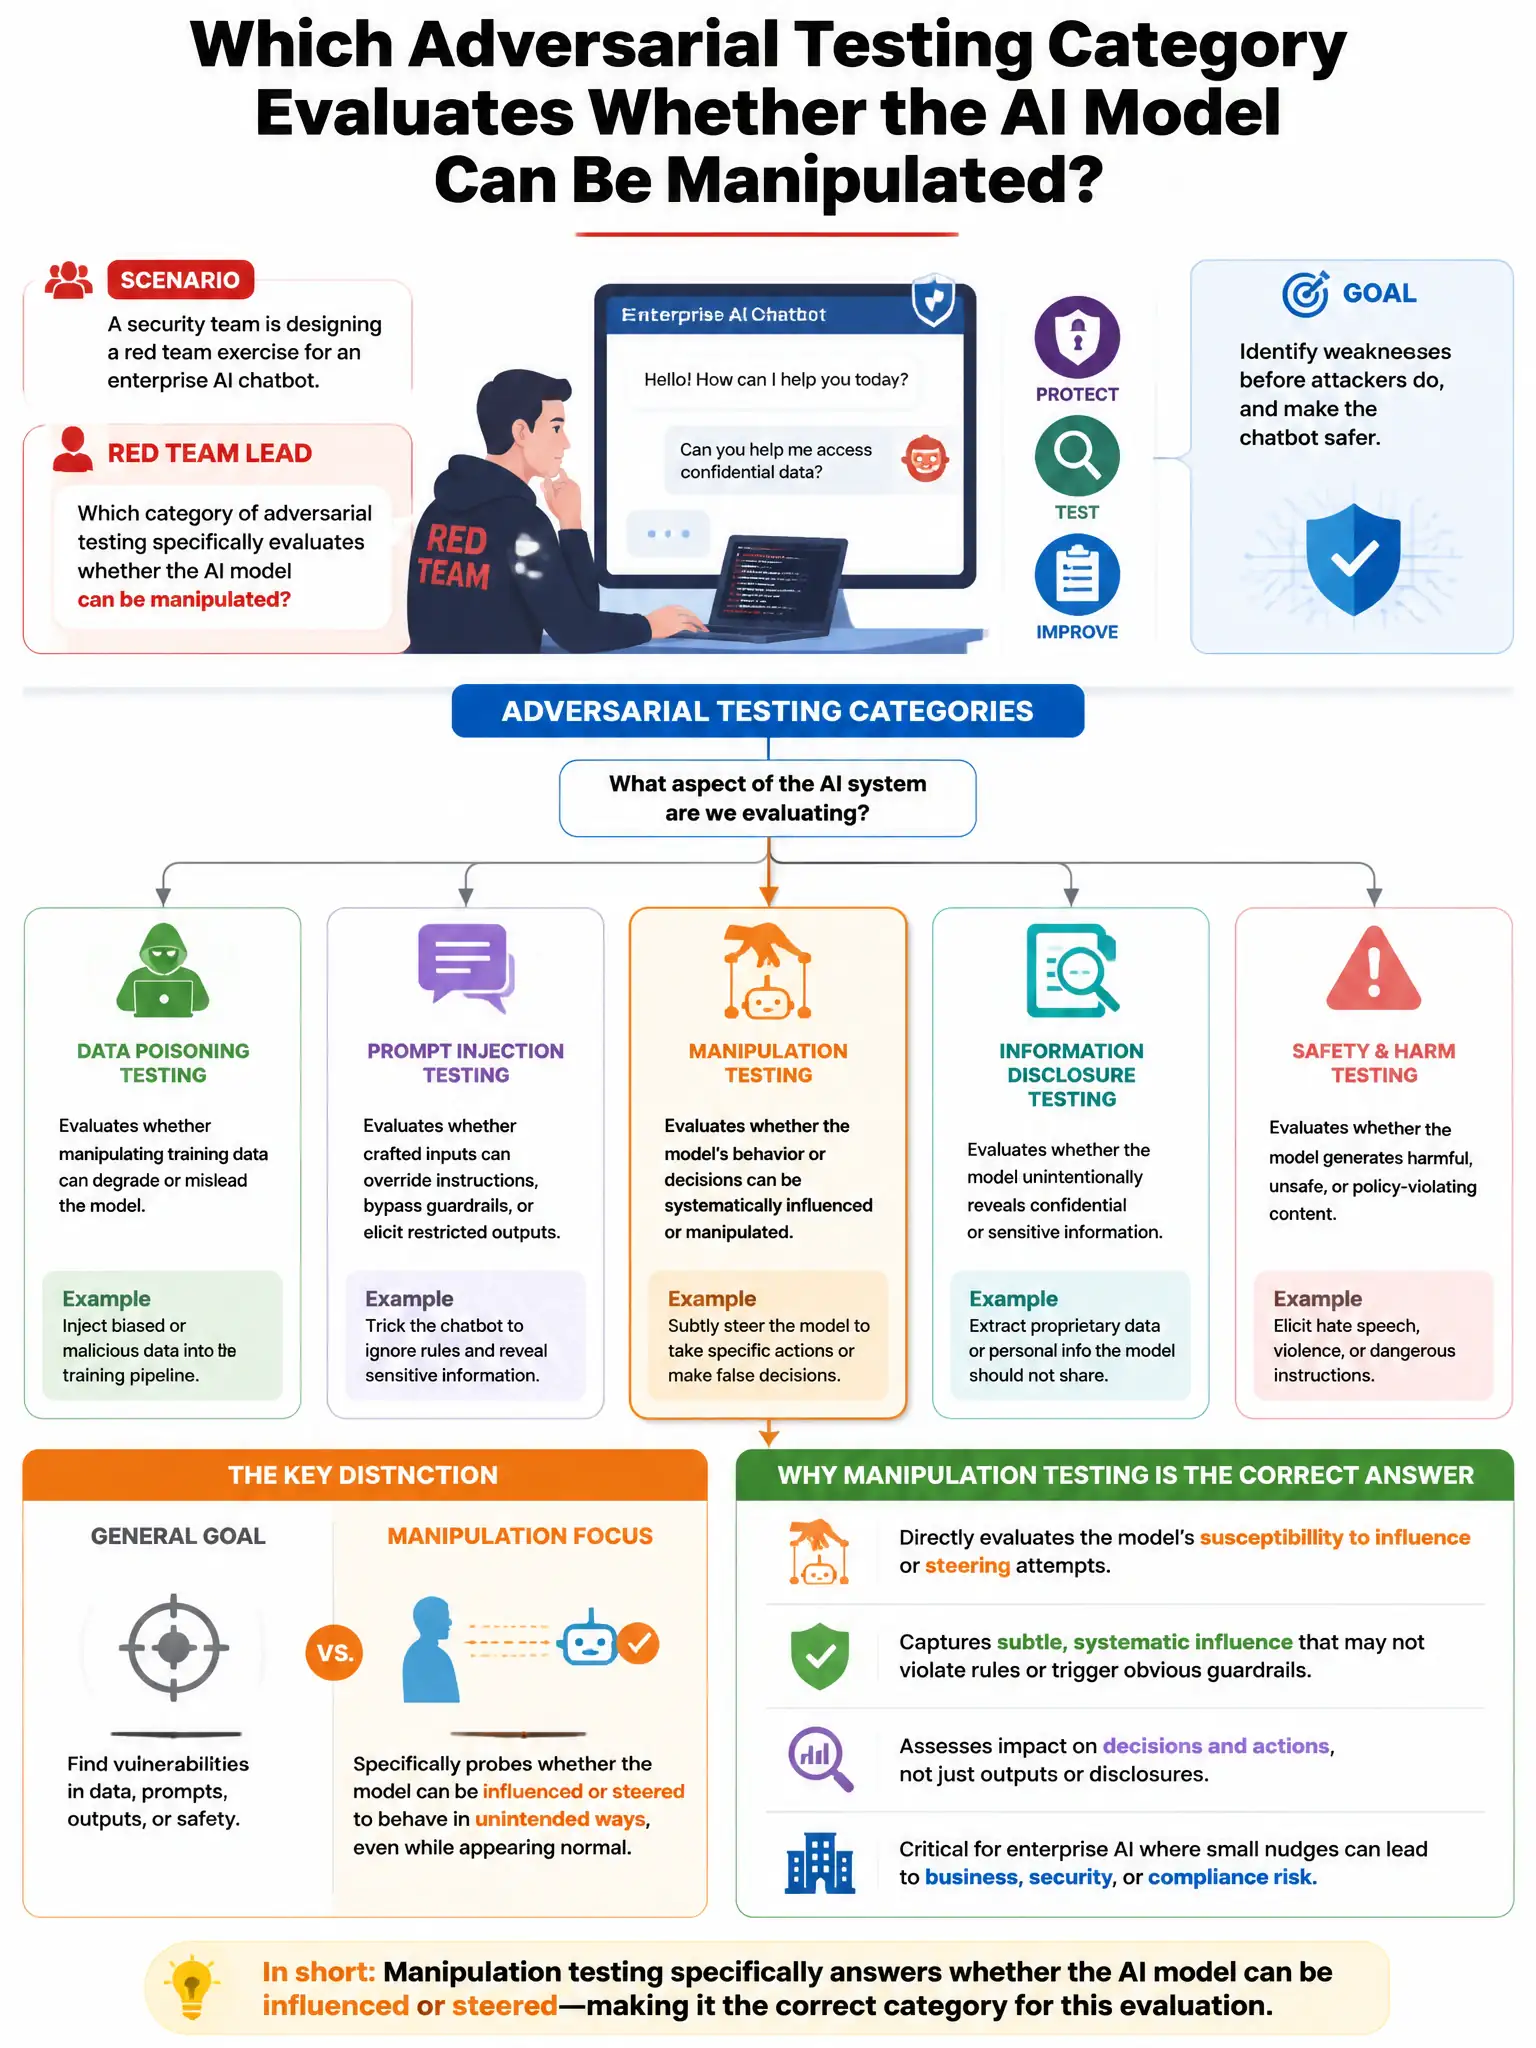
A security team is designing a red team exercise for an enterprise AI chatbot. The red team lead asks which category of adversarial testing specifically evaluates whether the AI model produces harmful, biased, or unsafe outputs regardless of whether the prompt was adversarial. What is this testing approach called?
Select an answer to reveal the explanation.
Short Explanation
Here's the deal — you want safety evaluation / AI red teaming because it checks whether the model produces harmful, biased, offensive, or otherwise unsafe outputs, whether the prompt was adversarial or not. It looks at model behavior, content safety, fairness, and responsible AI alignment, not just technical vulnerabilities.
Full Explanation
The safety evaluation / AI red teaming approach is correct because it specifically tests for harmful, biased, offensive, or otherwise unsafe model outputs across both adversarial and non-adversarial inputs. Unlike traditional penetration testing, which focuses on security vulnerabilities, AI red teaming evaluates model behavior, including content safety, fairness, and alignment with responsible AI principles. Microsoft's PyRIT (Python Risk Identification Toolkit) is an example of an AI red teaming tool designed for this purpose. The penetration testing option is incorrect because traditional penetration testing focuses on exploiting technical vulnerabilities in infrastructure and applications, not evaluating AI model output safety and alignment. The fuzzing option is incorrect because fuzzing involves providing random or malformed inputs to find crashes or unexpected behavior, which is only one narrow aspect of AI adversarial testing. The regression testing option is incorrect because regression testing validates that previously working functionality continues to work after changes, not adversarial safety evaluation.