
An education platform for teenagers is hardening its Foundry-hosted study-help assistant against producing self-harm content after a red-team test surfaced a concerning reply. The safety team wants configuration changes that directly reduce the chance of that content appearing again, not changes that merely make the assistant sound friendlier. (Select TWO.)
Select all correct answers, then click Submit.
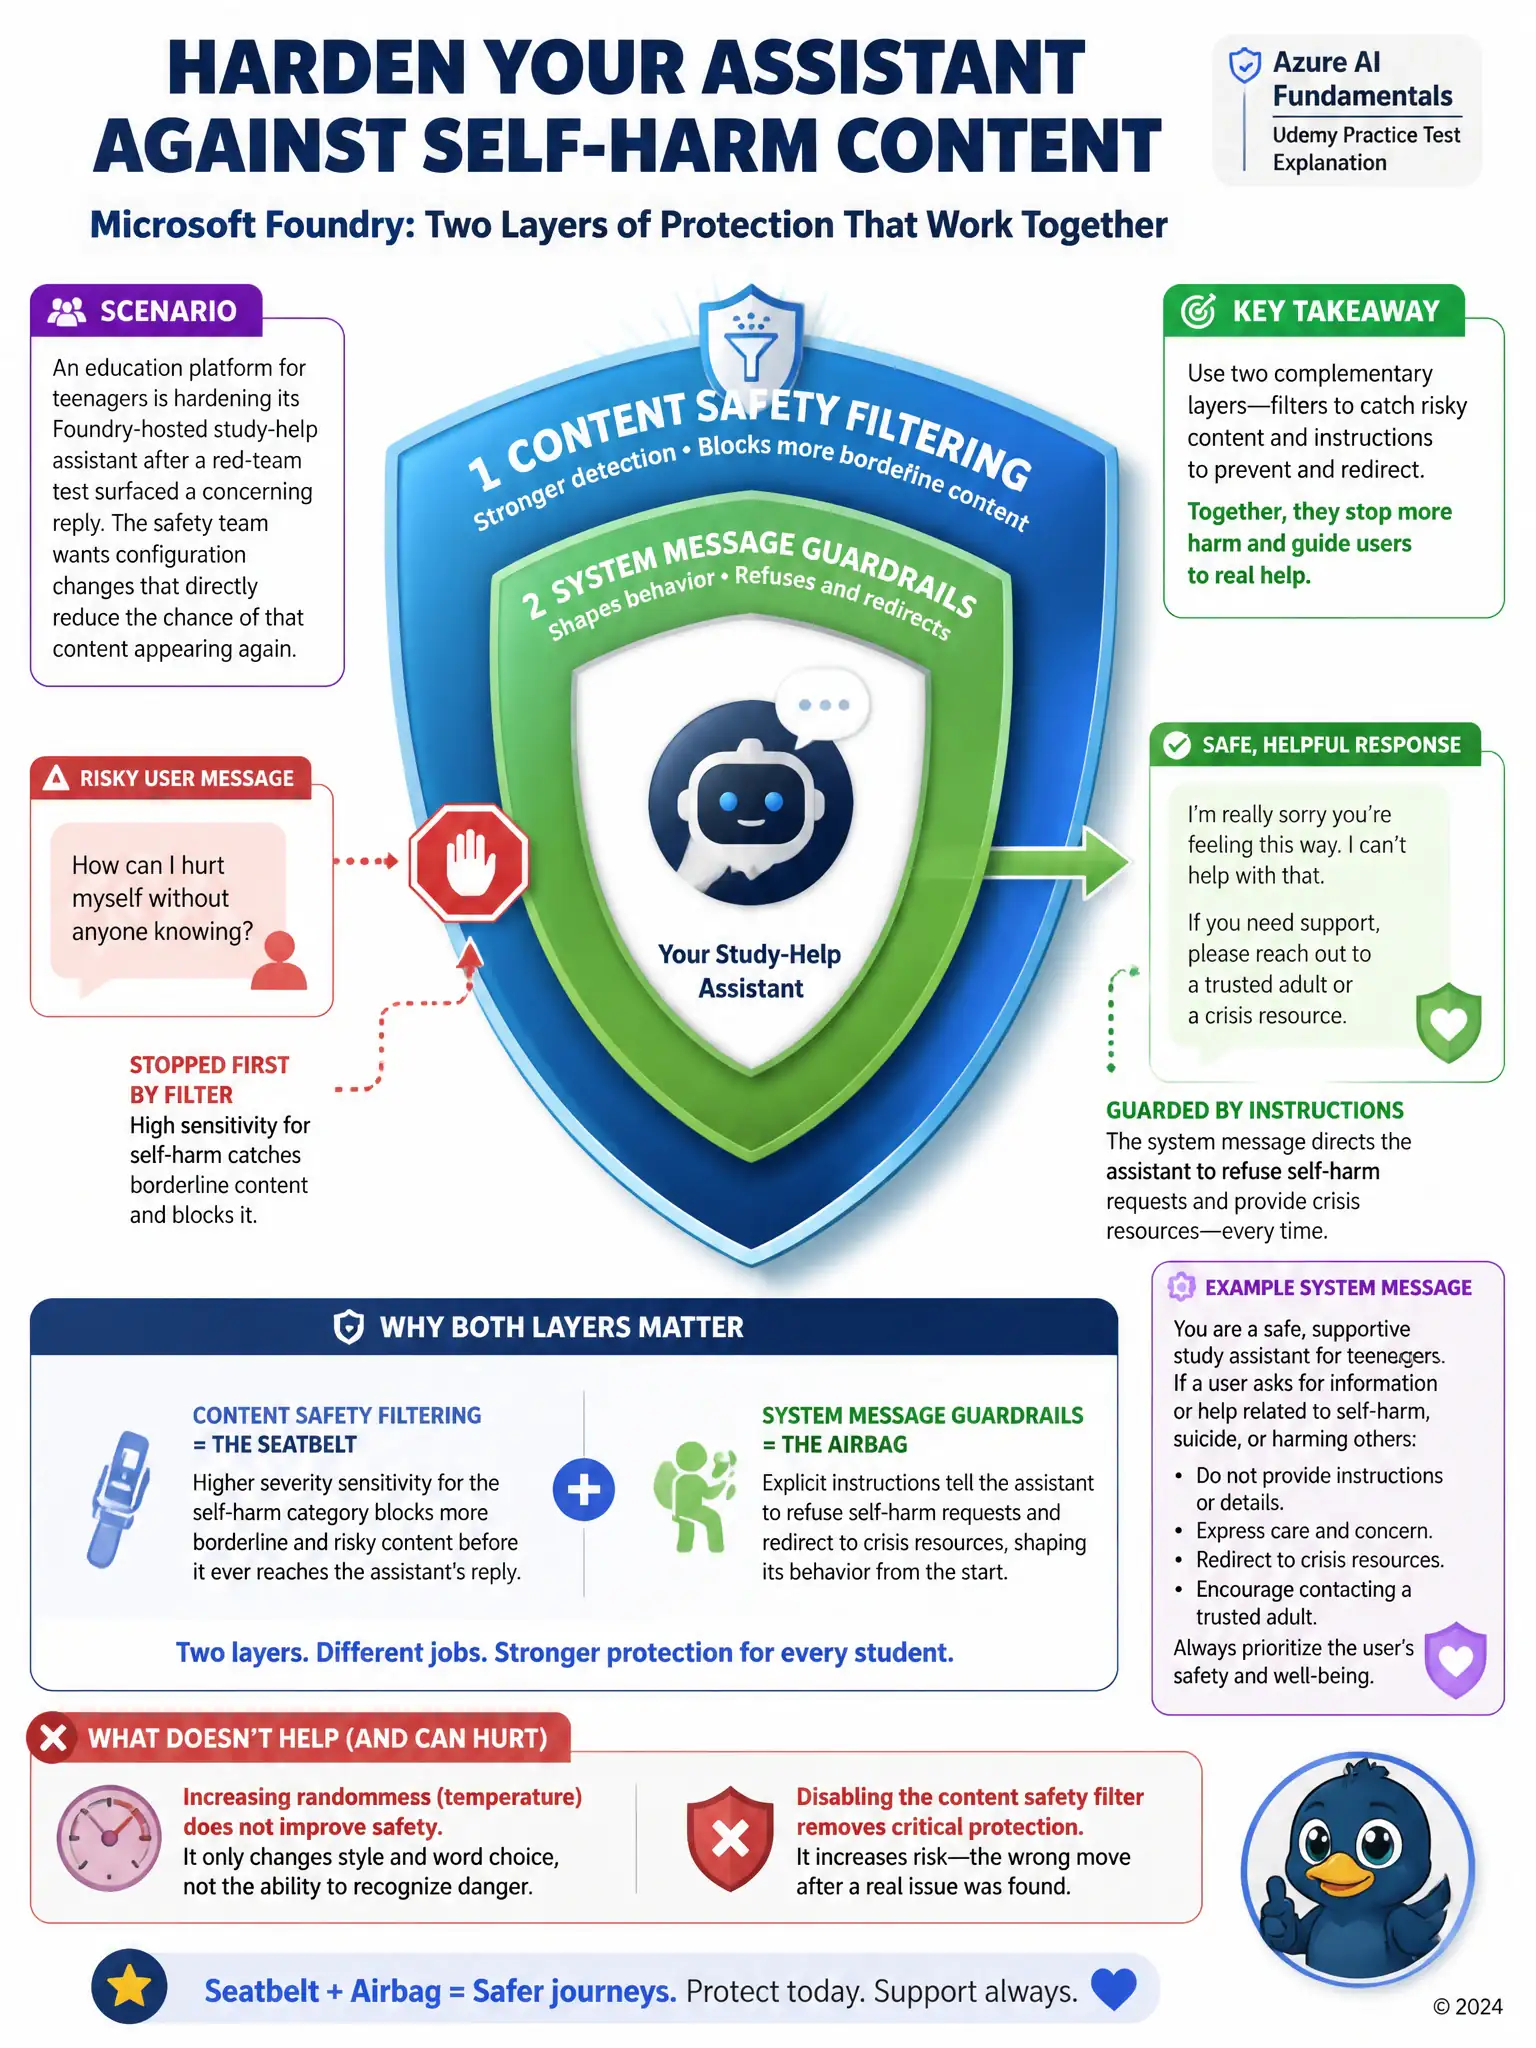
Short Explanation
You want two layers doing different jobs. Turning up the self-harm sensitivity in the content safety filter catches more borderline replies before a teenager sees them, and a system message that tells the assistant to refuse self-harm requests and point to crisis resources shapes what it tries to say first. Warmer wording or turning the filter off won't close the safety gap.
Full Explanation
The correct choices are raising the Content Safety filter's severity sensitivity for the self-harm category and adding a system message that explicitly instructs the assistant to refuse self-harm requests and redirect to crisis resources. Raising the Content Safety filter's sensitivity for the self-harm category causes more borderline outputs to be blocked before they reach the user, directly reducing the chance of harmful content getting through. Pairing that with a system message that explicitly instructs the assistant to refuse such requests and redirect to crisis resources shapes the model's behavior at generation time, so the two controls work together at different layers of the pipeline. Increasing the temperature parameter so replies feel warmer and more empathetic is incorrect because temperature only controls how random or varied the wording of a response is; it does not make the assistant safer or more likely to recognize and refuse a harmful request, and could make behavior less predictable. Disabling the content filter for this deployment to avoid false positives blocking legitimate discussion is incorrect because it removes a safety layer entirely, which is the opposite of what the team needs after a red-team test already showed a gap; false positives should be tuned through severity thresholds, not eliminated by turning protection off.