
A retail company's Foundry-hosted chatbot experiences a sudden traffic spike during a flash sale, and many requests begin failing with HTTP 429 'too many requests' errors from the model deployment. The engineering team needs to both keep the application resilient right now and prevent this from recurring during future sales events. (Select TWO.)
Select all correct answers, then click Submit.
Short Explanation
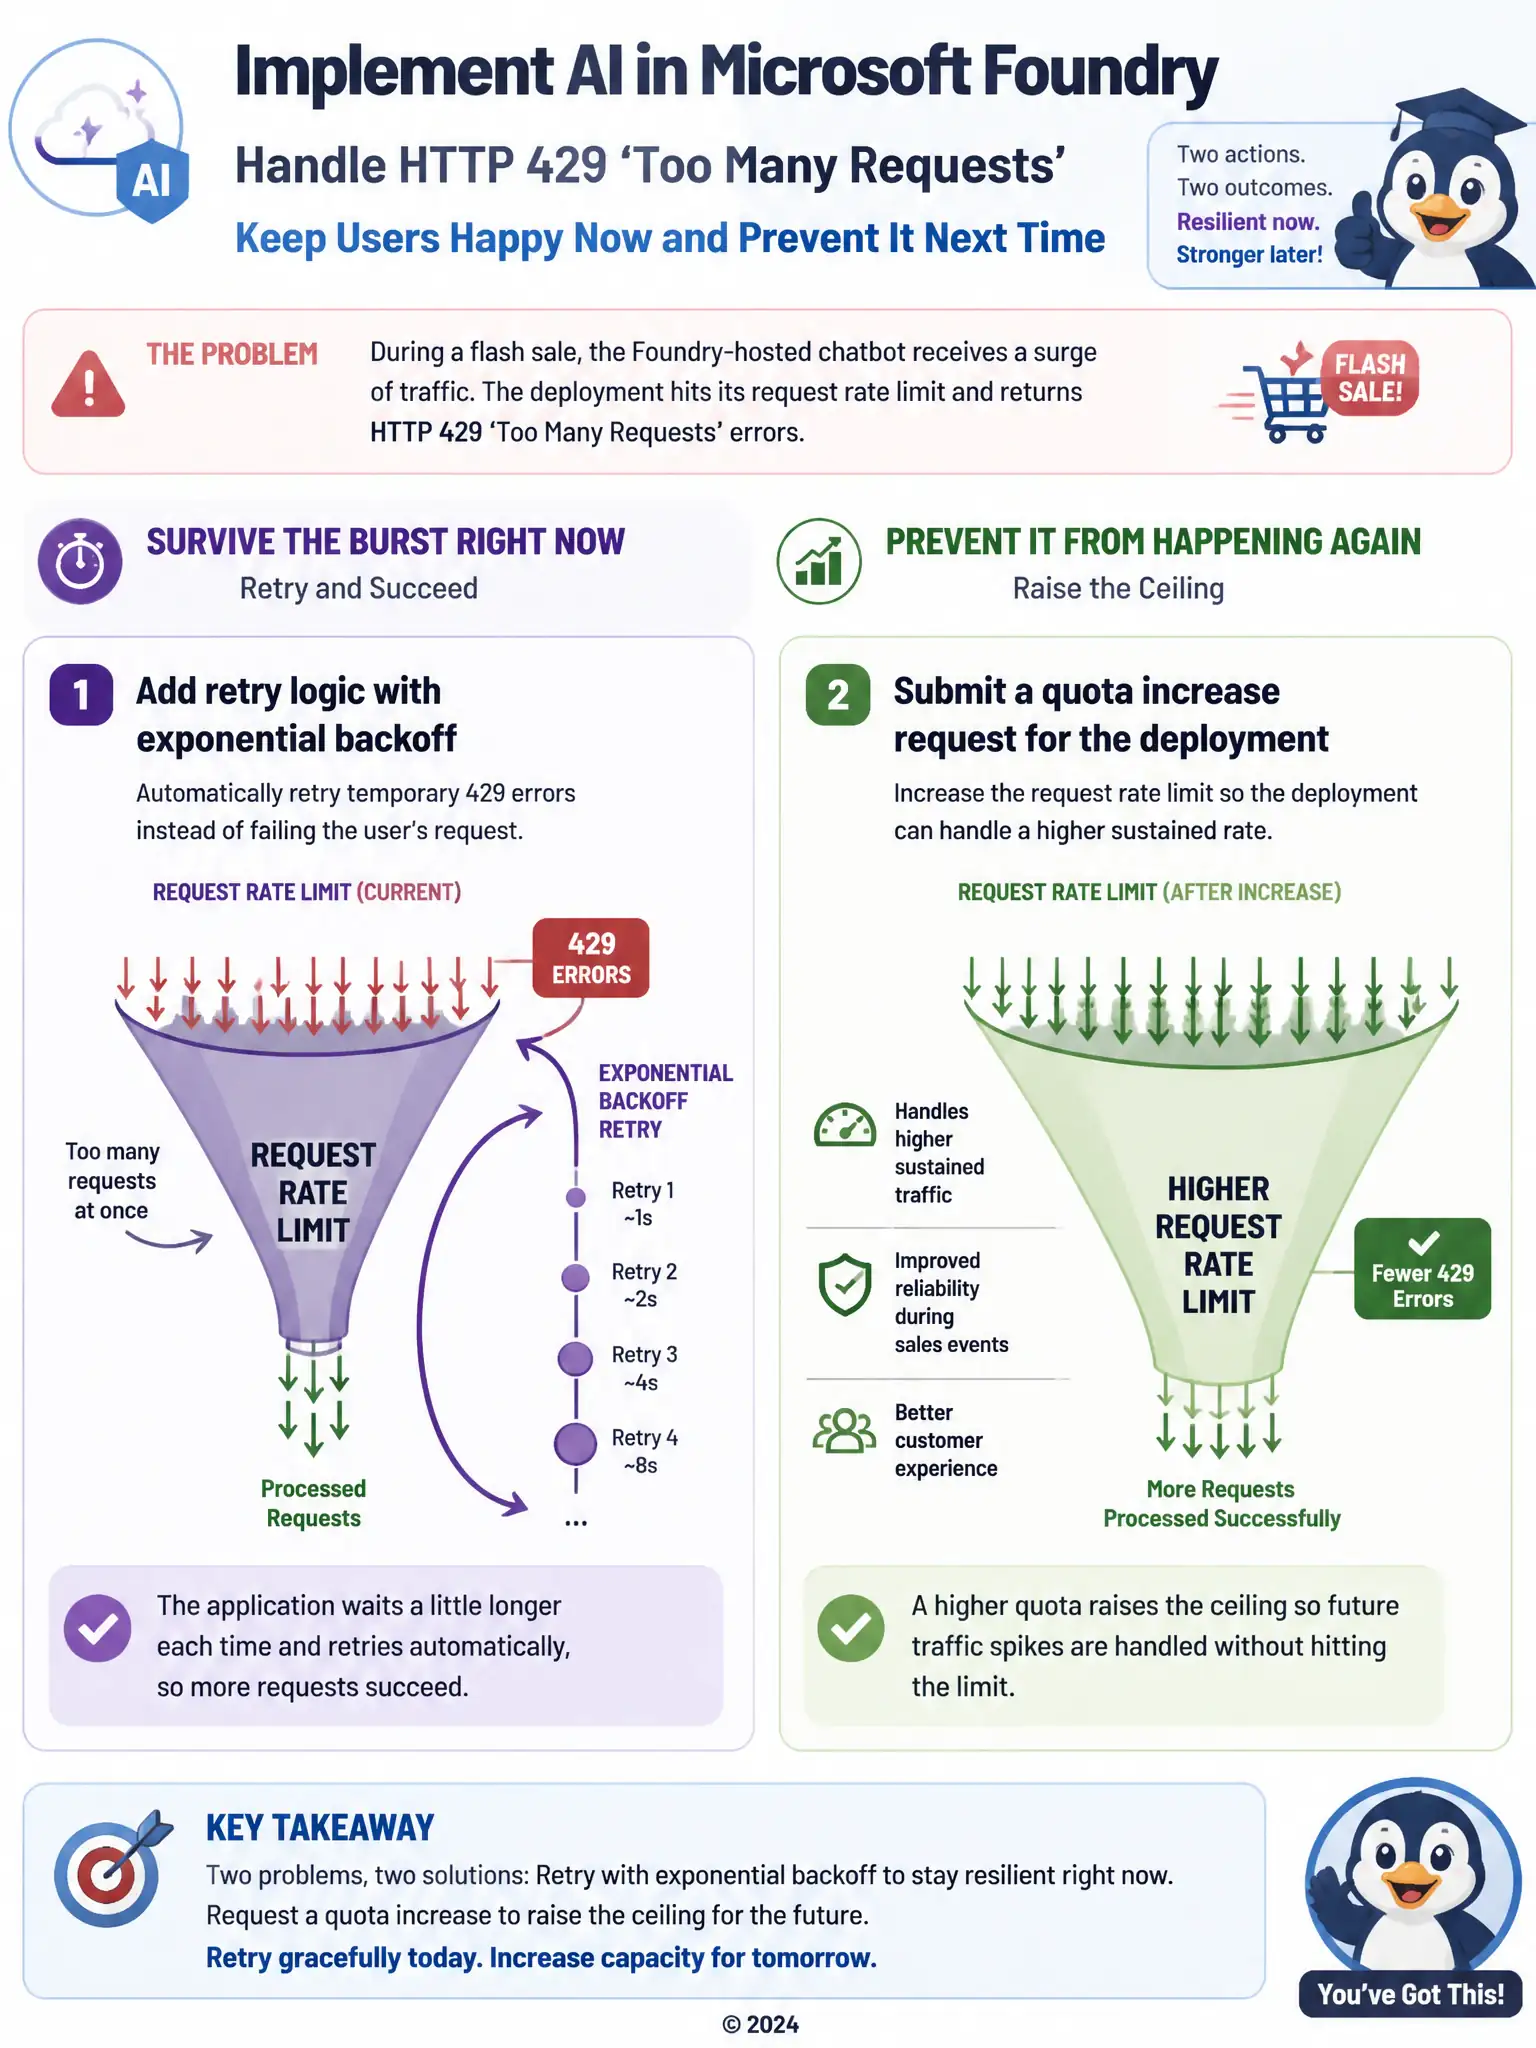
When a Foundry deployment starts returning 'too many requests' errors, you need to ride out the current spike and raise the ceiling for the next one. Add retry logic with exponential backoff so temporary 429 responses are retried automatically instead of failing the customer's request. Submit a quota increase request for the deployment so it can handle a higher sustained rate of requests.
Full Explanation
The two correct choices are retry logic with exponential backoff and submitting a quota increase request for the deployment. Retry logic with exponential backoff addresses the immediate resilience problem by automatically retrying requests that fail with a temporary 429 instead of surfacing an error to the user, smoothing over short bursts above the rate limit. Submitting a quota increase request addresses the recurrence problem directly by raising the deployment's allowed request rate so future traffic spikes of similar size stay under the limit in the first place. Lowering the model's temperature setting is incorrect because temperature controls the randomness and variety of the model's generated text; it has no effect on how many requests per minute the deployment can accept, so lowering it does nothing to reduce or prevent 429 errors. Switching the deployment's output format from streaming to non-streaming responses is incorrect because streaming versus non-streaming changes how the response is delivered to the client, token by token versus all at once, but it does not change the number of requests being sent to the deployment or the rate limit governing them, so switching formats leaves the underlying throttling issue untouched. Together, retry logic with exponential backoff and a quota increase form a complete answer: one absorbs short-term spikes gracefully, and the other raises the ceiling so the same spike is less likely to trigger throttling again.