
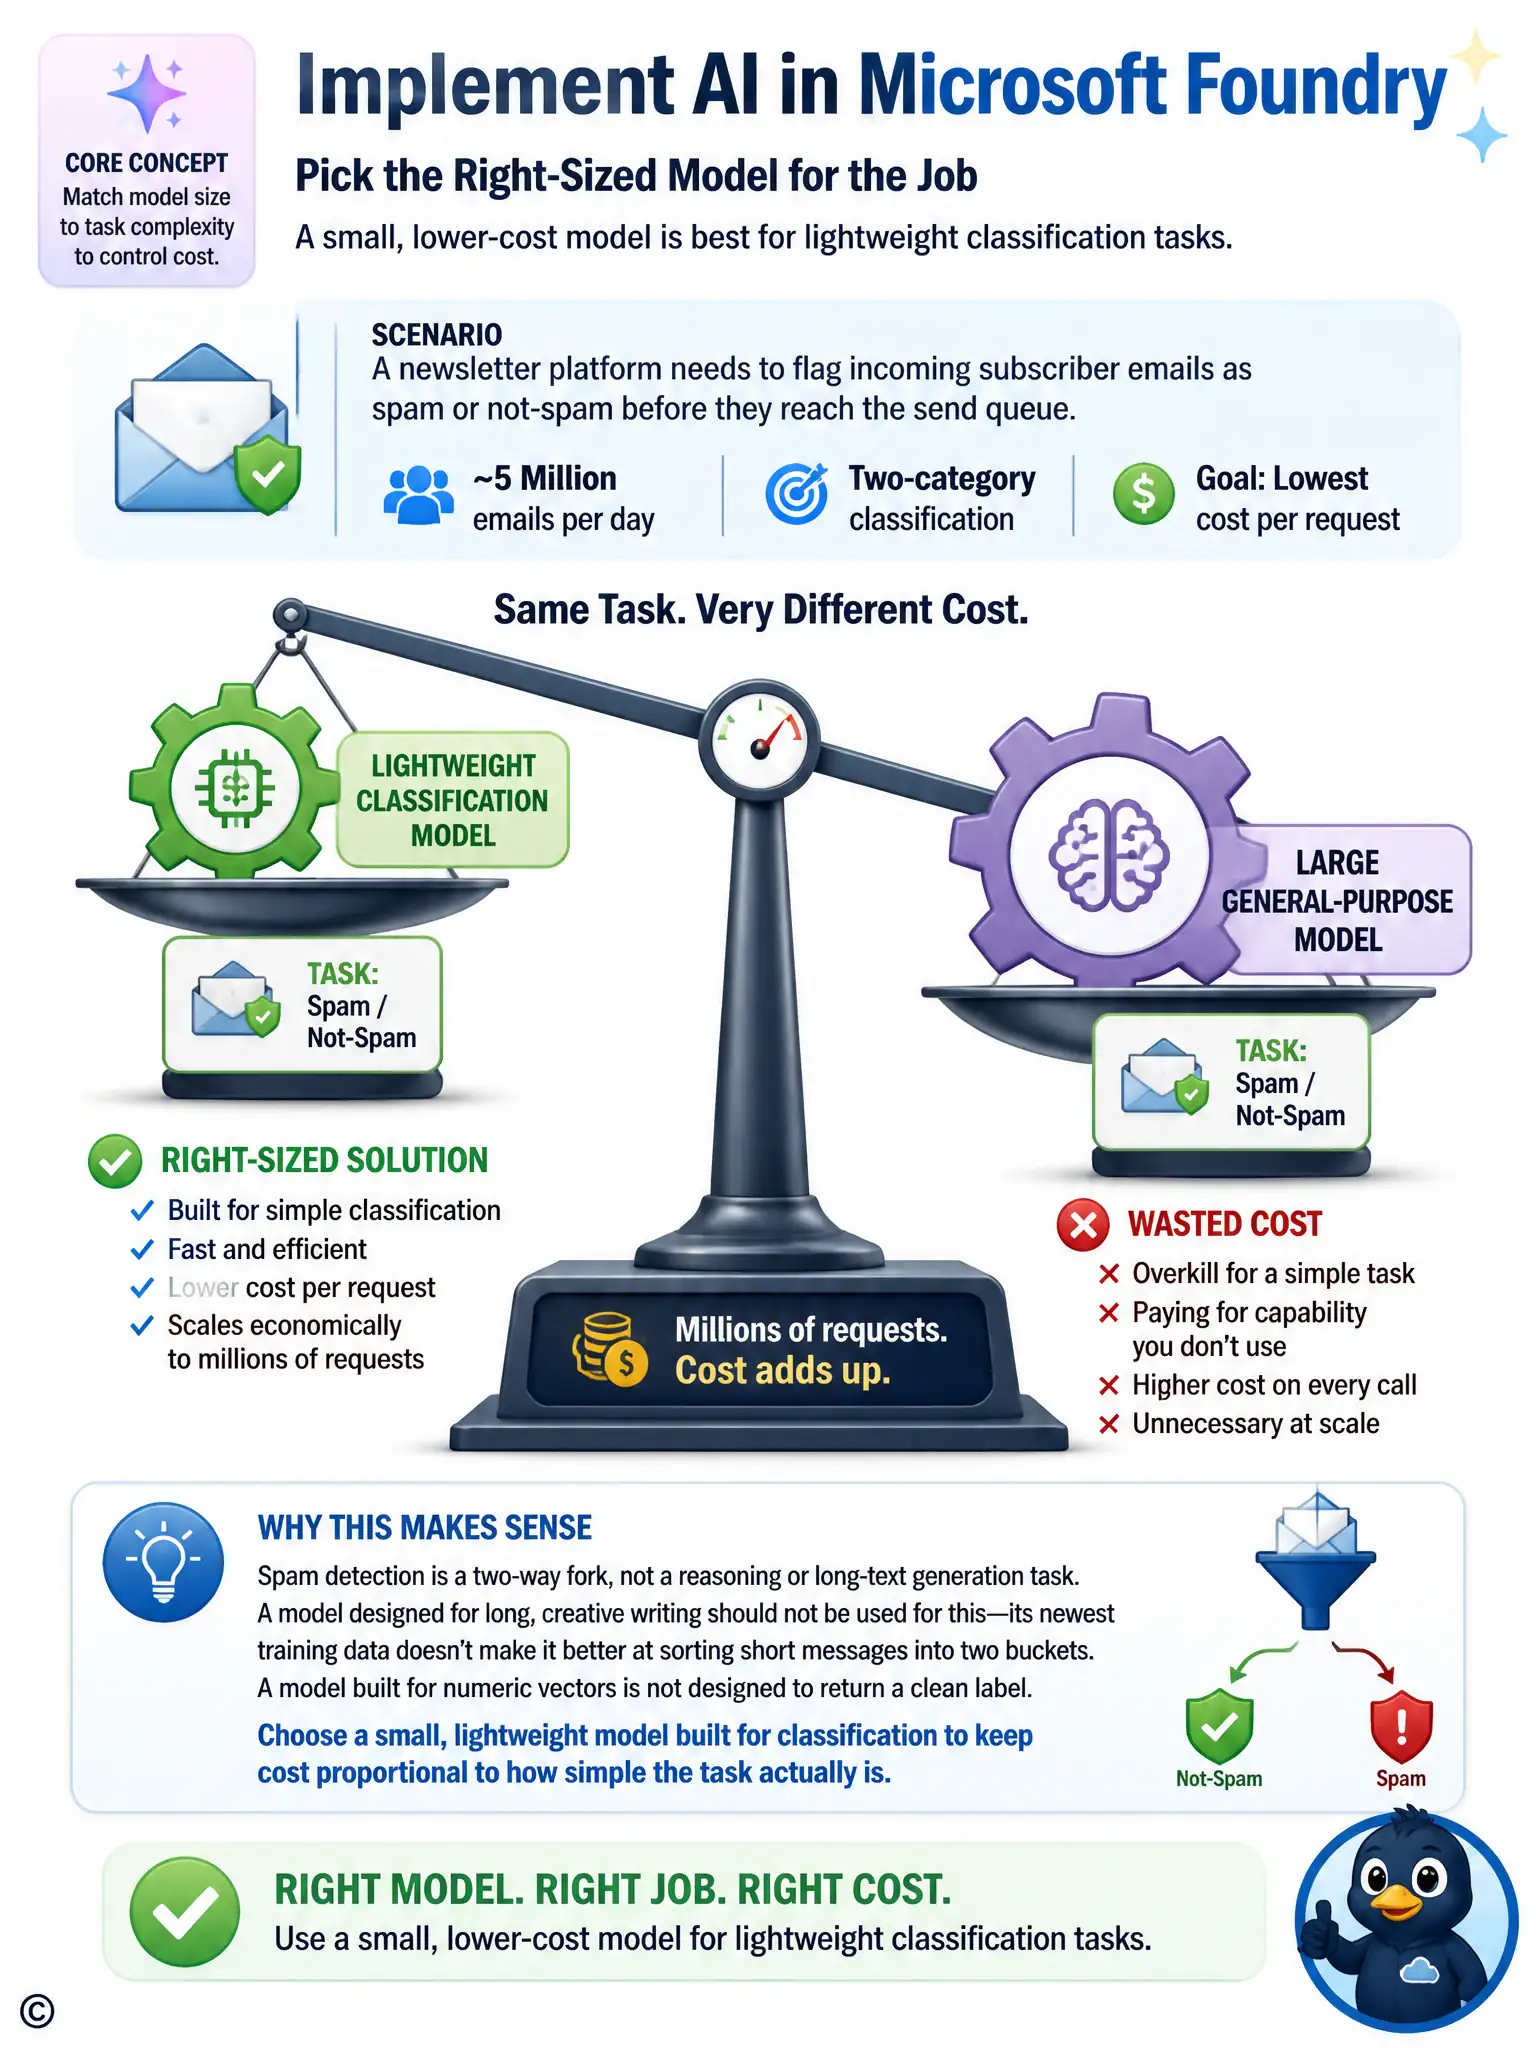
A newsletter platform wants to flag incoming subscriber emails as spam or not-spam before they reach the send queue, processing on the order of five million emails per day. The task is a straightforward two-category classification, and the team is under pressure to keep the per-request cost as low as possible without hosting their own infrastructure. Which choice from the Foundry model catalog best fits this situation?
Select an answer to reveal the explanation.
Short Explanation
You match the tool to the job. Spam or not-spam is a simple two-way classification, so a small, lower-cost model sized for lightweight classification keeps per-request cost down without wasting money on unused capability.
Full Explanation
The best fit is the small, lower-cost model sized for lightweight classification tasks rather than the largest general-purpose model available. A binary spam classification task is well within the capability of a small, lower-cost model, and at a volume of five million requests per day, choosing a smaller model sized for lightweight tasks keeps per-request cost low while still meeting the accuracy the task actually requires. The embedding-only choice is incorrect because embedding models are designed to output numeric vector representations of text for tasks like search and similarity comparison; they are not built to be prompted for a direct classification label, and using one this way is not their intended function or a reliable pattern. The most capable large-scale GPT choice is incorrect because assuming higher accuracy is always worth the cost ignores the actual requirement in the scenario, keeping per-request cost as low as possible, and applying the largest general-purpose model to a simple two-category task multiplies cost at high volume without a corresponding benefit for such a straightforward decision. The long-form creative text choice is incorrect because a model optimized for long-form creative generation is tuned for a completely different capability, producing extended original text, which has no relevance to sorting short emails into two categories, and recency of training data does not compensate for the mismatch in task fit. Matching model size to task complexity is the deciding factor here, not simply picking the newest or largest available option.