
An expense-management startup wants employees to photograph paper receipts with their phones and have a Foundry-hosted assistant automatically read the merchant name, date, and total amount directly from the image, without an employee typing anything. Which type of model deployment should the team choose from the Foundry model catalog?
Select an answer to reveal the explanation.
Short Explanation
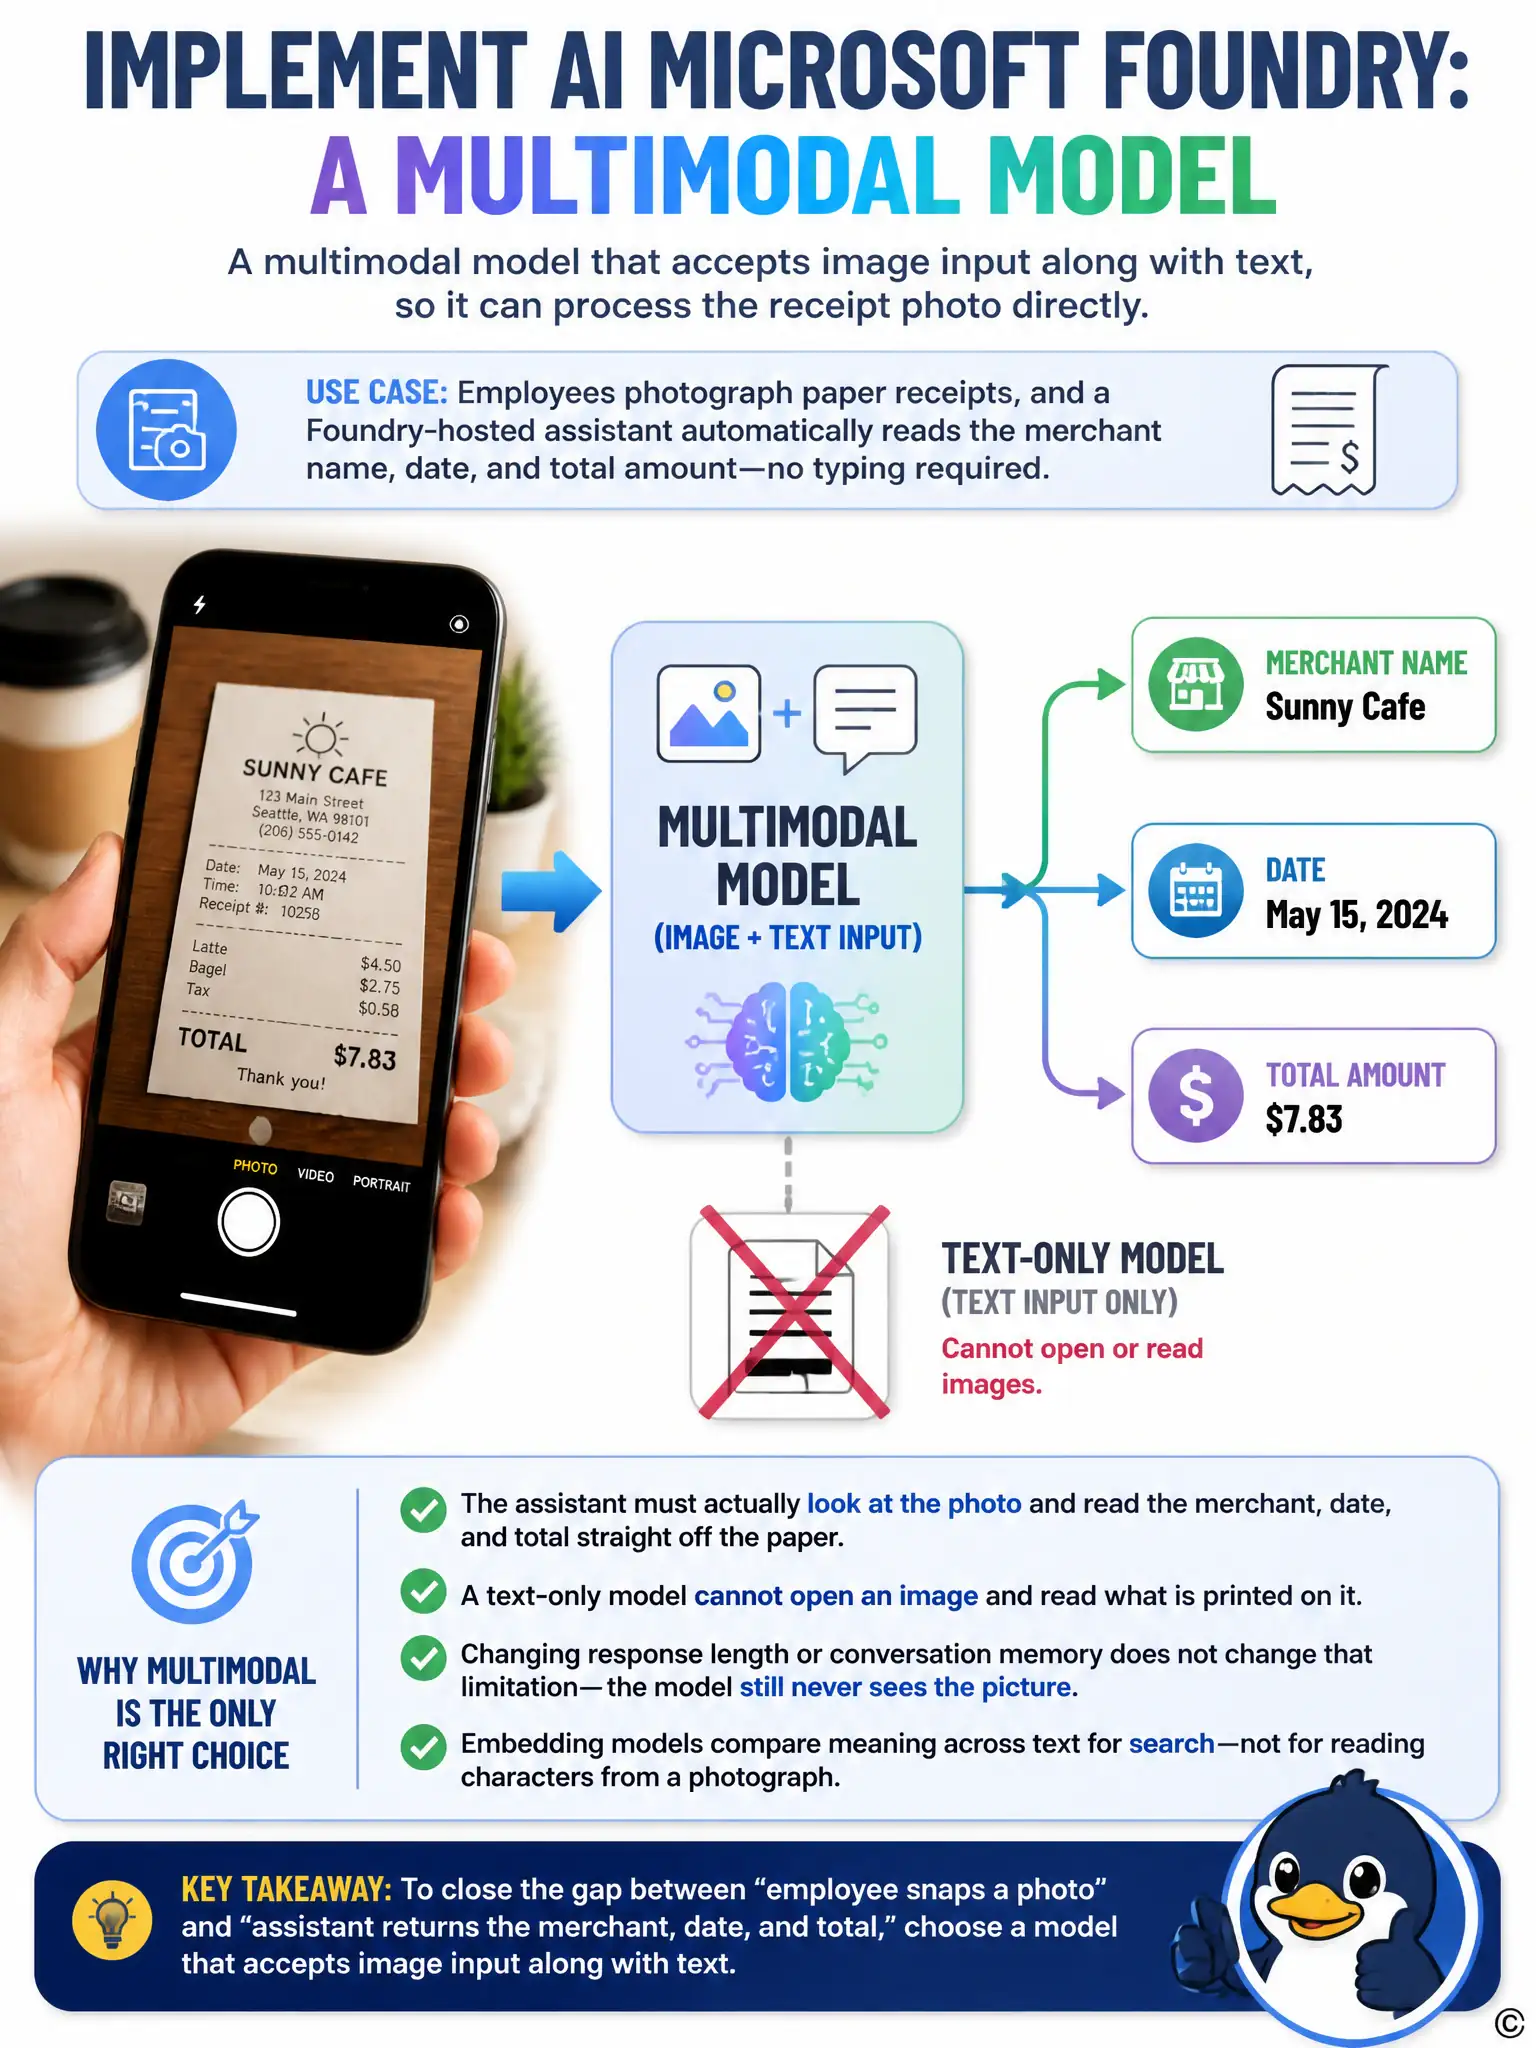
You need a model that can actually look at the receipt photo, so pick the multimodal model that accepts image input along with text. Text-only models can't see the picture no matter how you tune output length or context, and embedding models are for vector similarity search, not reading receipts.
Full Explanation
The correct choice is the multimodal model that accepts image input along with text, because the task requires reading information directly out of a photograph. That model can look at the receipt photo and extract the merchant name, date, and total without any employee transcribing it beforehand. The text embedding model to convert receipt descriptions into vectors for similarity search is incorrect because an embedding model converts text into numeric vectors for similarity comparison and search; it has no ability to interpret pixels in an image or read printed text off a receipt. The text-only model paired with a larger max_tokens setting is incorrect because increasing max_tokens only changes how much text the model can produce in a response; a text-only model still cannot accept an image as input no matter how the output length is configured, so it never sees the receipt at all. The text-only chat model with a longer context window to hold more conversation history is incorrect for the same core reason: a longer context window lets a text-only model retain more conversation history, but context length does not add the ability to process visual input, so the receipt photo still could not reach the model in a usable form. Extracting data from an image is fundamentally an input-modality requirement, and only a model built to accept image input can satisfy it.