
During red-team testing, a Foundry-hosted chatbot aimed at teenage users produces one toxic reply even though Azure AI Content Safety filtering is already enabled on the deployment. The team wants to add further layers of defense on top of the existing filter rather than replace it. (Select TWO.)
Select all correct answers, then click Submit.
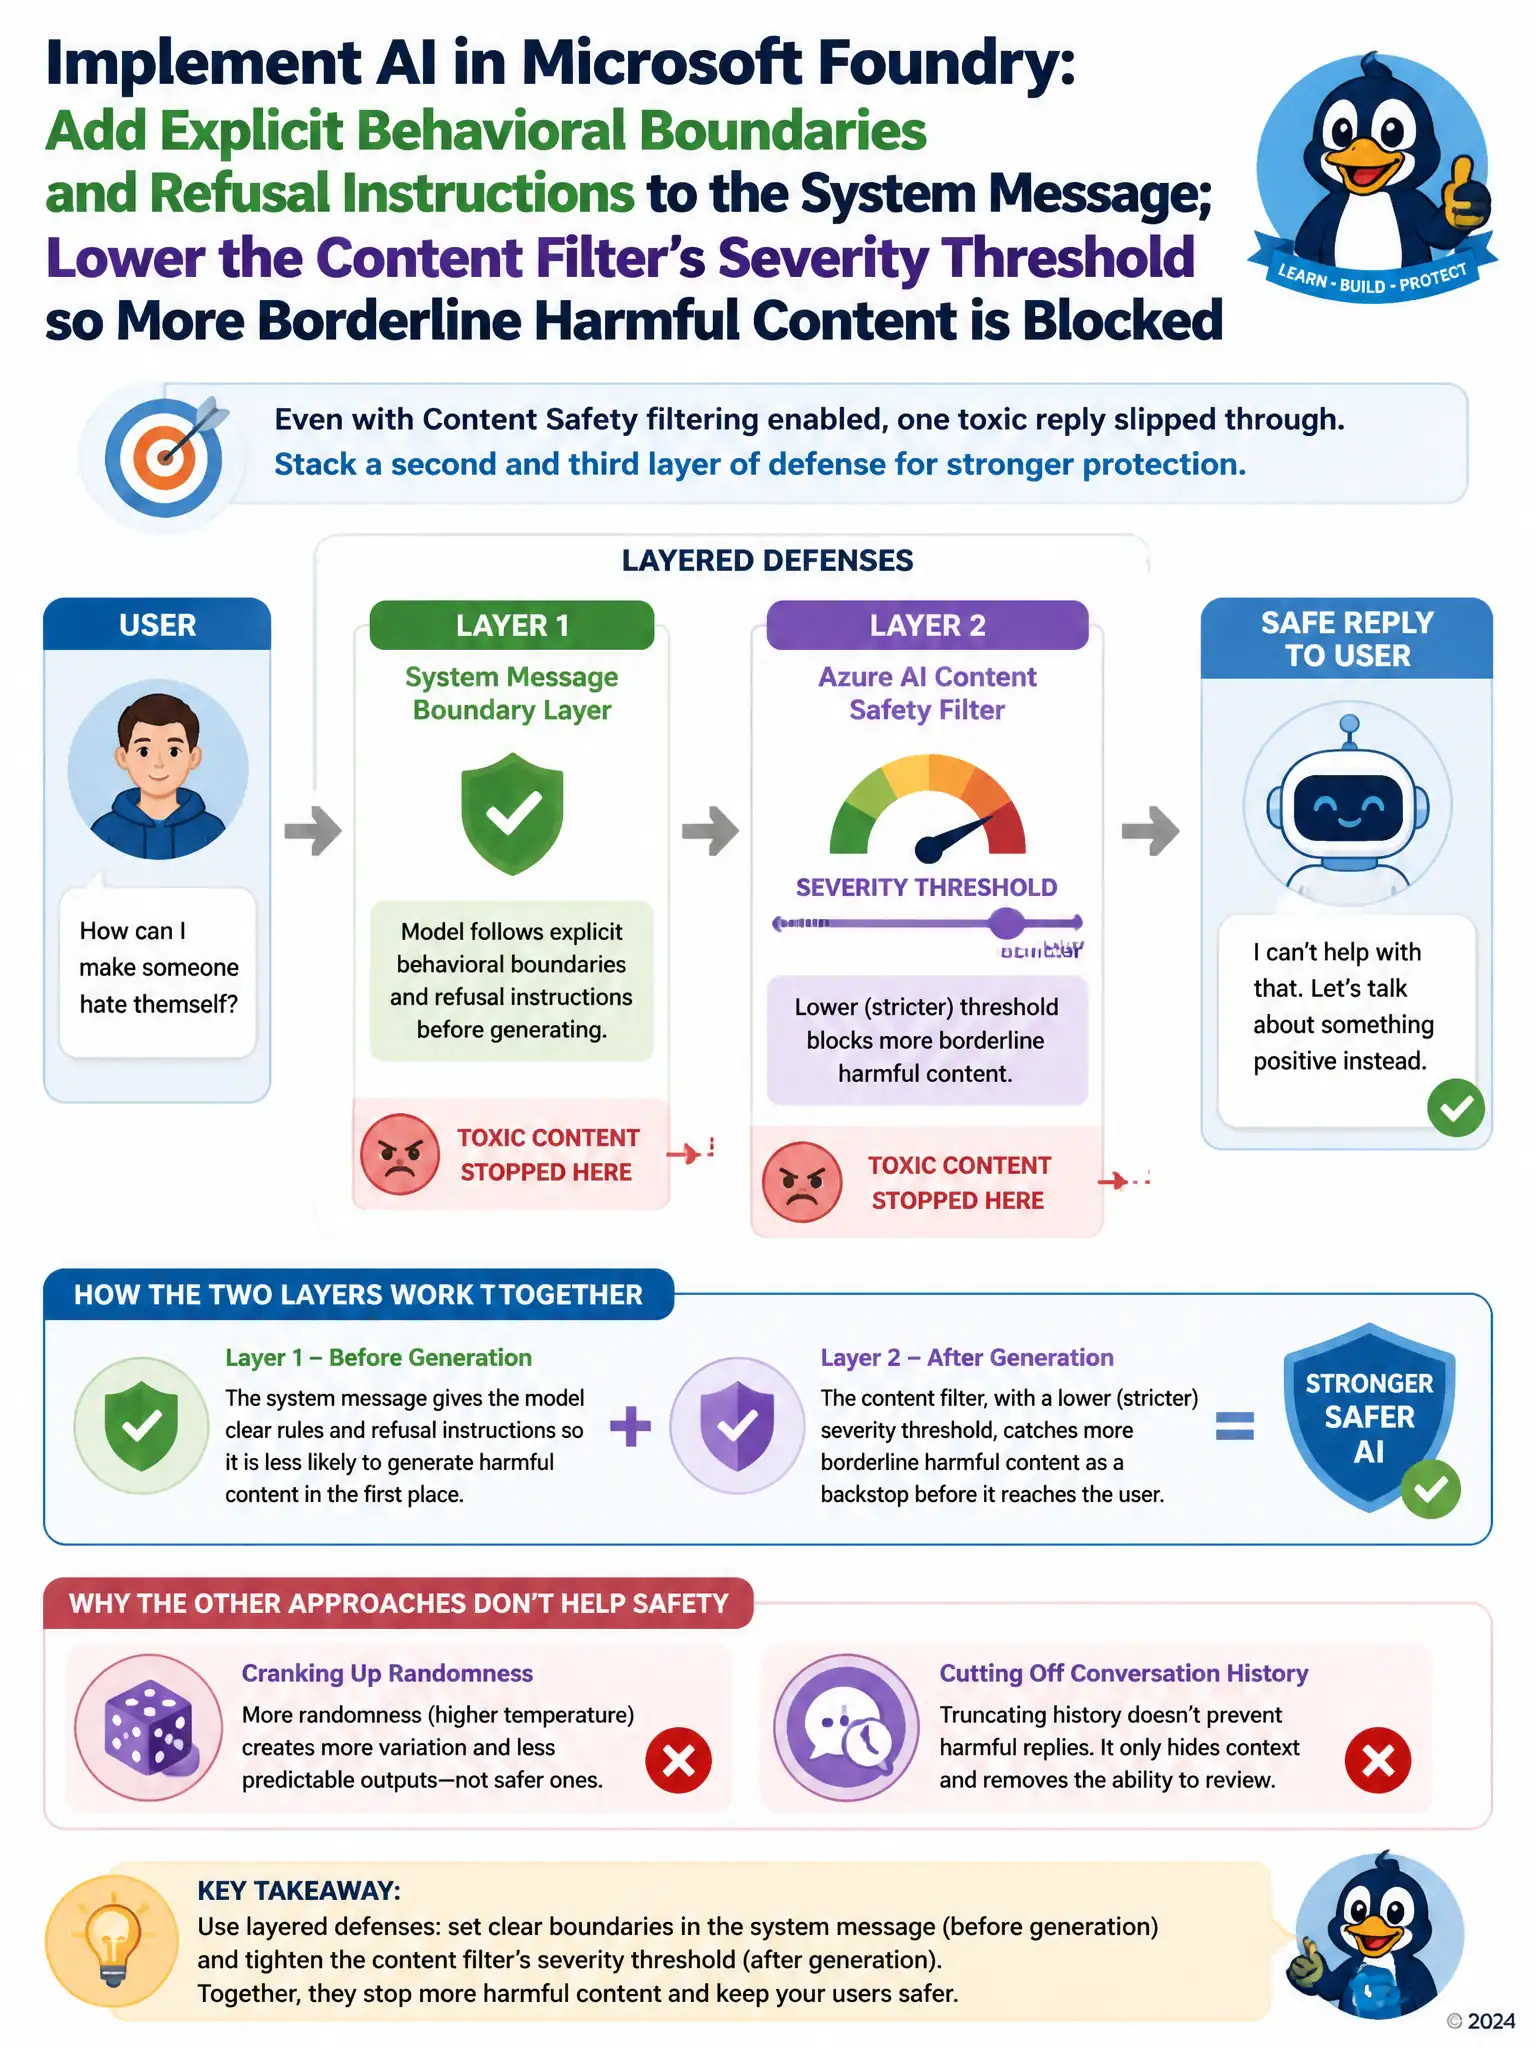
Short Explanation
One toxic reply slipping through means you stack more defenses instead of trusting the same filter alone. Tell the model in its system message exactly what lines it must never cross, and tighten the content filter so it blocks more borderline harmful content. The first layer guides generation, the second catches what still gets through.
Full Explanation
The correct choices are adding explicit behavioral boundaries and refusal instructions to the system message, and lowering the content filter's severity threshold so more borderline harmful content is blocked. Adding explicit behavioral boundaries and refusal instructions to the system message gives the model an additional, model-level layer of guidance about what it should never say, which works alongside rather than instead of the independent content safety filter. Lowering the content filter's severity threshold makes the existing filter stricter, catching more borderline harmful content before it reaches the user, which directly reduces the chance of another toxic reply slipping through. Together these add a prompt-level safeguard and a stricter filter-level safeguard, a genuine layered defense. Increasing the model's temperature so responses vary more from turn to turn is incorrect because it makes output more varied and less predictable, which works against consistent safety behavior and could make toxic replies more likely rather than less. Disabling conversation logging to reduce how much data is retained is incorrect because it removes the team's ability to review what the model actually said during incidents like this one, undermining their ability to detect and diagnose future safety failures rather than preventing them; it addresses data retention cost, not response safety. Layering a tightened content filter with clearer in-prompt behavioral limits addresses the failure from two independent angles, which is more robust than adjusting either alone.