
A team is adding a feature that suggests a one-sentence reply to a customer-support agent while the agent is actively typing. The suggestion must appear in well under a second, and the source transcripts are short, routine exchanges rather than complex multi-step problems. When comparing options in the Foundry model catalog, which factor should most influence their choice of model?
Select an answer to reveal the explanation.
Short Explanation
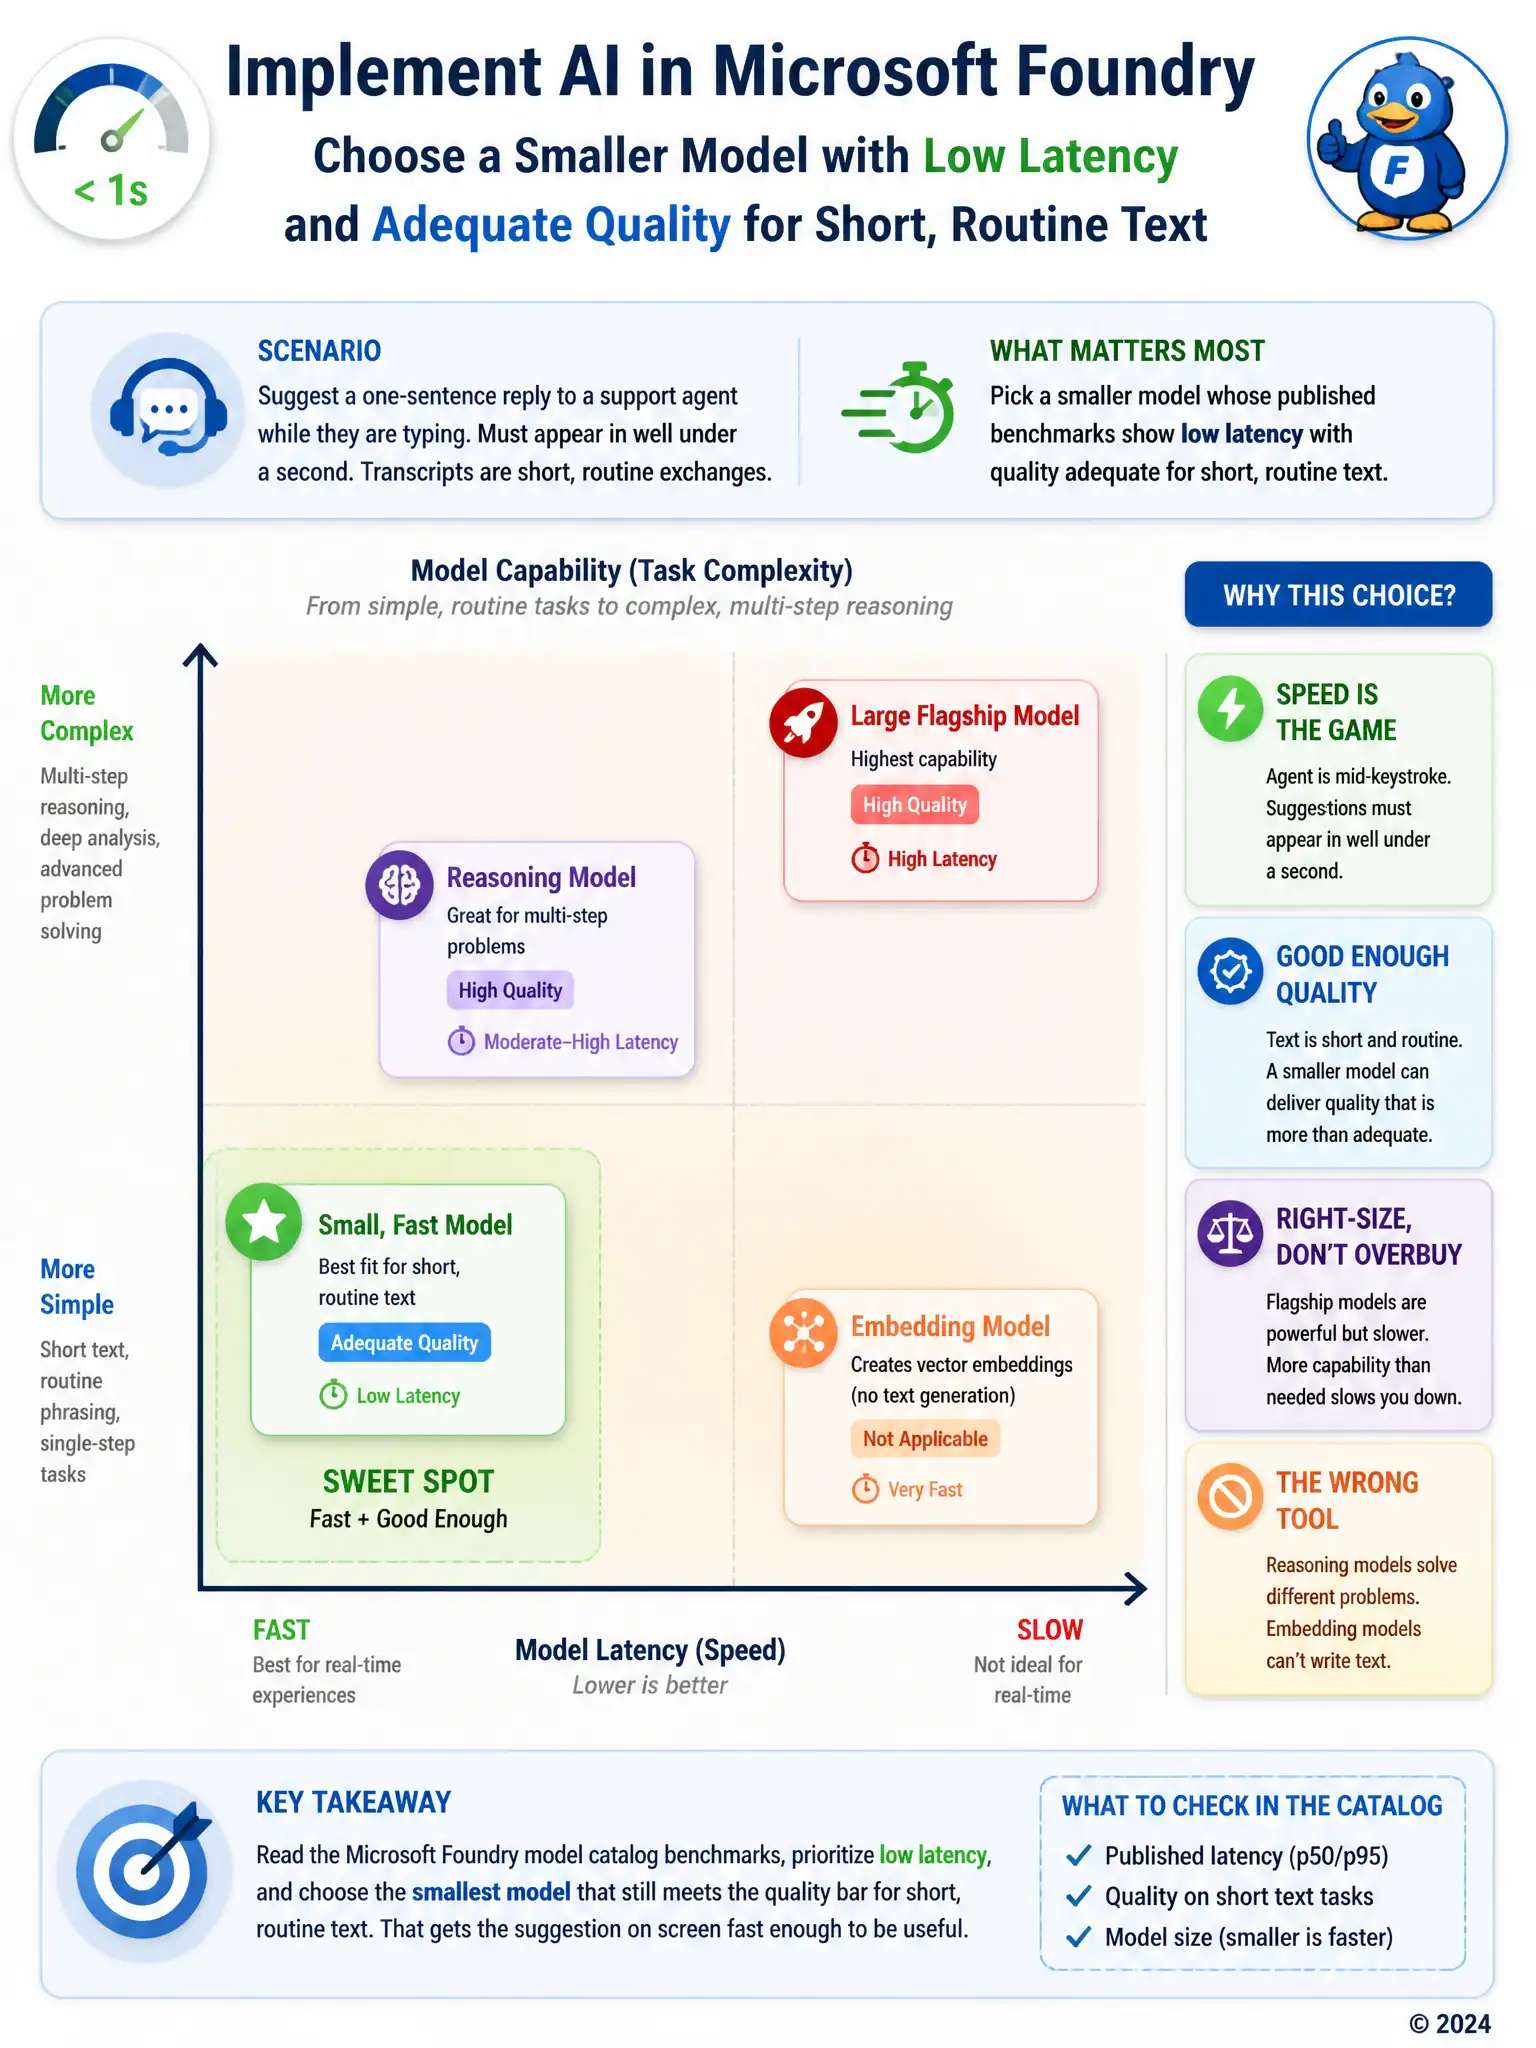
When you need a suggestion in well under a second, you pick the smaller model with low latency benchmarks and quality good enough for short, routine replies. You don't pay for heavyweight capability that slows you down, and you don't pick a model that can't generate text.
Full Explanation
The correct choice is the smaller model whose published benchmarks show low latency with quality adequate for short, routine text. The model catalog publishes latency and quality benchmarks alongside each model, and for a real-time typing-assist feature working on short, routine text, a smaller model that benchmarks fast with quality good enough for the task will meet the sub-second requirement without paying for capability the feature does not use. The largest, most capable flagship model chosen regardless of published latency benchmarks is incorrect because that model typically carries higher inference latency, and choosing it purely for maximum capability while ignoring the latency benchmark risks missing the sub-second target the feature depends on. The model benchmarked specifically for multi-step mathematical reasoning is incorrect because it is optimized for a different kind of task; strength in reasoning chains says nothing about response speed on short routine text and is irrelevant to this feature's needs. The embeddings-only model with no text-generation capability is incorrect because it produces vector representations, not generated reply text, so it cannot perform the core function of suggesting a written reply at all. Matching the model choice to the catalog's latency and task-fit benchmarks, rather than defaulting to the most powerful available model, is what keeps a real-time suggestion feature responsive while still producing usable output.