
A consumer app team enables Azure AI Content Safety filtering on their Foundry-hosted chat model. During testing, the filter blocks many benign messages that merely mention violence in a news-discussion context, frustrating users. The team wants to reduce these false blocks for the violence category without disabling protection against genuinely harmful content. What should they do?
Select an answer to reveal the explanation.
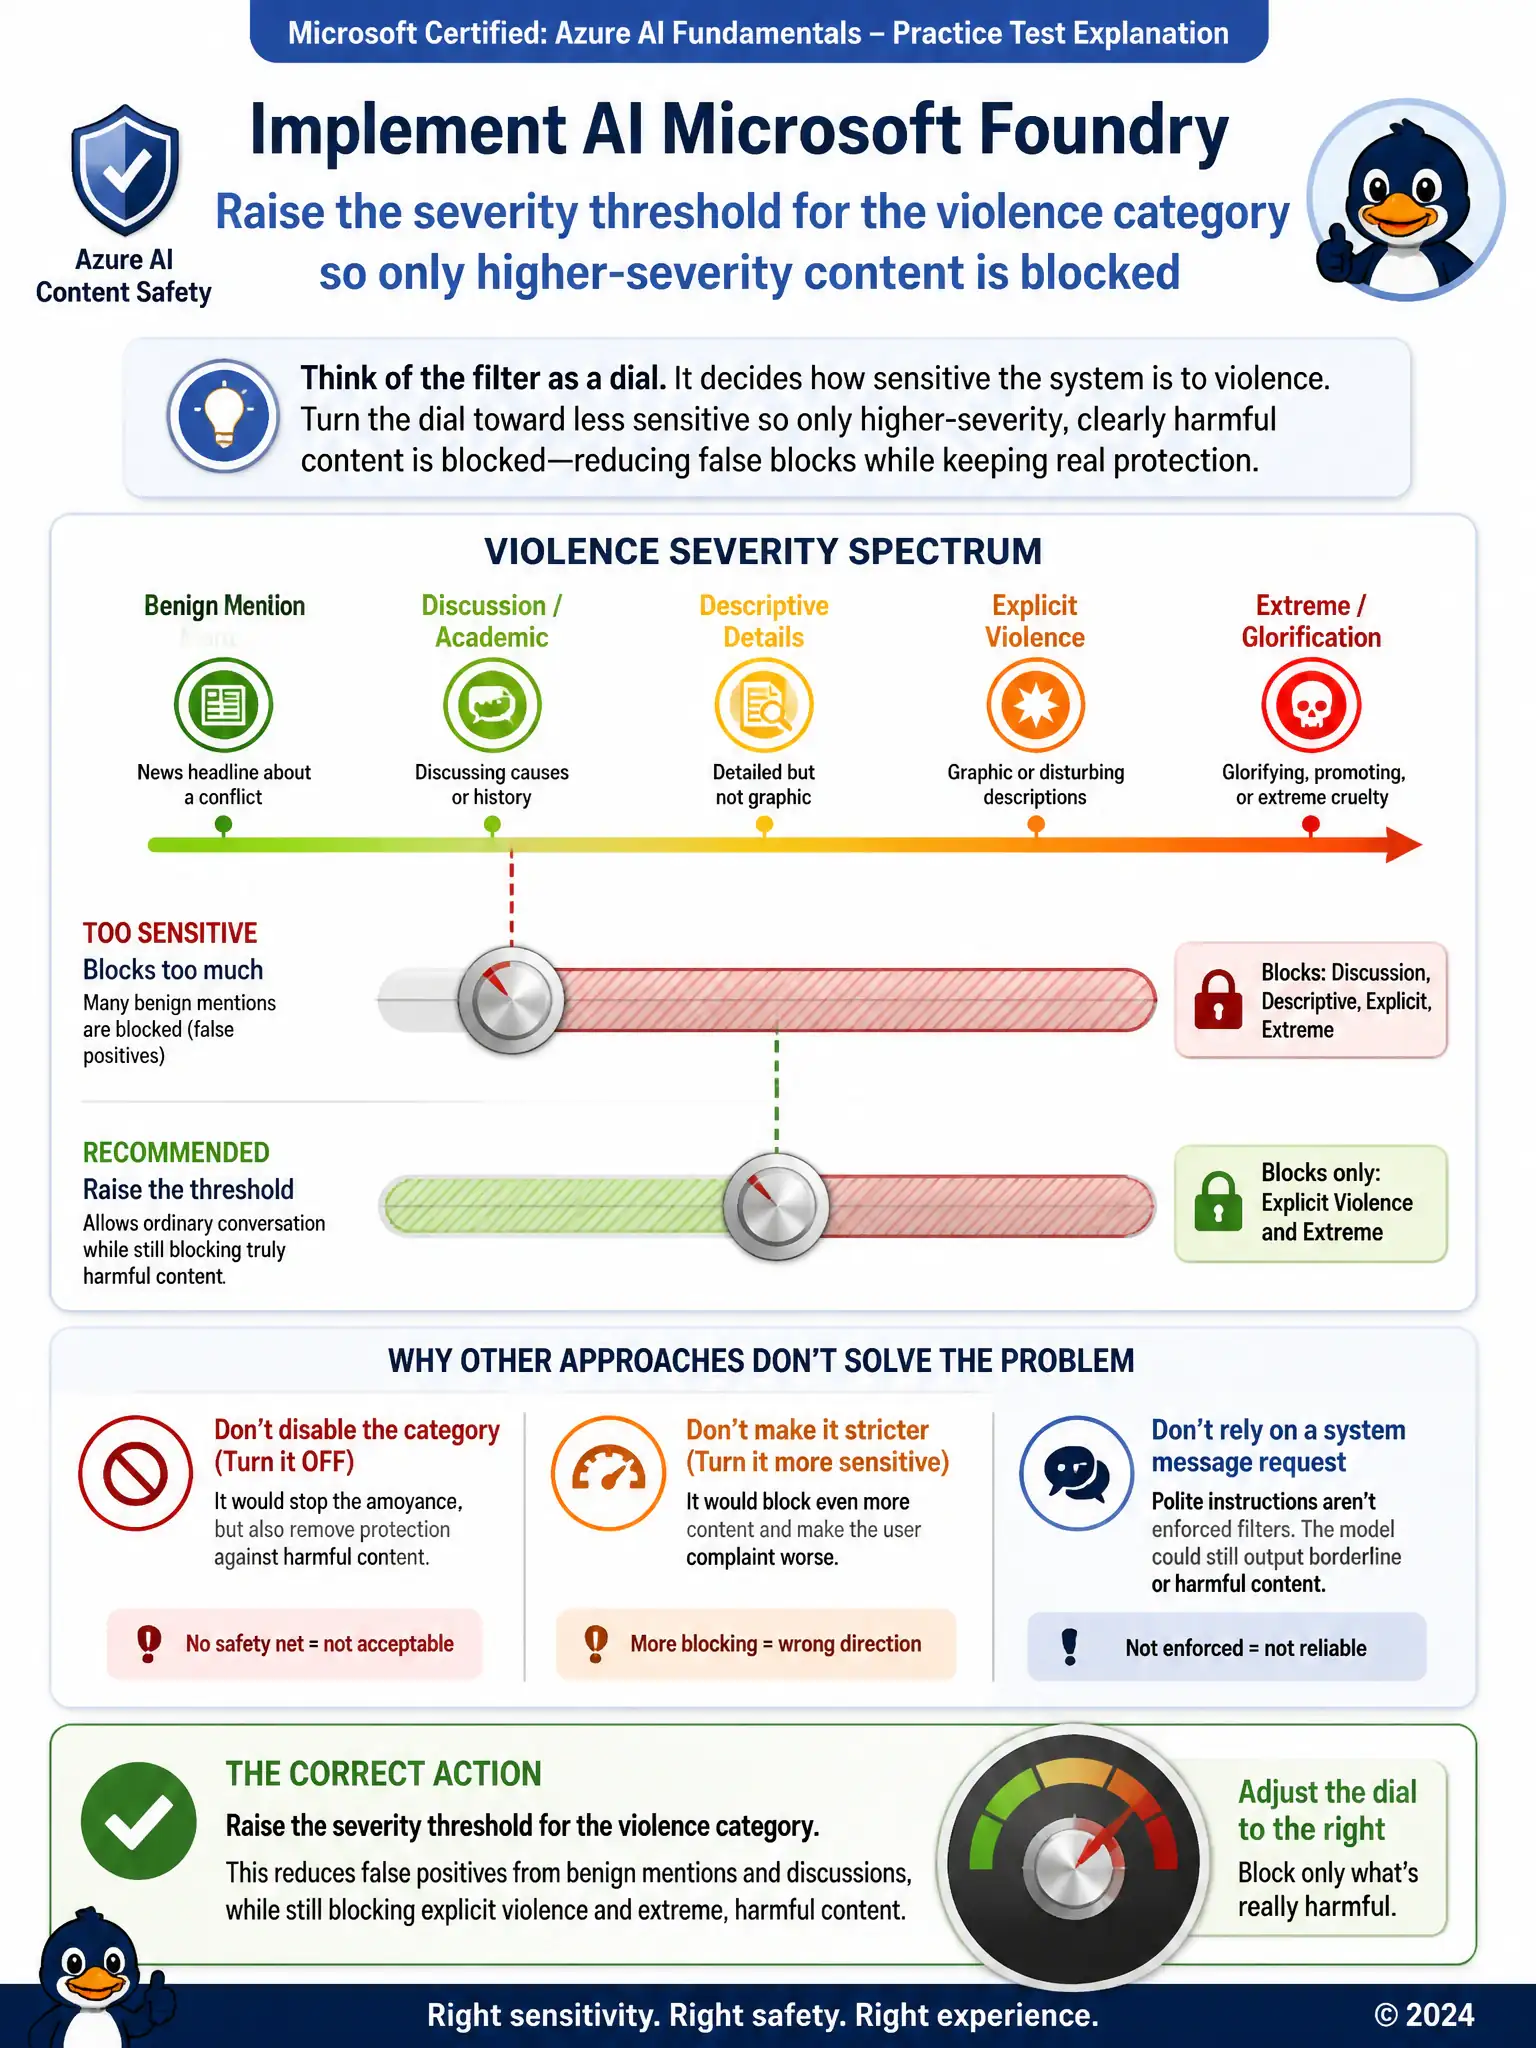
Short Explanation
Picture the violence filter as a dial. You need to raise the severity threshold so it only blocks clearly harmful content, letting news mentions pass while keeping real protection. Turning off violence filtering, lowering the violence severity threshold, or relying on a system message won't fix false blocks safely.
Full Explanation
Raising the severity threshold for the violence category means the filter only blocks content that scores at a higher severity level, letting lower-severity mentions such as a news reference to a conflict pass through while still catching genuinely graphic or harmful content at the top of the scale. This directly reduces false blocks without removing protection. Turning off content filtering for the violence category entirely is incorrect because disabling the category removes protection against actually harmful violent content along with the benign mentions, which overcorrects and reintroduces the risk the filter exists to manage. Lowering the severity threshold for the violence category so more content is blocked is incorrect because lowering the threshold makes the filter stricter, blocking even more content and worsening the exact problem the team is trying to fix. Replacing the content filter with a longer system message asking the model to avoid violent topics is incorrect because a system message is an instruction to the model, not an enforcement mechanism; it is not a substitute for the independently enforced content safety filter and does not reliably prevent the model from generating, or the filter from blocking, violent-sounding but harmless text. Tuning the severity threshold on the existing filter is the targeted fix: it keeps automated enforcement in place while recalibrating where the line between benign and harmful content sits for this specific category.