
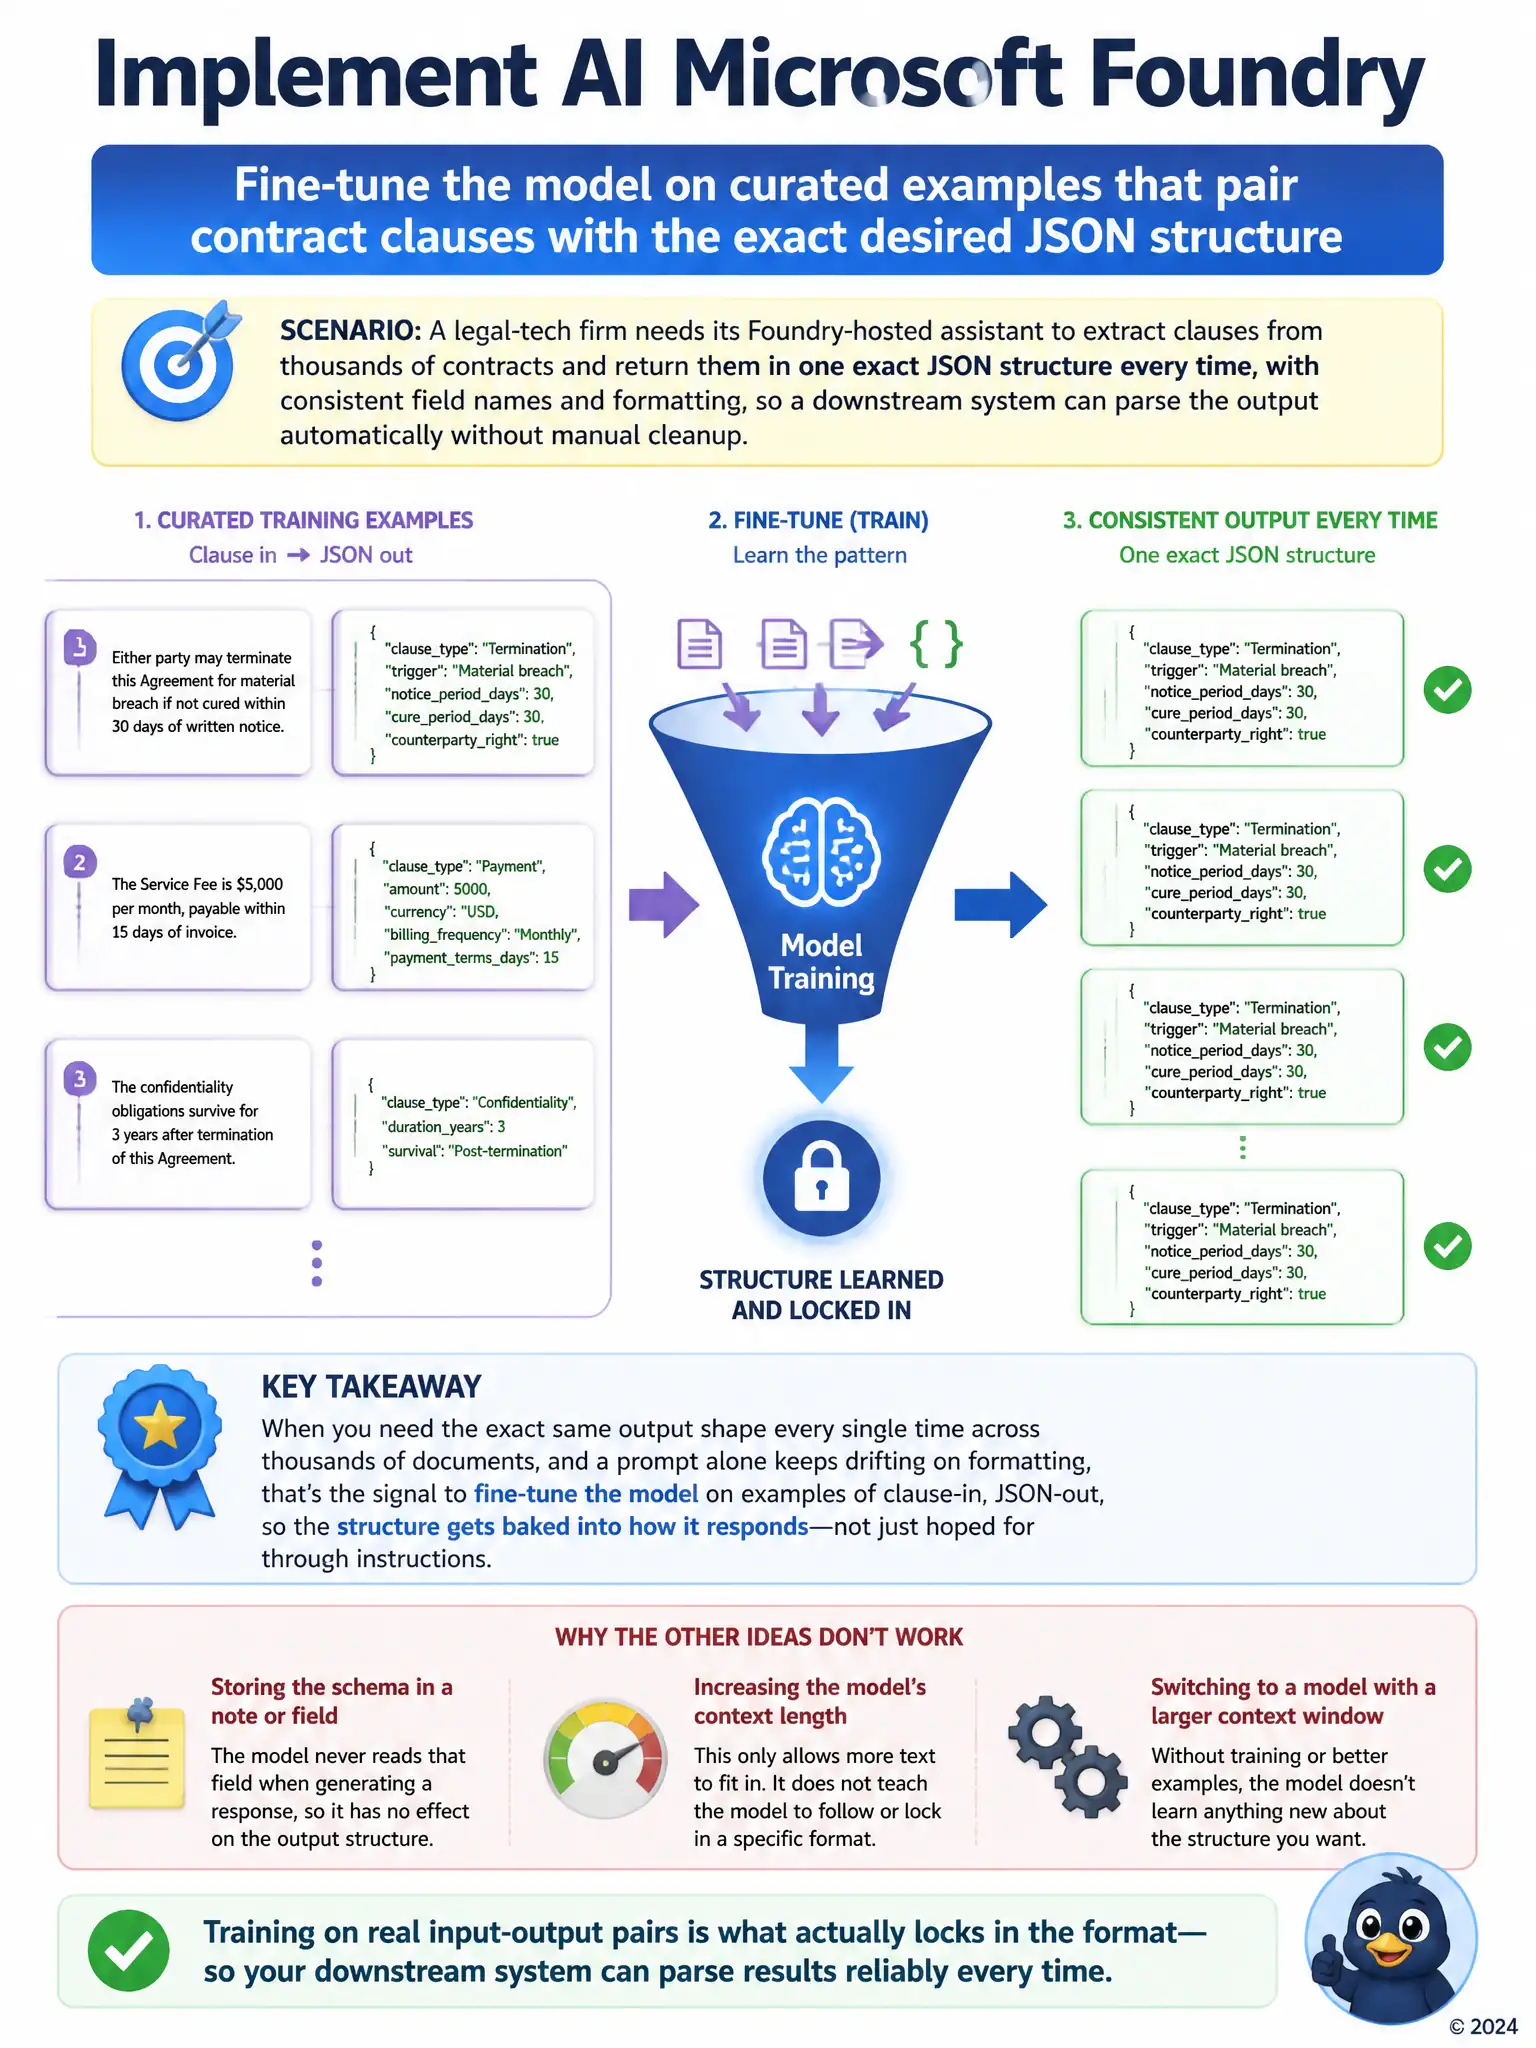
A legal-tech firm needs its Foundry-hosted assistant to extract clauses from thousands of contracts and return them in one exact JSON structure every time, with consistent field names and formatting, so a downstream system can parse the output automatically without manual cleanup.
Select an answer to reveal the explanation.
Short Explanation
When you need the exact same JSON shape every time across thousands of documents, you need to fine-tune the model on curated clause-to-JSON examples so the structure is baked into its responses. A note in the model description doesn't affect generation, and bigger token or context limits only handle more text, not consistent formatting.
Full Explanation
Fine-tuning on curated examples that pair real contract clauses with the exact target JSON structure teaches the model's weights to consistently reproduce that structure across thousands of varied documents, which is what a downstream system parsing automatically requires. The model description field is metadata for the deployment, not read by the model at inference time, so placing the desired schema there has no effect on the actual output format the model generates. Increasing the maximum token limit controls how much text can be processed or generated in one call; it does not teach the model what output structure to follow, so longer clauses fitting in context does nothing to fix inconsistent JSON formatting. Switching to a model with a larger context window only changes how much text the model can consider at once, and leaving the prompt unchanged means the model still has no reinforced pattern for the exact output structure, so formatting will remain inconsistent across the thousands of contracts. Fine-tuning directly targets the consistency problem the firm is describing.