
Before launching a Foundry-hosted assistant that answers questions using a retrieved knowledge base, a QA team wants a repeatable, quantitative check of whether answers are actually supported by the retrieved documents and whether the writing reads clearly, across a representative set of test questions rather than a handful of examples someone happens to glance at.
Select an answer to reveal the explanation.
Short Explanation
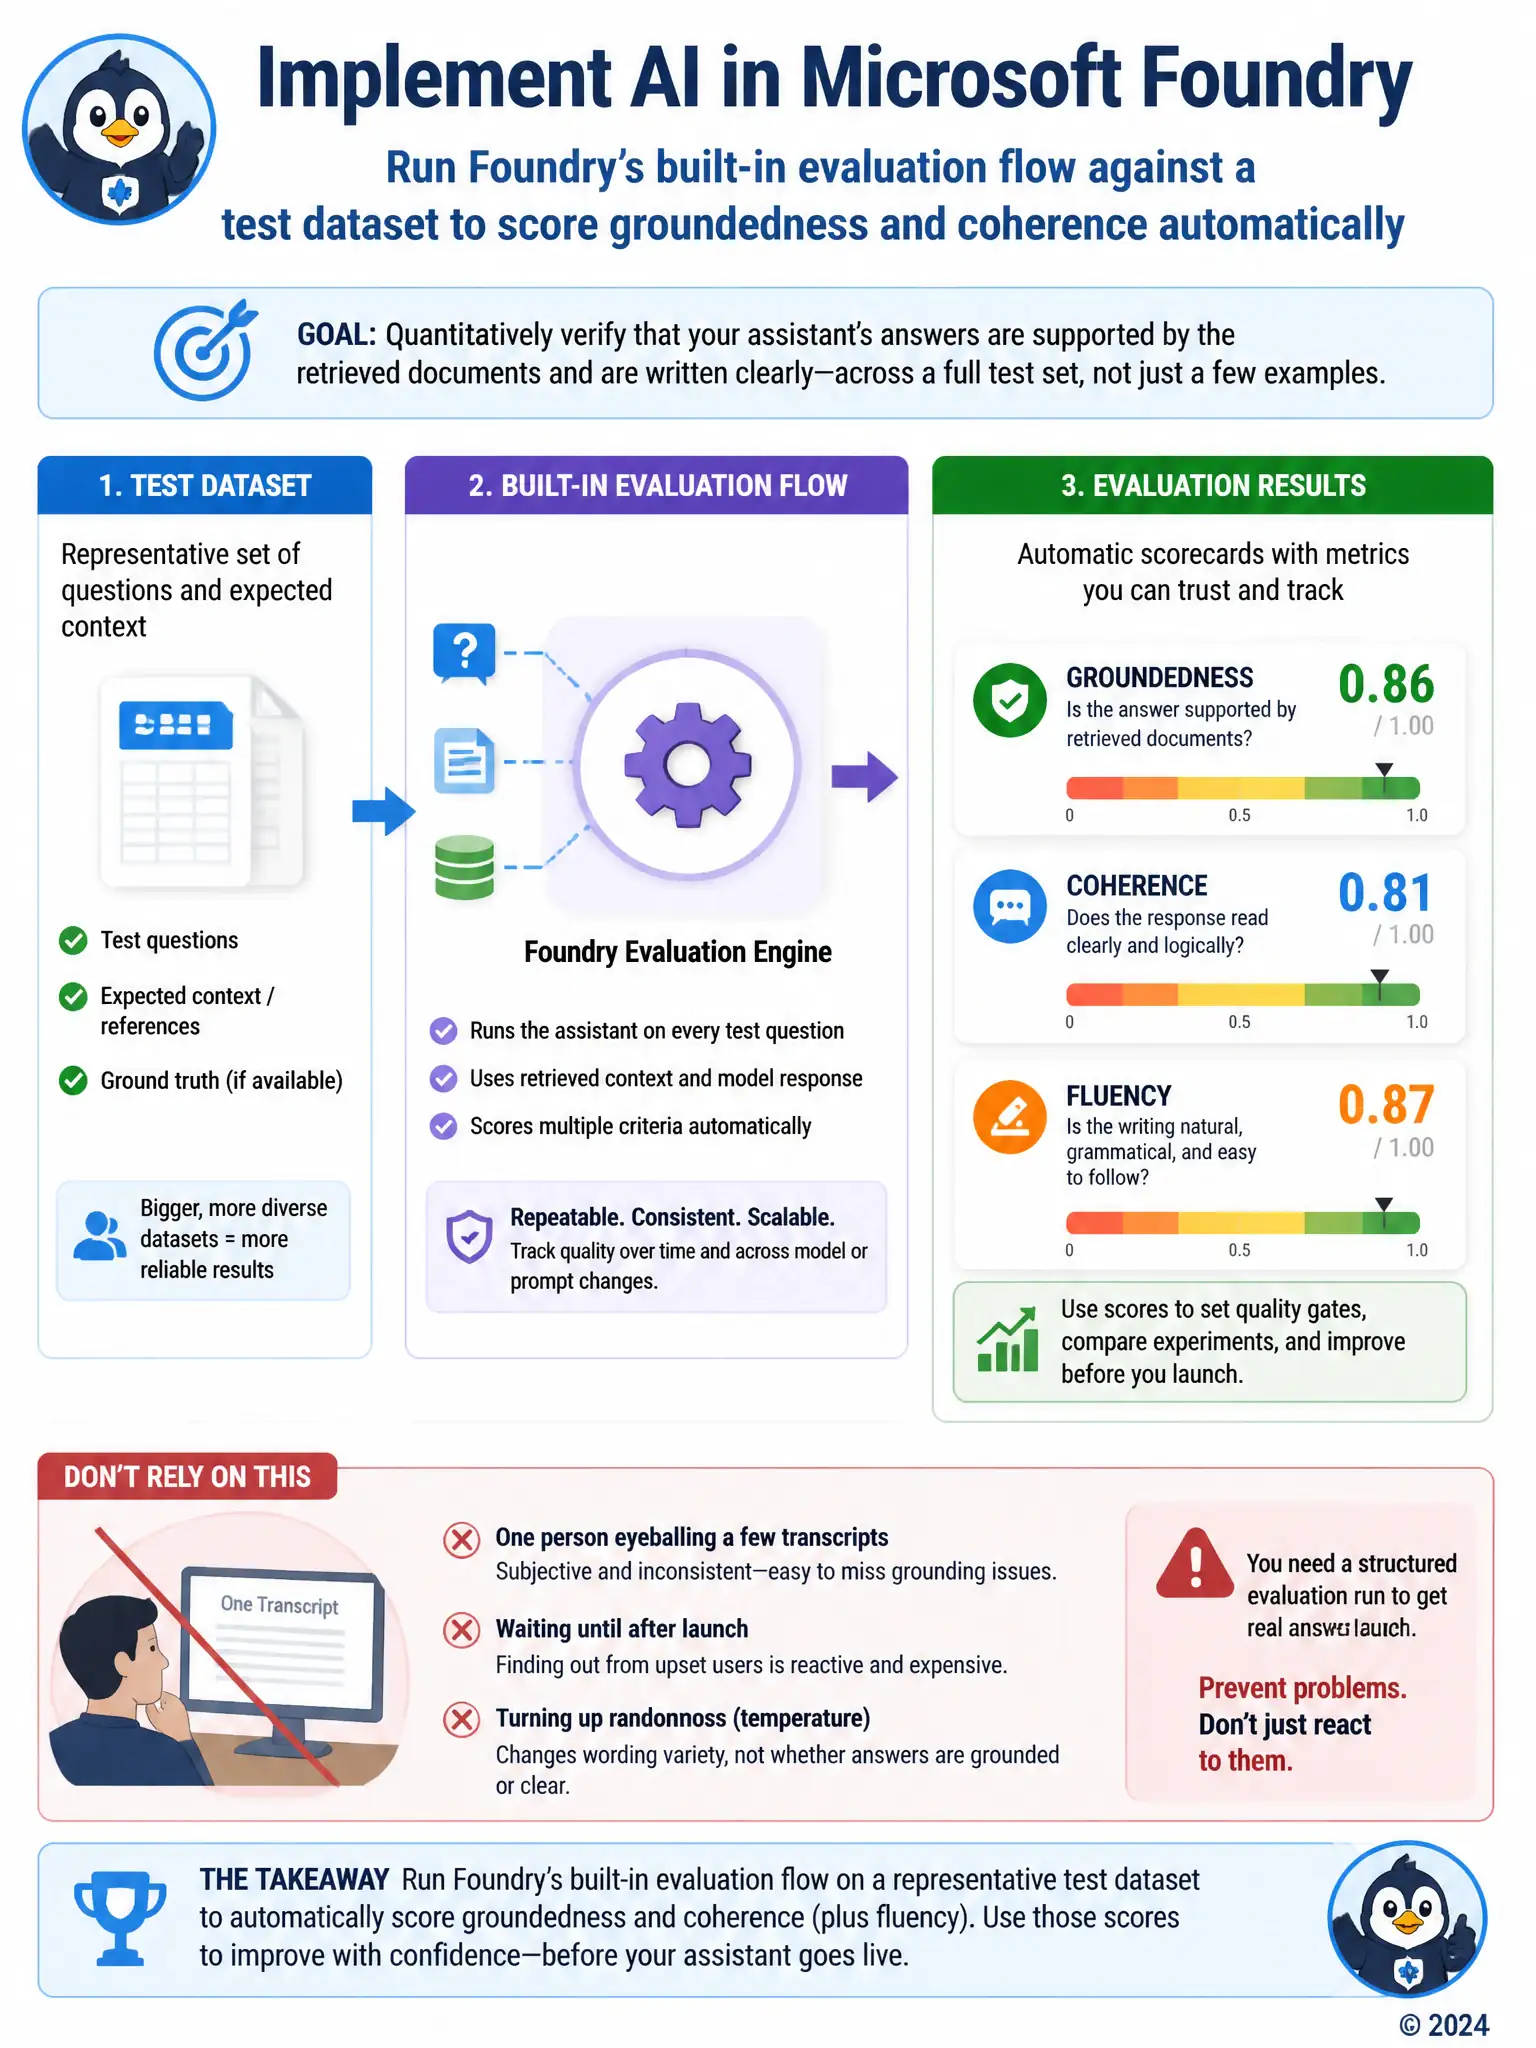
If you want to know whether answers are backed by retrieved documents and whether writing holds together, you need more than one person eyeballing a few transcripts. Run the built-in evaluation flow against a test dataset to score groundedness and coherence automatically, giving you numbers you can track and compare. Waiting for complaints after launch is reactive, and raising temperature doesn't make answers more grounded or clearer; it only changes wording variation.
Full Explanation
The correct approach is the built-in evaluation flow against a test dataset to score groundedness and coherence automatically. Foundry provides built-in evaluation tooling that runs a model against a prepared test dataset and produces quantitative scores for metrics such as groundedness, which measures whether an answer is supported by the retrieved content, and coherence, which measures how clearly the response reads, giving the quality assurance team a repeatable, scaled check before launch. Relying solely on one team member manually spot-checking a handful of transcripts before launch is incorrect because one person skimming a handful of transcripts is subjective, does not scale to a representative test set, and can easily miss systemic problems that only appear across many varied questions. Waiting until after launch and relying on customer complaint tickets to surface problems is incorrect because waiting for customer complaints means real users are exposed to ungrounded or unclear answers first, which is exactly the outcome the pre-launch check is meant to prevent. Increasing the model's temperature setting so responses become more consistent is incorrect because temperature controls how much randomness the model introduces when generating text, it has no relationship to whether an answer is factually grounded in retrieved documents or how coherent the writing is, and adjusting it does not substitute for measurement. Running a structured evaluation against a test dataset is the direct way to get the quantitative, repeatable check the team needs.