
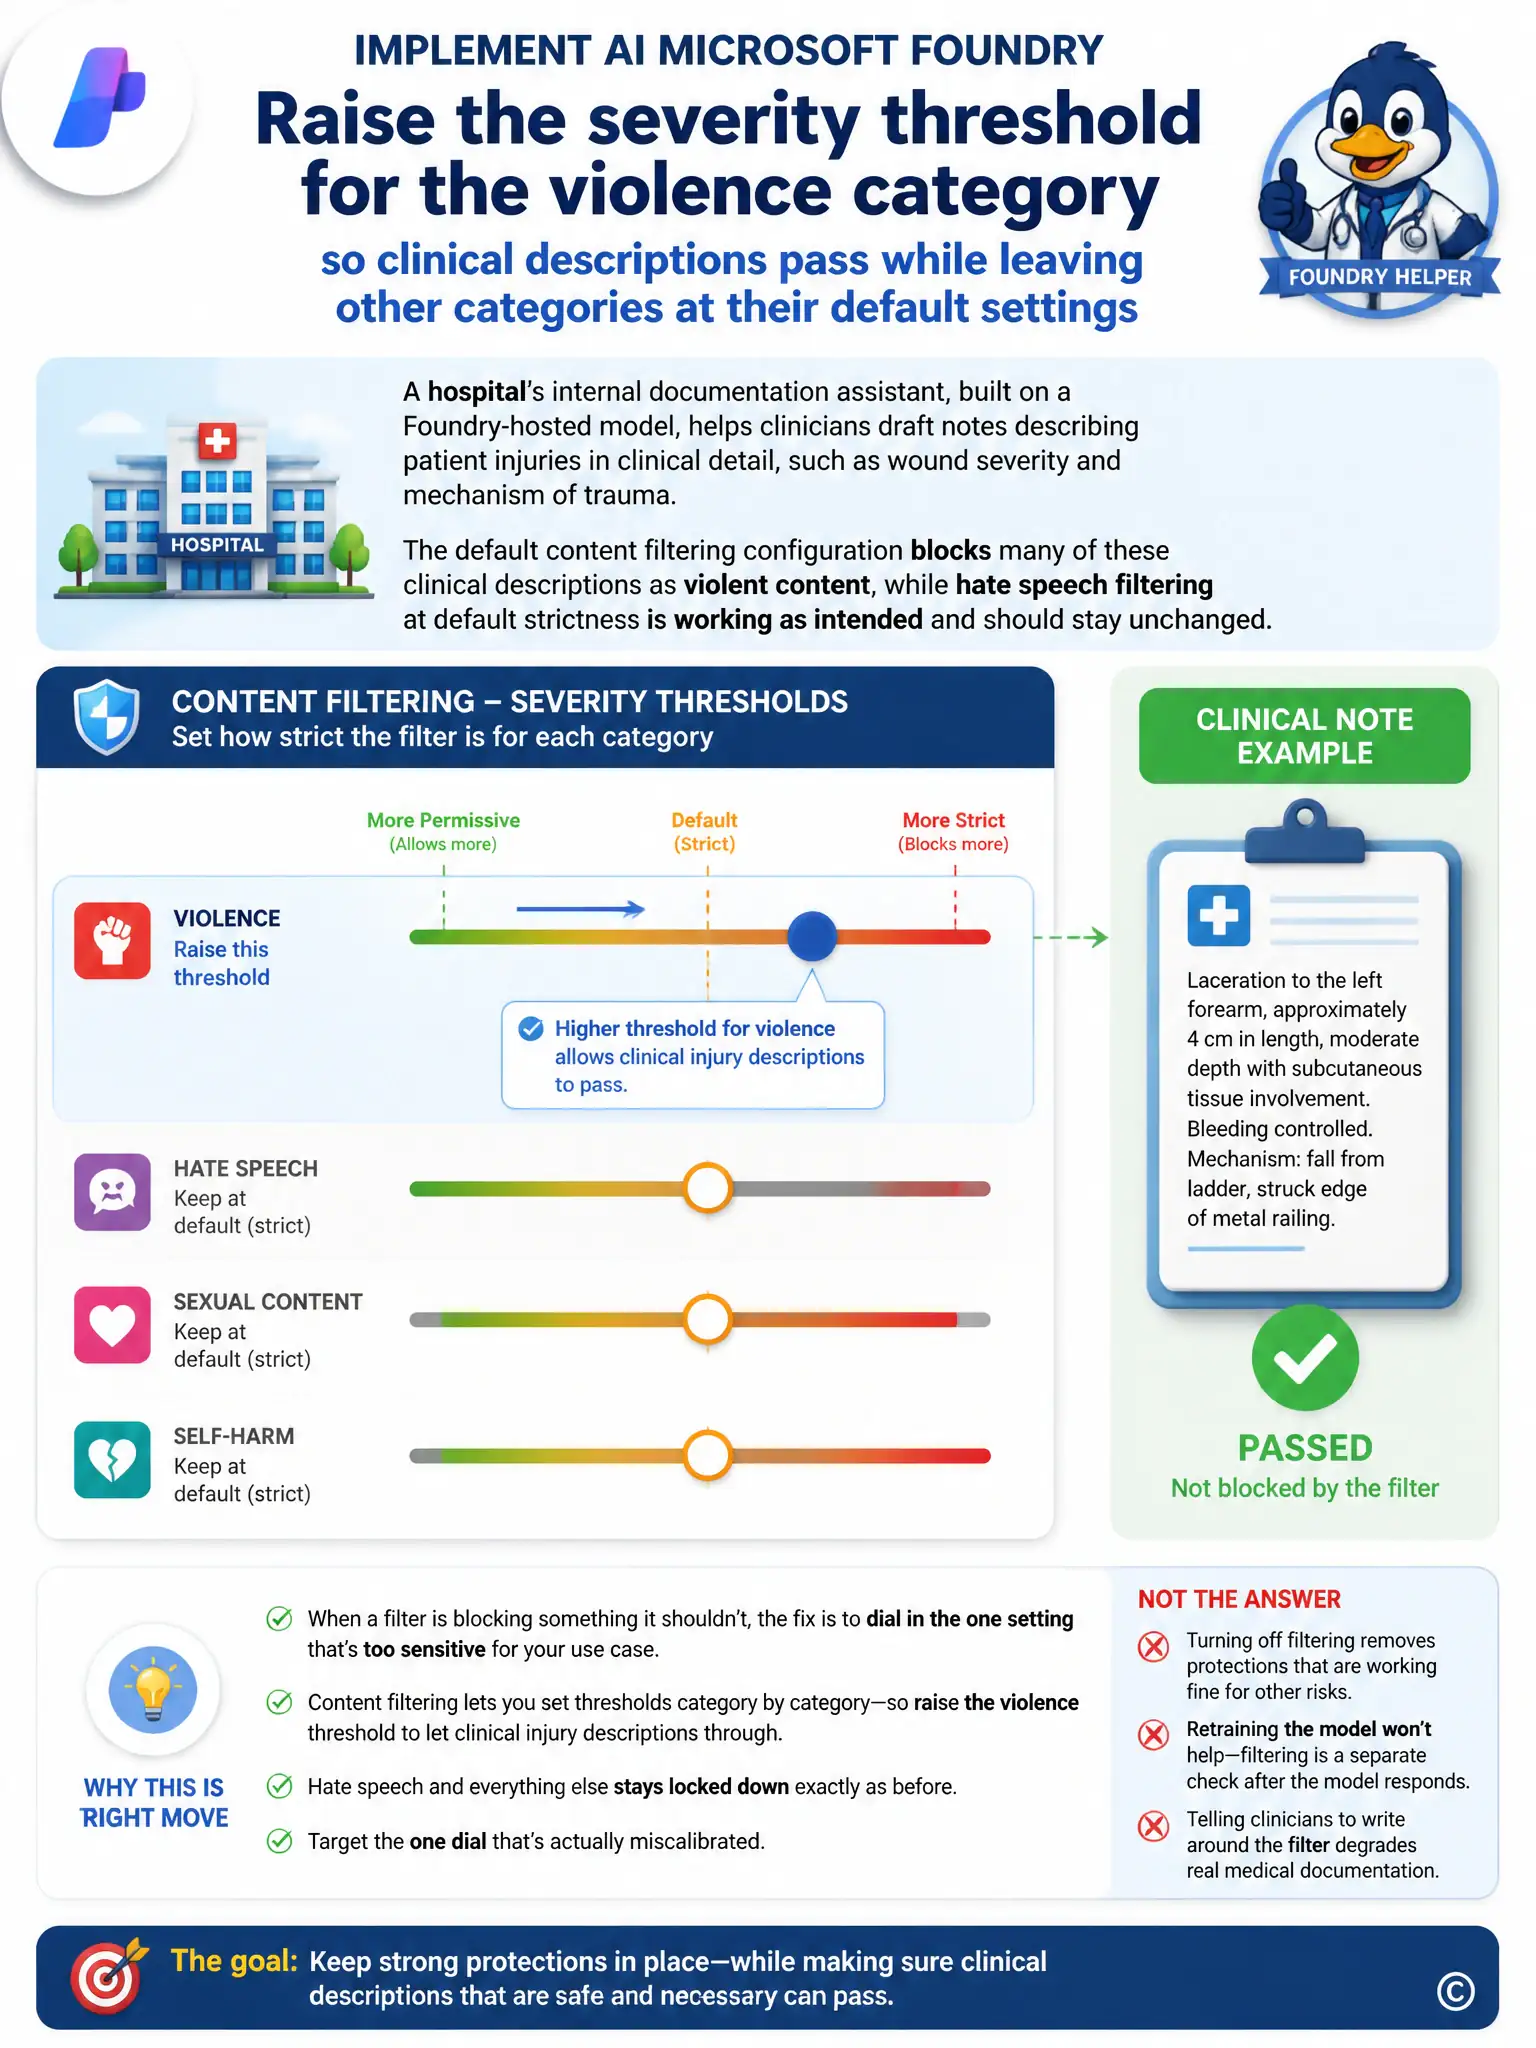
A hospital's internal documentation assistant, built on a Foundry-hosted model, helps clinicians draft notes describing patient injuries in clinical detail, such as wound severity and mechanism of trauma. The default content filtering configuration blocks many of these clinical descriptions as violent content, while hate speech filtering at default strictness is working as intended and should stay unchanged.
Select an answer to reveal the explanation.
Short Explanation
When a filter blocks legitimate clinical injury notes, you don't rip out all protections. You raise the violence-category severity threshold just enough to let those descriptions pass, while leaving hate speech and other filters at default. That targets the one miscalibrated setting.
Full Explanation
The correct answer is the targeted threshold adjustment: raise the severity threshold for the violence category so clinical descriptions pass while leaving other categories at their default settings. Foundry's content filtering lets teams configure severity thresholds independently per category, so the team can raise the threshold specifically for the violence category to allow legitimate clinical descriptions of injuries through, while leaving hate speech and other categories at their protective defaults. Disabling content filtering entirely is incorrect because it removes protection against every category, including hate speech and other harmful content that has nothing to do with the clinical documentation use case, which is far broader than the actual problem. Fine-tuning the model on medical texts is incorrect because it changes what the model tends to generate, not what the separate content filtering layer blocks after generation, so clinical descriptions would still be flagged by the unmodified violence filter. Asking clinicians to rephrase their notes so they avoid triggering the filters is incorrect because it asks them to avoid standard medical terminology to dodge a filter, compromising the accuracy and completeness of patient documentation, which is not an acceptable tradeoff in a clinical setting. Adjusting the specific category threshold is the targeted fix that solves the actual problem without weakening protection elsewhere.