
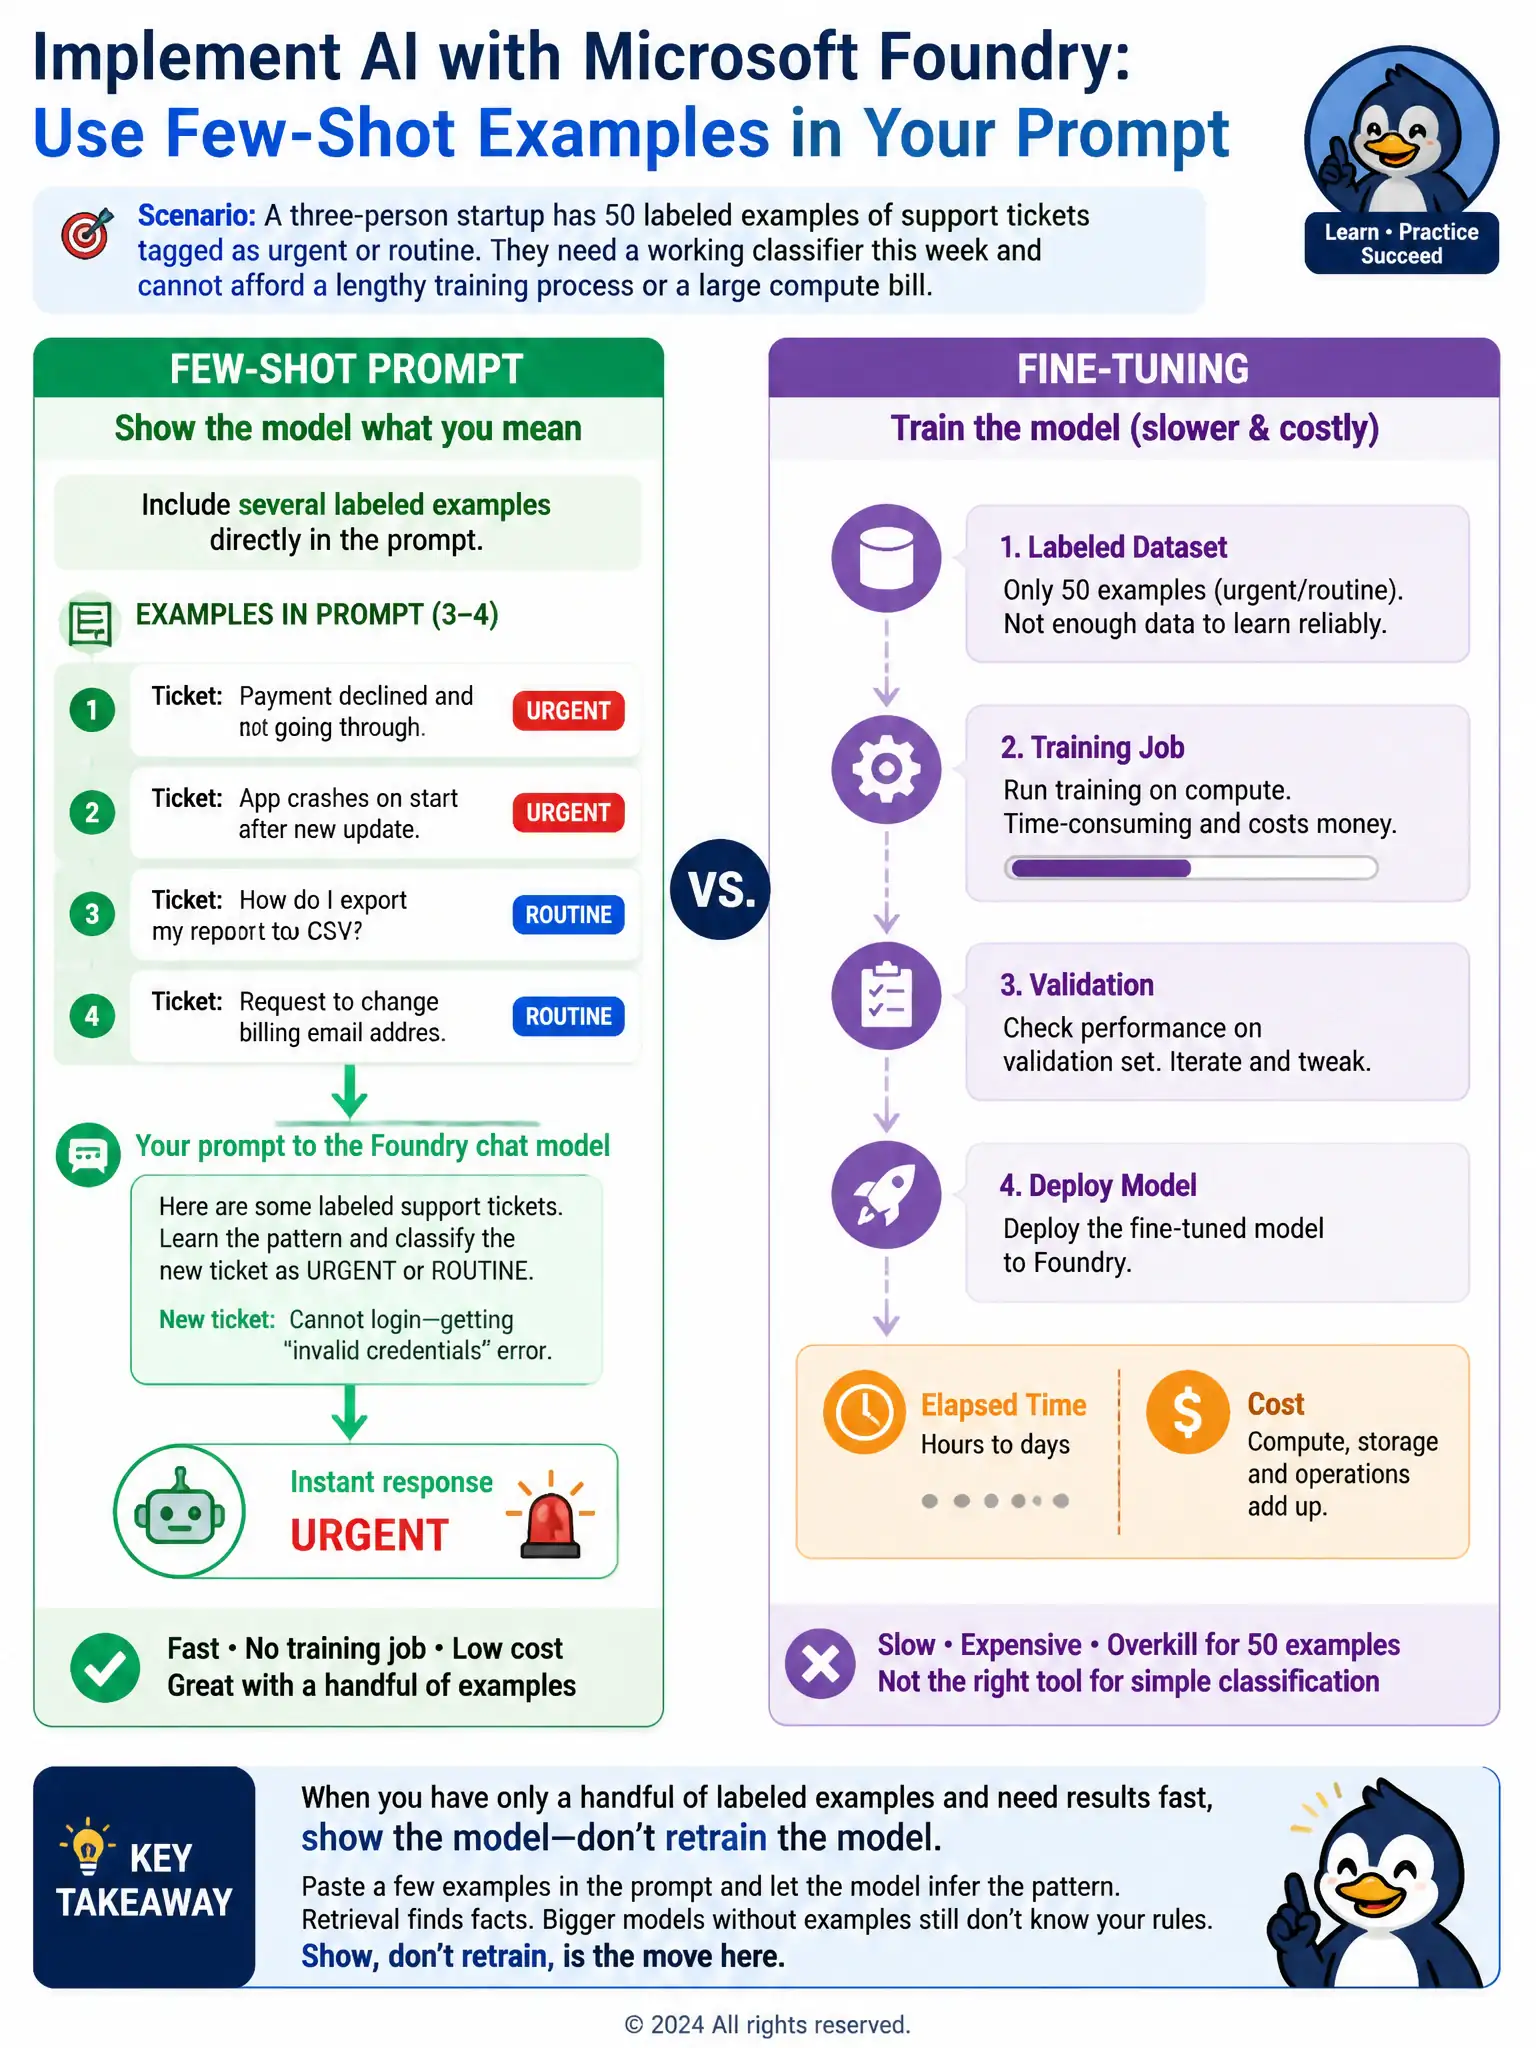
A three-person startup has 50 labeled examples of support tickets tagged as urgent or routine. The team needs a working classifier this week and cannot afford a lengthy training process or a large compute bill. They plan to build the feature using a Foundry-hosted chat model.
Select an answer to reveal the explanation.
Short Explanation
When you only have a handful of examples and no time or budget for a training run, the fastest path is showing the model what you mean right inside the prompt. Paste in a few tickets you've already labeled as urgent or routine, and the model picks up the pattern from those examples alone, no separate training job required. Show, don't retrain, is the move here.
Full Explanation
The correct choice is the few-shot prompting approach: include several labeled examples directly in the prompt so the model infers the urgent-versus-routine pattern immediately. With only 50 examples and a tight timeline, this gives results the same day, with no training job and no compute bill. The fine-tuning approach is incorrect because fine-tuning needs a proper training and validation split, incurs training compute cost, and 50 examples is a thin dataset for reliable fine-tuning, all of which fights the team's time and budget constraints. The vector-index retrieval approach is incorrect because a vector index and retrieval are built for finding and grounding answers in a large document collection, not for teaching a model a two-class labeling decision from a handful of examples. The largest-model swap is incorrect because swapping to a larger model without giving it any examples or guidance does not tell it what 'urgent' means for this company's tickets; a bigger model with an unchanged, example-free prompt will not reliably learn the distinction. Few-shot prompting matches the constraint of small data, small budget, and fast turnaround better than any of the alternatives.